The source files can be found in examples/.
Linear and group constraints
A mandate can cap the weight of a single name, keep each sector inside a band, keep one group larger than another, or forbid very small positions. PortfolioOptimisers.jl expresses each of these as a constraint on the JuMPOptimiser, and you can add them to any objective and prior. This page covers weight bounds, bounds on each member of a group and on the group's sum, and relative and sum constraints. Section 6 explains why thresholds and cardinality need a mixed-integer solver.
You name the assets and the groups once, in a UniverseSets, and every constraint refers to those names. The views of the prior examples use strings of the same "name op value" form.
Reach for these when a mandate limits what the portfolio holds: a 5% cap on a single name, a 20% ceiling on a sector, "healthcare at least as large as energy", "no position under 2%". All of them are convex except the thresholds and cardinality, which need a mixed-integer solver. You can use them with any objective, risk measure and prior. For limits that carry a cost, such as turnover, fees and tracking, see the other pages of this group.
using PortfolioOptimisers, CSV, TimeSeries, DataFrames, PrettyTables, Clarabel, StatsPlots, GraphRecipesresfmt = (v, i, j) -> begin return if j == 1 v else isa(v, AbstractFloat) ? "$(round(v*100, digits=3)) %" : v endend;1. Data
The data is one year of S&P 500 prices. We fit an empirical prior and set up one Clarabel solver.
X = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(X)pr = prior(EmpiricalPrior(), rd)slv = Solver(; name = :clarabel, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true))rf = 4.2 / 100 / 2520.00016666666666666672. Naming assets and groups
A UniverseSets maps each name to its members. The nx key holds every asset. The other keys are the groups that the constraints refer to, which here are sectors.
sets = UniverseSets(; dict = Dict("nx" => rd.nx, "tech" => ["AAPL", "AMD", "MSFT"], "financials" => ["BAC", "JPM"], "energy" => ["CVX", "XOM", "RRC"], "healthcare" => ["JNJ", "LLY", "MRK", "PFE", "UNH"], "staples" => ["KO", "PEP", "PG", "WMT"], "consumer" => ["BBY", "HD"], "industrial" => ["GE"]))UniverseSets
xkey ┼ String: "nx"
uxkey ┼ String: "ux"
tfkey ┼ String: "nf"
utfkey ┼ String: "uf"
cfkey ┼ String: "ncf"
ucfkey ┼ String: "ucf"
nikey ┼ String: "ni"
dict ┴ Dict{String, Vector{String}}: Dict("staples" => ["KO", "PEP", "PG", "WMT"], "financials" => ["BAC", "JPM"], "tech" => ["AAPL", "AMD", "MSFT"], "energy" => ["CVX", "XOM", "RRC"], "healthcare" => ["JNJ", "LLY", "MRK", "PFE", "UNH"], "nx" => ["AAPL", "AMD", "BAC", "BBY", "CVX", "GE", "HD", "JNJ", "JPM", "KO", "LLY", "MRK", "MSFT", "PEP", "PFE", "PG", "RRC", "UNH", "WMT", "XOM"], "industrial" => ["GE"], "consumer" => ["BBY", "HD"])
The baseline is a maximum-ratio portfolio with the default constraints only. We print its weight in each sector. On this year of data it holds two sectors and nothing else, so each constraint below has an effect you can see.
res_base = optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = pr, slv = slv)))sector_weight(w, g) = sum(w[i] for i in eachindex(w) if rd.nx[i] in sets.dict[g])sectors = ["tech", "financials", "energy", "healthcare", "staples", "consumer", "industrial"]pretty_table(DataFrame("Sector" => sectors, "Baseline" => [sector_weight(res_base.w, g) for g in sectors]); formatters = [resfmt], title = "Baseline max-ratio: sector exposure")Baseline max-ratio: sector exposure
┌────────────┬──────────┐
│ Sector │ Baseline │
│ String │ Float64 │
├────────────┼──────────┤
│ tech │ 0.0 % │
│ financials │ 0.0 % │
│ energy │ 34.02 % │
│ healthcare │ 65.979 % │
│ staples │ 0.001 % │
│ consumer │ 0.0 % │
│ industrial │ 0.0 % │
└────────────┴──────────┘3. Weight bounds: capping concentration
The simplest constraint is a bound on each weight, through wb. A WeightBounds with ub = 0.15 keeps every weight at or below 15%. The weights sum to one, so the optimiser must now hold at least seven names.
res_cap = optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = 0.0, ub = 0.15))))MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ Dict{Any, Any}: Dict{Any, Any}()
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 22
│ │ ├ num_constraints: 6
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ └ VariableRef in MOI.GreaterThan{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :dev_1, :k, :lw, :obj_expr, :ohf, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :sdp_corner, :so, :sr_ret, :variance_flag, :variance_risk_1, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┼ SquaredSOCRiskExpr()
│ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ ratio_alg ┼ SquareRootRatio()
│ corner ┴ nothing
fb ┴ nothing
4. A bound on each member against a bound on the group's sum
"A 15% floor on staples" can mean two different constraints. A WeightBoundsEstimator with a group key bounds each member of the group. A LinearConstraintEstimator bounds the sum of the group. Staples has four names here. WeightBoundsEstimator(lb = ["staples" => 0.15], ub = nothing) holds each of the four at 15% or more, which is at least 60% in total. LinearConstraintEstimator(val = ["staples >= 0.15"]) holds only their sum at 15% or more.
res_member = optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = pr, slv = slv, sets = sets, wb = WeightBoundsEstimator(; lb = ["staples" => 0.15], ub = nothing))))res_groupsum = optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = pr, slv = slv, sets = sets, lcse = LinearConstraintEstimator(; val = ["staples >= 0.15"]))))pretty_table(DataFrame("Interpretation" => ["per-member (each ≥ 15%)", "group-sum (total ≥ 15%)"], "Staples total" => [sector_weight(res_member.w, "staples"), sector_weight(res_groupsum.w, "staples")]); formatters = [resfmt], title = "Staples total for each form of the 15% floor")Staples total for each form of the 15% floor
┌─────────────────────────┬───────────────┐
│ Interpretation │ Staples total │
│ String │ Float64 │
├─────────────────────────┼───────────────┤
│ per-member (each ≥ 15%) │ 60.0 % │
│ group-sum (total ≥ 15%) │ 15.0 % │
└─────────────────────────┴───────────────┘Use the WeightBoundsEstimator form when the rule is about each name: "every position in this list at least x". Use the LinearConstraintEstimator form when the rule is about the total of a sector.
5. Linear group constraints: sums and relations
A LinearConstraintEstimator string combines group and asset names with +, -, numbers that multiply a name, and one of ==, <= and >=. With them you can cap a sum, "these two sectors together at most 60%", or relate two groups, "healthcare at least twice staples". We cap the two sectors of the baseline at 60% together, and hold tech at or below financials. At least 40% of the book must then go to sectors that the baseline did not hold.
res_sum = optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = pr, slv = slv, sets = sets, lcse = LinearConstraintEstimator(; val = ["healthcare + energy <= 0.6", "tech <= financials"]))))pretty_table(DataFrame("Sector" => sectors, "Baseline" => [sector_weight(res_base.w, g) for g in sectors], "Sum-capped" => [sector_weight(res_sum.w, g) for g in sectors]); formatters = [resfmt], title = "Sum cap (healthcare + energy ≤ 60%, tech ≤ financials)")Sum cap (healthcare + energy ≤ 60%, tech ≤ financials)
┌────────────┬──────────┬────────────┐
│ Sector │ Baseline │ Sum-capped │
│ String │ Float64 │ Float64 │
├────────────┼──────────┼────────────┤
│ tech │ 0.0 % │ 0.0 % │
│ financials │ 0.0 % │ 0.0 % │
│ energy │ 34.02 % │ 28.935 % │
│ healthcare │ 65.979 % │ 31.065 % │
│ staples │ 0.001 % │ 40.0 % │
│ consumer │ 0.0 % │ 0.0 % │
│ industrial │ 0.0 % │ 0.0 % │
└────────────┴──────────┴────────────┘6. Thresholds and cardinality need a mixed-integer solver
Two common constraints are not convex, so Clarabel cannot solve them alone.
- A threshold,
ThresholdEstimatorthrough theltandstkeywords, says "if you hold a name at all, hold at least x". A weight is then either zero or at least the floor. - A cardinality constraint, through the
cardandgcardekeywords, says "hold at most k names", and the solver must choose which names.
Both need a mixed-integer solver, for example Pajarito with Clarabel as the continuous solver and HiGHS as the mixed-integer solver. If you give a threshold to a continuous solver, the result carries a failed retcode and NaN weights. Cardinality and threshold sets up such a solver.
Every constraint on this page uses asset names. A mandate in factor names, such as "at most 10% momentum" or "no net exposure to value", is the same linear form over the factor exposures. Factor exposure constraints covers it.
7. Comparing the constraints
We print the weights of the four portfolios and plot them. The prior and the objective are the same in each, so only the constraint differs.
results = [res_base, res_cap, res_groupsum, res_sum]labels = ["Baseline", "Cap 15%", "Staples ≥ 15%", "Sum cap"]pretty_table(DataFrame(["Asset" => rd.nx, [labels[i] => results[i].w for i in eachindex(results)]...]); formatters = [resfmt], title = "Asset weights under each constraint")plot_stacked_bar_composition(results, rd; xticks = (1:length(labels), labels))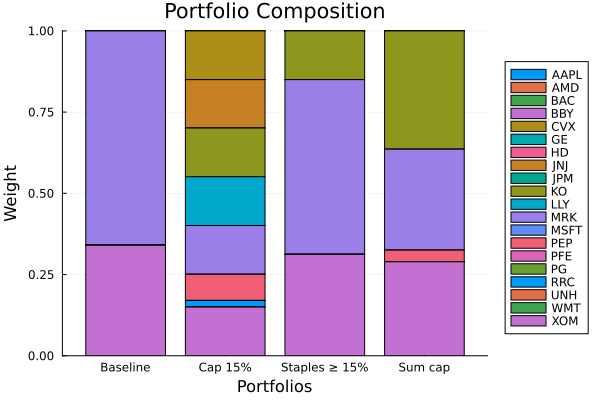
This page was generated using Literate.jl.