The source files can be found in examples/.
Higher moment estimation
Mean-variance optimisation reads only the first two moments of the returns. Asset returns are skewed and have fat tails, and risk measures such as NegativeSkewness and Kurtosis need estimates of the coskewness and cokurtosis tensors to account for that. These higher moments are harder to estimate than the covariance. The cokurtosis matrix is $N^2 \times N^2$. Its row for the pair (i, j) repeats its row for (j, i), so the raw estimate is singular at any window length. Denoising and sparsification help here, as they do for the covariance.
HighOrderPriorEstimator computes the higher moments. It wraps a prior for the mean and the covariance, and adds a Coskewness estimator in ske and a Cokurtosis estimator in kte. Each takes the same MatrixProcessing, with Denoise and LoGo, that the covariance page uses.
Reach for higher moment estimation when you optimise against a risk measure that reads the skew or the tails, such as NegativeSkewness, Kurtosis and their square-root forms, or when you build a Pareto surface over them. When you do, denoise the higher moments. The raw cokurtosis is numerically singular, and denoising lowers its condition number by many orders of magnitude. If your risk measures need no tensors, you do not need this page.
using PortfolioOptimisers, PrettyTables, LinearAlgebrahmmtfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v, digits=6))" : v endend;resfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v*100, digits=3)) %" : v endend;1. The data
We load 252 daily returns of 20 assets. For 20 assets the cokurtosis is a 400 by 400 matrix.
using CSV, TimeSeries, DataFramesX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(X)ReturnsResult
nx ┼ 20-element Vector{String}
X ┼ 252×20 Matrix{Float64}
nf ┼ nothing
F ┼ nothing
nb ┼ nothing
B ┼ nothing
ne ┼ nothing
E ┼ nothing
ts ┼ 252-element Vector{Date}
iv ┼ nothing
ivpa ┼ nothing
pnl ┼ AssetPanel
│ pf ┼ Vector{AbstractPanelField}: AbstractPanelField[]
│ amsk ┼ 252×20 AllTrueMask
│ emsk ┴ 252×20 AllTrueMask
2. High-order priors
We build three high-order priors that differ only in how they process V and the cokurtosis. V is the positive semidefinite matrix that the library builds from the negative eigenvalues of the slices of the coskewness, and kt is the cokurtosis matrix. The first prior applies only the default Posdef step, which replaces a matrix that is not positive definite with the nearest correlation matrix, rescaled to the same diagonal. The second also applies FixedDenoise. The third also applies the default Denoise and then LoGo sparsification. We then compare the condition numbers of V and of kt.
hopes = ["Vanilla" => HighOrderPriorEstimator(), "Denoise" => HighOrderPriorEstimator(; ske = Coskewness(; mp = MatrixProcessing(; dn = Denoise(; alg = FixedDenoise()))), kte = Cokurtosis(; mp = MatrixProcessing(; dn = Denoise(; alg = FixedDenoise())))), "LoGo" => HighOrderPriorEstimator(; ske = Coskewness(; mp = MatrixProcessing(; dn = Denoise(), alg = LoGo())), kte = Cokurtosis(; mp = MatrixProcessing(; dn = Denoise(), alg = LoGo())))]prs = [k => prior(pe, rd) for (k, pe) in hopes]3-element Vector{Pair{String}}:
"Vanilla" => HighOrderPrior
pr ┼ LowOrderPrior
│ X ┼ 252×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
kt ┼ 400×400 Matrix{Float64}
D2 ┼ 400×210 SparseArrays.SparseMatrixCSC{Int64, Int64}
L2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
S2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
sk ┼ 20×400 Matrix{Float64}
V ┼ 20×20 Matrix{Float64}
skmp ┼ MatrixProcessing
│ pdm ┼ Posdef
│ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ dn ┼ nothing
│ dt ┼ nothing
│ alg ┼ nothing
│ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
fpr ┴ nothing
"Denoise" => HighOrderPrior
pr ┼ LowOrderPrior
│ X ┼ 252×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
kt ┼ 400×400 Matrix{Float64}
D2 ┼ 400×210 SparseArrays.SparseMatrixCSC{Int64, Int64}
L2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
S2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
sk ┼ 20×400 Matrix{Float64}
V ┼ 20×20 Matrix{Float64}
skmp ┼ MatrixProcessing
│ pdm ┼ Posdef
│ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ dn ┼ Denoise
│ │ pdm ┼ Posdef
│ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ alg ┼ FixedDenoise()
│ │ args ┼ Tuple{}: ()
│ │ kwargs ┼ @NamedTuple{}: NamedTuple()
│ │ kernel ┼ typeof(AverageShiftedHistograms.Kernels.gaussian): AverageShiftedHistograms.Kernels.gaussian
│ │ m ┼ Int64: 10
│ │ n ┴ Int64: 1000
│ dt ┼ nothing
│ alg ┼ nothing
│ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
fpr ┴ nothing
"LoGo" => HighOrderPrior
pr ┼ LowOrderPrior
│ X ┼ 252×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
kt ┼ 400×400 Matrix{Float64}
D2 ┼ 400×210 SparseArrays.SparseMatrixCSC{Int64, Int64}
L2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
S2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
sk ┼ 20×400 Matrix{Float64}
V ┼ 20×20 Matrix{Float64}
skmp ┼ MatrixProcessing
│ pdm ┼ Posdef
│ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ dn ┼ Denoise
│ │ pdm ┼ Posdef
│ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ alg ┼ ShrunkDenoise
│ │ │ alpha ┴ Float64: 0.0
│ │ args ┼ Tuple{}: ()
│ │ kwargs ┼ @NamedTuple{}: NamedTuple()
│ │ kernel ┼ typeof(AverageShiftedHistograms.Kernels.gaussian): AverageShiftedHistograms.Kernels.gaussian
│ │ m ┼ Int64: 10
│ │ n ┴ Int64: 1000
│ dt ┼ nothing
│ alg ┼ LoGo
│ │ de ┼ Distance
│ │ │ power ┼ nothing
│ │ │ alg ┴ CanonicalDistance()
│ │ sim ┼ MaximumDistanceSimilarity()
│ │ pdm ┼ Posdef
│ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
fpr ┴ nothing
A condition number near $10^{15}$ means that the matrix is numerically singular, and an optimisation that reads it is ill-posed. In the table, compare the cokurtosis of the first prior with the denoised and the sparsified ones.
pretty_table(DataFrame(; :estimator => [k for (k, _) in prs], Symbol("cond(V) coskew") => [cond(p.V) for (_, p) in prs], Symbol("cond(kt) cokurt") => [cond(p.kt) for (_, p) in prs]); formatters = [hmmtfmt], title = "High-order moment conditioning") High-order moment conditioning
┌───────────┬────────────────┬───────────────────────┐
│ estimator │ cond(V) coskew │ cond(kt) cokurt │
│ String │ Float64 │ Float64 │
├───────────┼────────────────┼───────────────────────┤
│ Vanilla │ 129.142244 │ 1.8765248995980027e13 │
│ Denoise │ 41.276399 │ 16615.921465 │
│ LoGo │ 60.068167 │ 22716.974424 │
└───────────┴────────────────┴───────────────────────┘3. Visualising the high-order moments
plot_coskewness draws the coskewness matrix as a heatmap, and plot_cokurtosis draws the eigenvalues of the cokurtosis matrix. We draw each for the first prior and for the denoised prior. The matrix processing acts on V and not on the coskewness, so the two heatmaps are the same. The cokurtosis of the first prior has a block of eigenvalues near zero. FixedDenoise replaces the eigenvalues below its noise threshold with their mean, and the table of section 2 shows the condition number fall by many orders of magnitude.
using StatsPlots, GraphRecipesThe coskewness of the first prior.
plot_coskewness(prs[1].second, rd)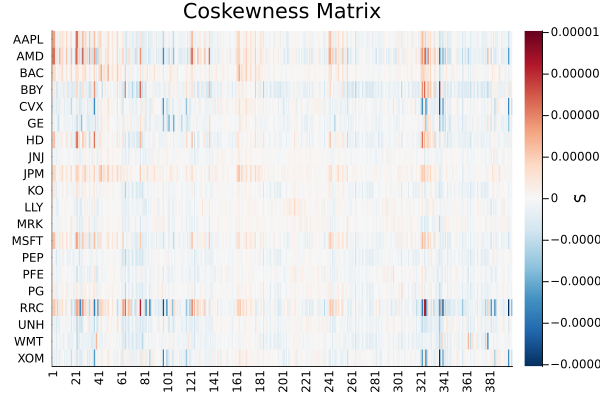
The coskewness of the denoised prior.
plot_coskewness(prs[2].second, rd)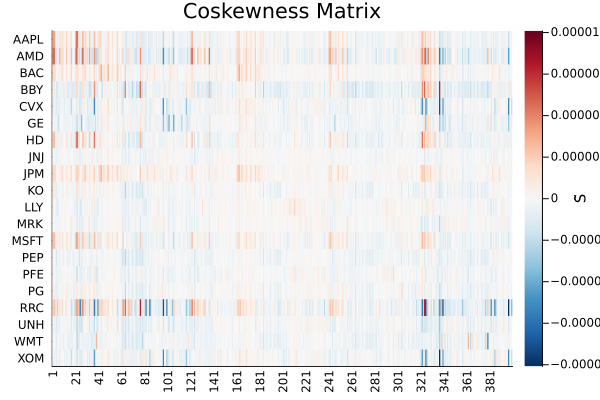
The eigenvalues of the cokurtosis of the first prior.
plot_cokurtosis(prs[1].second, rd)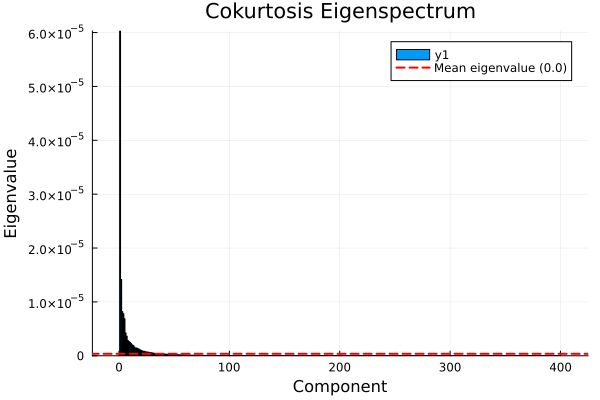
The eigenvalues of the denoised cokurtosis.
plot_cokurtosis(prs[2].second, rd)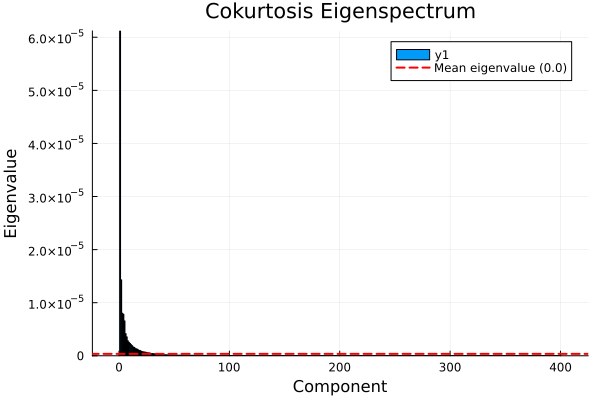
4. Minimum negative skewness and minimum kurtosis portfolios
We minimise two higher moment risk measures, NegativeSkewness and Kurtosis, with each high-order prior. The kurtosis constraint first adds the row of the pair (i, j) to the row of (j, i), and factors the smaller matrix that results. The repeated rows therefore never reach the solver. Denoising still changes the matrix that the solver reads, and with it the weights.
using Clarabelslv = Solver(; name = :clarabel1, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true))ress_sk = [k => optimise(MeanRisk(; r = NegativeSkewness(), obj = MinimumRisk(), opt = JuMPOptimiser(; pe = p, slv = slv))) for (k, p) in prs]ress_kt = [k => optimise(MeanRisk(; r = Kurtosis(), obj = MinimumRisk(), opt = JuMPOptimiser(; pe = p, slv = slv))) for (k, p) in prs]pretty_table(DataFrame(["Assets" => rd.nx; ["NSkew $k" => r.w for (k, r) in ress_sk]; ["Kurt $k" => r.w for (k, r) in ress_kt]]); formatters = [resfmt], title = "Minimum negative skewness and minimum kurtosis weights by prior") Minimum negative skewness and minimum kurtosis weights by prior
┌────────┬───────────────┬───────────────┬────────────┬──────────────┬──────────────┬───────────┐
│ Assets │ NSkew Vanilla │ NSkew Denoise │ NSkew LoGo │ Kurt Vanilla │ Kurt Denoise │ Kurt LoGo │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼───────────────┼───────────────┼────────────┼──────────────┼──────────────┼───────────┤
│ AAPL │ 0.0 % │ 0.0 % │ 0.655 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ AMD │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ BAC │ 15.073 % │ 21.071 % │ 21.574 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ BBY │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ CVX │ 5.941 % │ 2.999 % │ 0.0 % │ 0.0 % │ 0.842 % │ 7.005 % │
│ GE │ 0.0 % │ 0.0 % │ 0.0 % │ 1.548 % │ 1.061 % │ 6.205 % │
│ HD │ 0.0 % │ 0.0 % │ 0.0 % │ 2.616 % │ 2.614 % │ 3.462 % │
│ JNJ │ 16.214 % │ 10.15 % │ 17.774 % │ 40.295 % │ 40.486 % │ 33.57 % │
│ JPM │ 30.097 % │ 31.038 % │ 19.773 % │ 2.471 % │ 2.373 % │ 7.656 % │
│ KO │ 0.794 % │ 0.223 % │ 0.0 % │ 1.878 % │ 1.292 % │ 0.0 % │
│ LLY │ 7.921 % │ 7.467 % │ 15.945 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ MRK │ 14.537 % │ 18.374 % │ 23.329 % │ 25.182 % │ 23.836 % │ 15.976 % │
│ MSFT │ 7.633 % │ 0.11 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ PEP │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 2.652 % │ 0.94 % │
│ PFE │ 0.0 % │ 0.0 % │ 0.442 % │ 0.0 % │ 0.0 % │ 9.145 % │
│ PG │ 1.365 % │ 2.945 % │ 0.508 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ RRC │ 0.0 % │ 1.989 % │ 0.0 % │ 4.31 % │ 3.788 % │ 2.092 % │
│ UNH │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │ 0.0 % │
│ WMT │ 0.427 % │ 0.0 % │ 0.0 % │ 15.848 % │ 15.186 % │ 10.596 % │
│ XOM │ 0.0 % │ 3.635 % │ 0.0 % │ 5.852 % │ 5.87 % │ 3.352 % │
└────────┴───────────────┴───────────────┴────────────┴──────────────┴──────────────┴───────────┘We stack the weights that minimise the negative skewness into one bar per prior.
plot_stacked_bar_composition([r for (_, r) in ress_sk], rd; xticks = (1:length(ress_sk), [k for (k, _) in ress_sk]))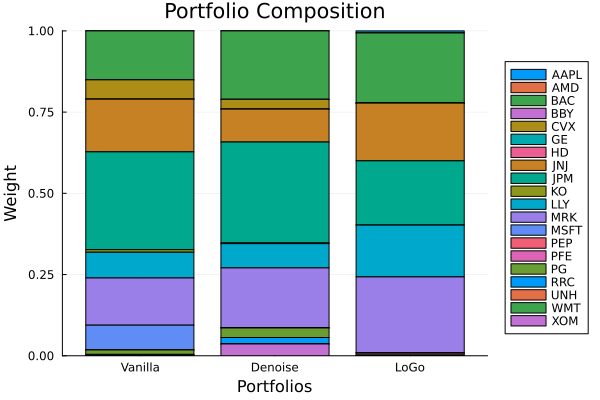
We do the same for the weights that minimise the kurtosis.
plot_stacked_bar_composition([r for (_, r) in ress_kt], rd; xticks = (1:length(ress_kt), [k for (k, _) in ress_kt]))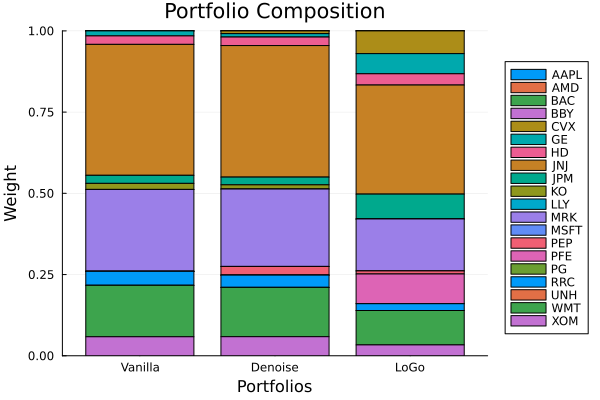
This page was generated using Literate.jl.