The source files can be found in examples/.
BrownianDistanceVariance and VarianceSkewKurtosis
Some risk measures respond to parts of the return distribution that the variance and the conditional value at risk do not measure. This page shows two of them.
BrownianDistanceVariancemeasures the dispersion of the portfolio returns with an upper bound on their distance variance, the Brownian distance covariance of the return series with itself. It is built from the absolute differences between the returns of every pair of days, not from their deviations about the mean.VarianceSkewKurtosiscombines the variance, the skewness and the kurtosis in one objective. Its model is a semidefinite relaxation with one large positive semidefinite matrix, so a first-order solver such as SCS suits it.
Reach for BrownianDistanceVariance when you want a measure of dispersion built from the differences between pairs of returns, not from their deviations about the mean. Reach for VarianceSkewKurtosis when the third and fourth moments of the portfolio return matter, for example when the assets have fat tails or skewed payoffs that mean-variance optimisation ignores.
BrownianDistanceVariancebuilds aT × Tdistance matrix inside the model, so the
number of extra variables grows with the square of the number of observations. This example uses 50 observations to keep the model small.
VarianceSkewKurtosisbuilds a large semidefinite problem. This example solves it
with SCS, and you can use another solver that handles large semidefinite problems. It also needs a HighOrderPriorEstimator, which computes the coskewness and the cokurtosis that the risk measure uses. This example uses the same 50 observations.
using PortfolioOptimisers, PrettyTables, DataFramesresfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v * 100, digits = 3)) %" : v endend;using CSV, TimeSeries, Clarabel, SCS1. The data: 50 observations
Both measures use the last 50 daily returns. The number of returns T sets the size of the model of BrownianDistanceVariance.
X = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 50):end]rd = prices_to_returns(X)pr = prior(EmpiricalPrior(), rd)slv = [Solver(; name = :clarabel1, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel2, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.95), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel3, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.9), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel4, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.85), check_sol = (; allow_local = true, allow_almost = true))]opt = JuMPOptimiser(; pe = pr, slv = slv)JuMPOptimiser
pe ┼ LowOrderPrior
│ X ┼ 50×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
slv ┼ 4-element Vector{Solver}
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
wb ┼ WeightBounds
│ lb ┼ Float64: 0.0
│ ub ┴ Float64: 1.0
bgt ┼ Float64: 1.0
sbgt ┼ nothing
gbgt ┼ nothing
lt ┼ nothing
st ┼ nothing
lcse ┼ nothing
cte ┼ nothing
gcarde ┼ nothing
sgcarde ┼ nothing
smtx ┼ nothing
sgmtx ┼ nothing
slt ┼ nothing
sst ┼ nothing
sglt ┼ nothing
sgst ┼ nothing
tn ┼ nothing
fees ┼ nothing
sets ┼ nothing
tr ┼ nothing
ple ┼ nothing
ret ┼ ArithmeticReturn
│ settings ┼ JuMPReturnsSettings
│ │ scale ┼ Float64: 1.0
│ │ lb ┼ nothing
│ │ rte ┼ Bool: true
│ │ fee ┼ Bool: true
│ │ mic ┴ Bool: true
│ ucs ┼ nothing
│ mu ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
sca ┼ SumScalariser()
ccnt ┼ nothing
cobj ┼ nothing
sc ┼ Int64: 1
so ┼ Int64: 1
ss ┼ nothing
card ┼ nothing
scard ┼ nothing
l2c ┼ nothing
lpc ┼ nothing
linfc ┼ nothing
l1 ┼ nothing
l2 ┼ nothing
lp ┼ nothing
linf ┼ nothing
xbgt ┼ Bool: false
strict ┴ Bool: false
2. Brownian distance variance
2.1 alg2: the absolute distances
By default BrownianDistanceVariance writes the absolute distances with a norm-one cone, NormOneConeBrownianDistanceVariance. The model adds one variable for each entry of the distance matrix and bounds it with that cone.
res_bdvar = optimise(MeanRisk(; r = BrownianDistanceVariance(), opt = opt))MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 50×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ Dict{Any, Any}: Dict{Any, Any}()
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 1295
│ │ ├ num_constraints: 1278
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ └ Vector{AffExpr} in MOI.NormOneCone: 1275
│ │ └ Names registered in the model
│ │ └ :Dt, :Dx, :T, :X, :bdvariance_risk, :bgt, :cbdvariance_noc, :k, :lw, :net_X, :obj_expr, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :so, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ BrownianDistanceVariance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ alg1 ┼ QuadRiskExpr()
│ alg2 ┴ NormOneConeBrownianDistanceVariance()
fb ┴ nothing
The other value of alg2, IneqBrownianDistanceVariance, writes the absolute distances with linear inequalities instead of a cone. On a large problem it can be faster, because it avoids a large cone.
res_bdvar_ineq = optimise(MeanRisk(; r = BrownianDistanceVariance(; alg2 = IneqBrownianDistanceVariance()), opt = opt))MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 50×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ Dict{Any, Any}: Dict{Any, Any}()
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 1295
│ │ ├ num_constraints: 5
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 3
│ │ │ └ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ └ Names registered in the model
│ │ └ :Dt, :Dx, :T, :X, :bdvariance_risk, :bgt, :cn_bdvariance, :cp_bdvariance, :k, :lw, :net_X, :obj_expr, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :so, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ BrownianDistanceVariance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ alg1 ┼ QuadRiskExpr()
│ alg2 ┴ IneqBrownianDistanceVariance()
fb ┴ nothing
2.2 alg1: the sum of squares
A second choice, alg1, sets how the model writes the sum of the squared distances. The default, QuadRiskExpr, writes it as a quadratic expression. RSOCRiskExpr writes it with a rotated second-order cone, which can be faster on a dense problem. We print the weights of the three formulations side by side.
res_bdvar_rsoc = optimise(MeanRisk(; r = BrownianDistanceVariance(; alg1 = RSOCRiskExpr()), opt = opt))pretty_table(DataFrame(; :assets => rd.nx, :BDVar_default => res_bdvar.w, :BDVar_ineq => res_bdvar_ineq.w, :BDVar_rsoc => res_bdvar_rsoc.w); formatters = [resfmt])┌────────┬───────────────┬────────────┬────────────┐
│ assets │ BDVar_default │ BDVar_ineq │ BDVar_rsoc │
│ String │ Float64 │ Float64 │ Float64 │
├────────┼───────────────┼────────────┼────────────┤
│ AAPL │ 0.0 % │ 0.0 % │ -0.0 % │
│ AMD │ 0.0 % │ 0.0 % │ -0.0 % │
│ BAC │ 0.0 % │ 0.0 % │ -0.0 % │
│ BBY │ 0.0 % │ 0.0 % │ -0.0 % │
│ CVX │ 6.687 % │ 6.687 % │ 6.687 % │
│ GE │ 0.0 % │ 0.0 % │ -0.0 % │
│ HD │ 0.0 % │ 0.0 % │ -0.0 % │
│ JNJ │ 43.573 % │ 43.573 % │ 43.586 % │
│ JPM │ 0.0 % │ 0.0 % │ -0.0 % │
│ KO │ 0.0 % │ 0.0 % │ -0.0 % │
│ LLY │ 0.0 % │ 0.0 % │ -0.0 % │
│ MRK │ 4.505 % │ 4.506 % │ 4.498 % │
│ MSFT │ 0.0 % │ 0.0 % │ -0.0 % │
│ PEP │ 6.377 % │ 6.377 % │ 6.379 % │
│ PFE │ 0.0 % │ 0.0 % │ -0.0 % │
│ PG │ 31.596 % │ 31.596 % │ 31.591 % │
│ RRC │ 0.0 % │ 0.0 % │ -0.0 % │
│ UNH │ 0.0 % │ 0.0 % │ 0.0 % │
│ WMT │ 7.261 % │ 7.261 % │ 7.259 % │
│ XOM │ 0.0 % │ 0.0 % │ 0.0 % │
└────────┴───────────────┴────────────┴────────────┘The three columns show the same portfolio. The formulations differ in how they build the model, not in what the model optimises.
We also minimise the variance, and plot the two portfolios. The Brownian distance variance depends on the distances between the returns of pairs of days, and the variance on the squared deviations about the mean, so the two portfolios can differ.
res_var = optimise(MeanRisk(; r = Variance(), opt = opt))using StatsPlots, GraphRecipesplot_stacked_bar_composition([res_var, res_bdvar], rd)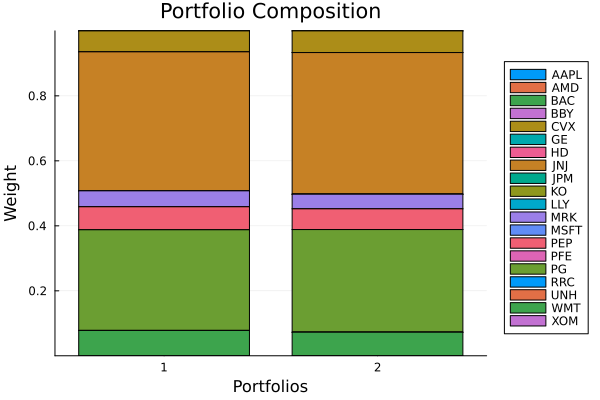
3. VarianceSkewKurtosis
3.1 High-order prior and SCS solver
We solve VarianceSkewKurtosis with SCS, and compute its prior with HighOrderPriorEstimator on the same 50 observations as section 1.
pr_ho = prior(HighOrderPriorEstimator(), rd)scs_slv = Solver(; name = :scs, solver = SCS.Optimizer, settings = "verbose" => false, check_sol = (; allow_local = true, allow_almost = true))opt_ho = JuMPOptimiser(; pe = pr_ho, slv = scs_slv)JuMPOptimiser
pe ┼ HighOrderPrior
│ pr ┼ LowOrderPrior
│ │ X ┼ 50×20 Matrix{Float64}
│ │ o_X ┼ nothing
│ │ mu ┼ 20-element Vector{Float64}
│ │ sigma ┼ 20×20 Matrix{Float64}
│ │ chol ┼ nothing
│ │ w ┼ nothing
│ │ ens ┼ nothing
│ │ kld ┼ nothing
│ │ ow ┼ nothing
│ │ rr ┼ nothing
│ │ fpr ┼ nothing
│ │ x_src ┼ nothing
│ │ ss_gaps ┼ nothing
│ │ pc ┴ nothing
│ kt ┼ 400×400 Matrix{Float64}
│ D2 ┼ 400×210 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ L2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ S2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ sk ┼ 20×400 Matrix{Float64}
│ V ┼ 20×20 Matrix{Float64}
│ skmp ┼ MatrixProcessing
│ │ pdm ┼ Posdef
│ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ dn ┼ nothing
│ │ dt ┼ nothing
│ │ alg ┼ nothing
│ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ fpr ┴ nothing
slv ┼ Solver
│ name ┼ Symbol: :scs
│ solver ┼ DataType: SCS.Optimizer
│ settings ┼ Pair{String, Bool}: "verbose" => false
│ check_sol ┼ @NamedTuple{allow_local::Bool, allow_almost::Bool}: (allow_local = true, allow_almost = true)
│ add_bridges ┴ Bool: true
wb ┼ WeightBounds
│ lb ┼ Float64: 0.0
│ ub ┴ Float64: 1.0
bgt ┼ Float64: 1.0
sbgt ┼ nothing
gbgt ┼ nothing
lt ┼ nothing
st ┼ nothing
lcse ┼ nothing
cte ┼ nothing
gcarde ┼ nothing
sgcarde ┼ nothing
smtx ┼ nothing
sgmtx ┼ nothing
slt ┼ nothing
sst ┼ nothing
sglt ┼ nothing
sgst ┼ nothing
tn ┼ nothing
fees ┼ nothing
sets ┼ nothing
tr ┼ nothing
ple ┼ nothing
ret ┼ ArithmeticReturn
│ settings ┼ JuMPReturnsSettings
│ │ scale ┼ Float64: 1.0
│ │ lb ┼ nothing
│ │ rte ┼ Bool: true
│ │ fee ┼ Bool: true
│ │ mic ┴ Bool: true
│ ucs ┼ nothing
│ mu ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
sca ┼ SumScalariser()
ccnt ┼ nothing
cobj ┼ nothing
sc ┼ Int64: 1
so ┼ Int64: 1
ss ┼ nothing
card ┼ nothing
scard ┼ nothing
l2c ┼ nothing
lpc ┼ nothing
linfc ┼ nothing
l1 ┼ nothing
l2 ┼ nothing
lp ┼ nothing
linf ┼ nothing
xbgt ┼ Bool: false
strict ┴ Bool: false
3.2 Default composite
VarianceSkewKurtosis combines three measures.
Variancepenalises dispersion.Skewnessenters with a negative sign, so a larger skewness lowers the risk, and returns skewed to the left raise it.Kurtosispenalises fat tails.
Each measure has a scale of 1 by default. A larger scale gives that moment more weight in the objective. We optimise with the default scales and print the return code.
res_vsk = optimise(MeanRisk(; r = VarianceSkewKurtosis(), opt = opt_ho), rd)println("VarianceSkewKurtosis retcode: $(res_vsk.retcode)")VarianceSkewKurtosis retcode: OptimisationSuccess
res ┴ Dict{Any, Any}: Dict{Any, Any}()3.3 Custom component scales
To set how much each higher moment counts next to the variance, pass your own Skewness and Kurtosis with a scale in their settings. The skewness takes MaxRiskMeasureSettings, and the kurtosis takes RiskMeasureSettings. We give both a scale of 2.
r_vsk_heavy = VarianceSkewKurtosis(; sk = Skewness(; settings = MaxRiskMeasureSettings(; scale = 2.0)), kt = Kurtosis(; settings = RiskMeasureSettings(; scale = 2.0)))res_vsk_heavy = optimise(MeanRisk(; r = r_vsk_heavy, opt = opt_ho), rd)MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ HighOrderPrior
│ │ │ pr ┼ LowOrderPrior
│ │ │ │ X ┼ 50×20 Matrix{Float64}
│ │ │ │ o_X ┼ nothing
│ │ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ │ chol ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ ens ┼ nothing
│ │ │ │ kld ┼ nothing
│ │ │ │ ow ┼ nothing
│ │ │ │ rr ┼ nothing
│ │ │ │ fpr ┼ nothing
│ │ │ │ x_src ┼ nothing
│ │ │ │ ss_gaps ┼ nothing
│ │ │ │ pc ┴ nothing
│ │ │ kt ┼ 400×400 Matrix{Float64}
│ │ │ D2 ┼ 400×210 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ │ │ L2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ │ │ S2 ┼ 210×400 SparseArrays.SparseMatrixCSC{Int64, Int64}
│ │ │ sk ┼ 20×400 Matrix{Float64}
│ │ │ V ┼ 20×20 Matrix{Float64}
│ │ │ skmp ┼ MatrixProcessing
│ │ │ │ pdm ┼ Posdef
│ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ dn ┼ nothing
│ │ │ │ dt ┼ nothing
│ │ │ │ alg ┼ nothing
│ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ Dict{Any, Any}: Dict{Any, Any}()
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: SCS
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: AffExpr
│ │ ├ num_variables: 26585
│ │ ├ num_constraints: 4
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ └ Vector{AffExpr} in MOI.PositiveSemidefiniteConeSquare: 1
│ │ └ Names registered in the model
│ │ └ :L2W1_vr_sk_kt, :M_vr_sk_kt, :M_vr_sk_kt_PSD, :T, :W1_vr_sk_kt, :W2_vr_sk_kt, :W3_vr_sk_kt, :bgt, :k, :kt_risk_1, :lw, :obj_expr, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :sk_risk_1, :so, :vr_risk_1, :vr_sk_kt_risk_1, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ VarianceSkewKurtosis
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ vr ┼ Variance
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 1.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: false
│ │ sigma ┼ 20×20 Matrix{Float64}
│ │ chol ┼ nothing
│ │ rc ┼ nothing
│ │ alg ┼ SquaredSOCRiskExpr()
│ │ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ │ ratio_alg ┼ SquareRootRatio()
│ │ corner ┴ nothing
│ sk ┼ Skewness
│ │ settings ┼ MaxRiskMeasureSettings
│ │ │ scale ┼ Float64: 2.0
│ │ │ lb ┼ nothing
│ │ │ rke ┴ Bool: false
│ │ ve ┼ SimpleVariance
│ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ w ┴ nothing
│ │ │ w ┼ nothing
│ │ │ corrected ┴ Bool: true
│ │ sk ┼ 20×400 Matrix{Float64}
│ │ w ┼ nothing
│ │ mu ┼ 20-element Vector{Float64}
│ │ pe ┴ nothing
│ kt ┼ Kurtosis
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 2.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: false
│ │ w ┼ nothing
│ │ mu ┼ 20-element Vector{Float64}
│ │ kt ┼ 400×400 Matrix{Float64}
│ │ N ┼ nothing
│ │ alg1 ┼ FullMoment()
│ │ alg2 ┼ SOCRiskExpr()
│ │ pe ┼ nothing
│ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ pe ┴ nothing
fb ┴ nothing
We print the two portfolios side by side. The larger scales double the skewness and kurtosis terms of the objective. On these 50 daily returns, the weights move by up to about three percentage points. JNJ grows, and PEP and MRK shrink.
pretty_table(DataFrame(; :assets => rd.nx, :VarianceSkewKurtosis => res_vsk.w, :VSK_heavy_tail => res_vsk_heavy.w); formatters = [resfmt])┌────────┬──────────────────────┬────────────────┐
│ assets │ VarianceSkewKurtosis │ VSK_heavy_tail │
│ String │ Float64 │ Float64 │
├────────┼──────────────────────┼────────────────┤
│ AAPL │ -0.001 % │ 0.0 % │
│ AMD │ -0.0 % │ 0.0 % │
│ BAC │ -0.0 % │ 0.0 % │
│ BBY │ -0.0 % │ 0.0 % │
│ CVX │ 4.614 % │ 4.42 % │
│ GE │ -0.0 % │ 0.0 % │
│ HD │ -0.001 % │ 0.0 % │
│ JNJ │ 31.215 % │ 31.072 % │
│ JPM │ 0.035 % │ 0.006 % │
│ KO │ -0.012 % │ 0.02 % │
│ LLY │ -0.001 % │ 0.0 % │
│ MRK │ 10.554 % │ 10.182 % │
│ MSFT │ -0.0 % │ 0.0 % │
│ PEP │ 9.63 % │ 9.877 % │
│ PFE │ -0.001 % │ 0.0 % │
│ PG │ 33.222 % │ 33.682 % │
│ RRC │ -0.0 % │ 0.0 % │
│ UNH │ -0.0 % │ 0.0 % │
│ WMT │ 8.474 % │ 8.415 % │
│ XOM │ 2.281 % │ 2.324 % │
└────────┴──────────────────────┴────────────────┘3.4 Comparison with plain variance (SCS)
We also minimise the variance with SCS on the same prior, so that only the risk measure differs, and plot the three portfolios.
res_var_scs = optimise(MeanRisk(; r = Variance(), opt = opt_ho))plot_stacked_bar_composition([res_var_scs, res_vsk, res_vsk_heavy], rd)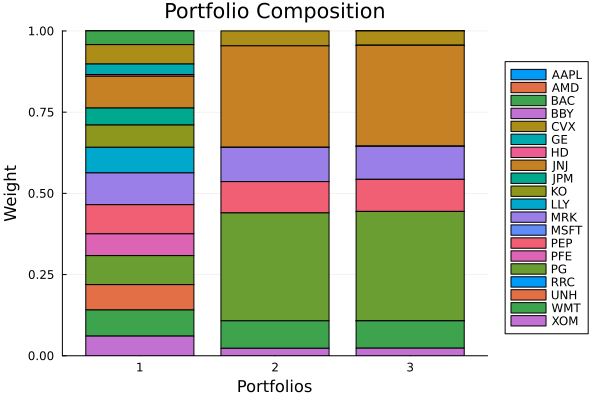
Summary
- We minimised
BrownianDistanceVariancewith Clarabel on 50 returns. KeepTsmall, because the size of the model grows with the square ofT. - We minimised
VarianceSkewKurtosiswith SCS, because the model is a large semidefinite problem. Pair it withHighOrderPriorEstimator, whose coskewness and cokurtosis grow with the number of assets.
This page was generated using Literate.jl.