The source files can be found in examples/.
Advanced Black-Litterman variants
The base BlackLittermanPrior of the previous page works on the assets alone, and each view is about one asset or a group of assets. But a view is often easier to state about a factor, such as "momentum will earn a premium" or "quality minus low volatility will be negative". Sometimes you also hold views on assets and on factors at once. The library has three variants of the model for these cases.
BayesianBlackLittermanPrioris the Bayesian form of the model, and it builds on aFactorPrior. You state the views on the factors, and the factor model carries the posterior back to the assets.FactorBlackLittermanPriortakes views on the factor premia and passes them to the assets through a factor regression. Thersdflag sets whether the posterior keeps the residual variance of each asset.lis the risk aversion of an implied factor equilibrium, and it is off by default.AugmentedBlackLittermanPriortakes views on assets ina_viewsand views on factors inf_viewsin one model, each with its own confidence.
Each variant returns a posterior mean and covariance over the assets, mu and sigma, and you give it to an optimiser as you give the base model.
Reach for these when your views are about factors, alone or next to views on single assets. Examples are a macro view on momentum or value, a spread between quality and low volatility, or a view on a stock that you want to combine with a view on a factor in one posterior. If every view is about assets, the base BlackLittermanPrior is simpler, and it is enough.
These variants need factor returns, so you must build the ReturnsResult with the factor data, which the price ingestion step adds: prices_to_returns(price_ingestion(PriceIngestion(), X; F = F)). Factor views and factor sets use the factor names in rd.nf.
using PortfolioOptimisers, PrettyTables, DataFramesmmtfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v * 100, digits = 4)) %" : v endend;resfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v * 100, digits = 3)) %" : v endend;1. Data, sets and the equilibrium prior
We load one year of daily prices of 20 assets and of five factor funds, and convert both to returns. Then we declare one UniverseSets that all three variants read. It lists the assets under "nx" and the factors under "nf", each in the column order of rd.X and rd.F. These are the default keys under which every estimator looks for the assets and the factors. The xkey and tfkey fields of UniverseSets hold the two keys. The object also holds two groups of assets for the asset views of the augmented model. One object therefore serves a model with factor views only, a model with asset views only, and the augmented model that has both.
We also compute the EquilibriumExpectedReturns prior as a reference to compare the posteriors with. The Bayesian, the factor and the augmented posteriors of the comparison table do not start from it. Each starts from the sample mean of the quantities its views update.
using CSV, TimeSeriesX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]F = TimeArray(CSV.File(joinpath(@__DIR__, "..", "Factors.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(price_ingestion(PriceIngestion(), X; F = F))universe_sets = UniverseSets(; dict = Dict("nx" => rd.nx, "nf" => rd.nf, "tech" => ["AAPL", "AMD", "MSFT"], "energy" => ["CVX"]))tau = 1 / size(rd.X, 1)pr_eq = prior(EmpiricalPrior(; me = EquilibriumExpectedReturns()), rd)LowOrderPrior
X ┼ 252×20 Matrix{Float64}
o_X ┼ nothing
mu ┼ 20-element Vector{Float64}
sigma ┼ 20×20 Matrix{Float64}
chol ┼ nothing
w ┼ nothing
ens ┼ nothing
kld ┼ nothing
ow ┼ nothing
rr ┼ nothing
fpr ┼ nothing
x_src ┼ nothing
ss_gaps ┼ nothing
pc ┴ nothing
rd.nf holds the names of the factors in this data set.
pretty_table(DataFrame(; factor = rd.nf); title = "Factor names (rd.nf)")Factor names (rd.nf)
┌────────┐
│ factor │
│ String │
├────────┤
│ MTUM │
│ QUAL │
│ SIZE │
│ USMV │
│ VLUE │
└────────┘2. Bayesian Black-Litterman with factor views
BayesianBlackLittermanPrior takes a FactorPrior as its base estimator, and views on the factors, whose names must be in sets.dict[sets.tfkey]. In this Bayesian form the factor prior gives the structure, and the views update the mean and the covariance of the factors. The model then maps the result back to a posterior over the assets through the factor loadings.
We state two factor views. Momentum earns 5 bps a day, and quality returns 3 bps a day less than low volatility.
factor_views = LinearConstraintEstimator(; val = ["MTUM == 0.0005", "QUAL - USMV == -0.0003"])pr_bayes = prior(BayesianBlackLittermanPrior(; pe = FactorPrior(; pe = EmpiricalPrior()), sets = universe_sets, tau = tau, views = factor_views), rd)LowOrderPrior
X ┼ 252×20 Matrix{Float64}
o_X ┼ 252×20 Matrix{Float64}
mu ┼ 20-element Vector{Float64}
sigma ┼ 20×20 Matrix{Float64}
chol ┼ nothing
w ┼ nothing
ens ┼ nothing
kld ┼ nothing
ow ┼ nothing
rr ┼ Regression
│ M ┼ 20×5 SubArray{Float64, 2, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, UnitRange{Int64}}, true}
│ L ┼ 20×5 SubArray{Float64, 2, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, UnitRange{Int64}}, true}
│ b ┼ 20-element SubArray{Float64, 1, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, Int64}, true}
│ esigma ┼ 20-element Vector{Float64}
│ edof ┼ 20-element Vector{Int64}
│ ediv ┼ 20-element Vector{Int64}
│ idx ┼ 252-element UnitRange{Int64}
│ ts ┴ nothing
fpr ┼ LowOrderPrior
│ X ┼ 252×5 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ Vector{Float64}: [0.0004935513857205133, 0.00013981052864864518, 0.0002941301399949343, 0.0004387517589914691, 0.0003055527028387441]
│ sigma ┼ 5×5 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
x_src ┼ nothing
ss_gaps ┼ nothing
pc ┴ nothing
3. Factor Black-Litterman with views on factor premia
FactorBlackLittermanPrior also takes factor views. It runs the ordinary Black-Litterman update on a prior fit to the factors alone, and carries the result to the assets through the regression loadings. Its views name factors from the same list, sets.dict[sets.tfkey]. Two parameters change the posterior.
rsd = trueadds the residual variance of each asset on the diagonal of the posterior covariance, andrsd = falsekeeps only the part the factors explain.lis off by default,nothing. Set it, and the model replaces the factor prior's own mean with the equilibrium mean that this risk aversion implies for the equal-weight portfolio.
We build one prior with each rsd setting, and a third that sets l = 5. The table compares Apple's posterior mean and variance under the two rsd settings. The page prints nothing for the third prior, and you can compare pr_fbl_l.mu with pr_fbl_rsd.mu to see what l changes.
pr_fbl_rsd = prior(FactorBlackLittermanPrior(; pe = EmpiricalPrior(), rsd = true, sets = universe_sets, tau = tau, views = factor_views), rd)pr_fbl_nors = prior(FactorBlackLittermanPrior(; pe = EmpiricalPrior(), rsd = false, sets = universe_sets, tau = tau, views = factor_views), rd)pr_fbl_l = prior(FactorBlackLittermanPrior(; pe = EmpiricalPrior(), rsd = true, l = 5.0, sets = universe_sets, tau = tau, views = factor_views), rd)i_aapl = findfirst(==("AAPL"), rd.nx)pretty_table(DataFrame(; quantity = ["AAPL posterior mean", "AAPL posterior variance"], rsd_true = [pr_fbl_rsd.mu[i_aapl], pr_fbl_rsd.sigma[i_aapl, i_aapl]], rsd_false = [pr_fbl_nors.mu[i_aapl], pr_fbl_nors.sigma[i_aapl, i_aapl]]); formatters = [mmtfmt], title = "AAPL posterior mean and variance of FactorBlackLittermanPrior with and without the residual variance")AAPL posterior mean and variance of FactorBlackLittermanPrior with and without the residual variance
┌─────────────────────────┬──────────┬───────────┐
│ quantity │ rsd_true │ rsd_false │
│ String │ Float64 │ Float64 │
├─────────────────────────┼──────────┼───────────┤
│ AAPL posterior mean │ -0.044 % │ -0.044 % │
│ AAPL posterior variance │ 0.0501 % │ 0.0384 % │
└─────────────────────────┴──────────┴───────────┘With rsd = false the covariance keeps only the part the factors explain, so the posterior variance is smaller. The model then assumes that the factors explain all of the risk.
4. Augmented Black-Litterman with asset and factor views
AugmentedBlackLittermanPrior is the most general variant. It takes views on assets in a_views and views on factors in f_views, in the same posterior. Use it when you hold a view on a stock and a view on a factor, and do not want to choose between them.
It is the only estimator of the three that reads both declared lists, and it reads them from the same universe_sets as the variants above. It resolves the names of a_views against the assets, sets.dict[sets.xkey], and the names of f_views against the factors, sets.dict[sets.tfkey]. A group name such as tech is read from its own entry in sets.dict, and in Black-Litterman it stands for the average of its members.
asset_views = LinearConstraintEstimator(; val = ["AAPL == 0.0008", "tech == 0.0006"])pr_aug = prior(AugmentedBlackLittermanPrior(; sets = universe_sets, tau = tau, a_views = asset_views, f_views = factor_views), rd)LowOrderPrior
X ┼ 252×20 Matrix{Float64}
o_X ┼ 252×20 Matrix{Float64}
mu ┼ 20-element Vector{Float64}
sigma ┼ 20×20 Matrix{Float64}
chol ┼ nothing
w ┼ nothing
ens ┼ nothing
kld ┼ nothing
ow ┼ nothing
rr ┼ Regression
│ M ┼ 20×5 SubArray{Float64, 2, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, UnitRange{Int64}}, true}
│ L ┼ 20×5 SubArray{Float64, 2, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, UnitRange{Int64}}, true}
│ b ┼ 20-element SubArray{Float64, 1, Matrix{Float64}, Tuple{Base.Slice{Base.OneTo{Int64}}, Int64}, true}
│ esigma ┼ nothing
│ edof ┼ 20-element Vector{Int64}
│ ediv ┼ nothing
│ idx ┼ nothing
│ ts ┴ nothing
fpr ┼ LowOrderPrior
│ X ┼ 252×5 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ Vector{Float64}: [0.0001738101695024088, 0.00010766089837441716, 0.00023286771481700614, 0.0003149866079392385, 0.00021554387985553566]
│ sigma ┼ 5×5 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
x_src ┼ nothing
ss_gaps ┼ nothing
pc ┴ nothing
5. Comparing the posteriors
Each variant gives a different posterior mean. The table lines them up with the equilibrium prior for the first few assets. The factor views move every asset, and the augmented model also moves the assets that its asset views name.
cmp = DataFrame(; Assets = rd.nx, Equilibrium = pr_eq.mu, Bayesian = pr_bayes.mu, Factor = pr_fbl_rsd.mu, Augmented = pr_aug.mu)pretty_table(first(cmp, 8); formatters = [mmtfmt], title = "Posterior expected returns (first 8 assets)") Posterior expected returns (first 8 assets)
┌────────┬─────────────┬───────────┬───────────┬───────────┐
│ Assets │ Equilibrium │ Bayesian │ Factor │ Augmented │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼─────────────┼───────────┼───────────┼───────────┤
│ AAPL │ 0.0231 % │ 0.0036 % │ -0.044 % │ 0.0222 % │
│ AMD │ 0.0362 % │ -0.1036 % │ -0.1656 % │ -0.0792 % │
│ BAC │ 0.0191 % │ 0.0005 % │ -0.0392 % │ -0.0127 % │
│ BBY │ 0.0239 % │ 0.0659 % │ 0.0316 % │ 0.072 % │
│ CVX │ 0.0144 % │ 0.2523 % │ 0.2295 % │ 0.2375 % │
│ GE │ 0.0194 % │ 0.0642 % │ 0.0212 % │ 0.0512 % │
│ HD │ 0.0178 % │ 0.0126 % │ -0.0229 % │ 0.0082 % │
│ JNJ │ 0.0075 % │ 0.0701 % │ 0.0456 % │ 0.0588 % │
└────────┴─────────────┴───────────┴───────────┴───────────┘The posterior expected returns of the augmented model, for every asset.
using StatsPlots, GraphRecipesplot_mu(pr_aug, rd.nx)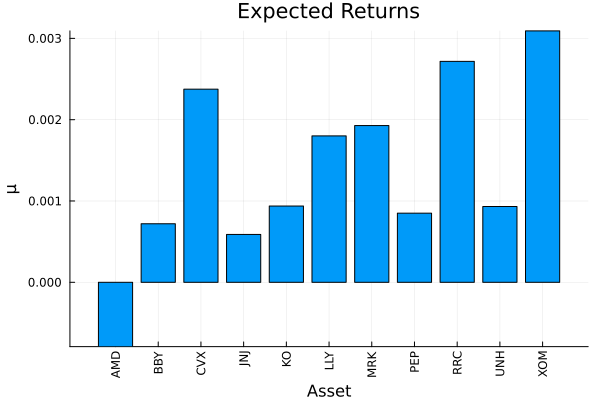
6. From views to portfolios
As with the base model, each posterior changes the optimal portfolio. We solve a maximum-ratio portfolio under the equilibrium prior and under each variant, then compare the compositions.
using Clarabelslv = Solver(; name = :clarabel1, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true))rf = 4.2 / 100 / 252priors = ["Equilibrium" => pr_eq, "Bayesian" => pr_bayes, "Factor" => pr_fbl_rsd, "Augmented" => pr_aug]res = [optimise(MeanRisk(; obj = MaximumRatio(; rf = rf), opt = JuMPOptimiser(; pe = p, slv = slv))) for (_, p) in priors]pretty_table(DataFrame(hcat(rd.nx, [r.w for r in res]...), [:assets; Symbol.(first.(priors))...]); formatters = [resfmt], title = "Maximum-ratio weights by prior")plot_stacked_bar_composition(res, rd; xticks = (1:length(priors), first.(priors)))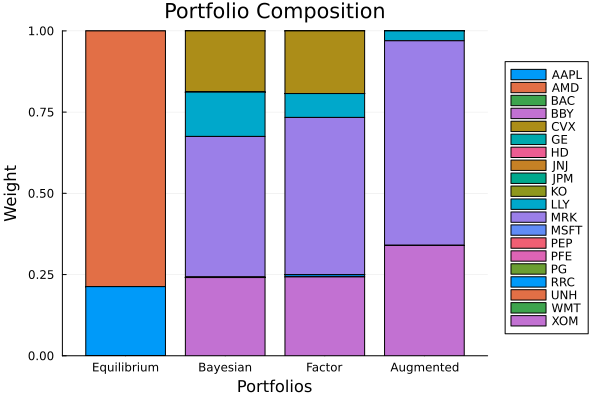
Summary
The three variants take views that the base model cannot.
BayesianBlackLittermanPriorputs factor views on aFactorPrior.FactorBlackLittermanPriorpasses views on the factor premia through a regression.rsdsets whether it keeps the residual variance, andl, off by default, is the risk aversion of an implied equilibrium.AugmentedBlackLittermanPriorcombines asset views and factor views in one posterior.
This page was generated using Literate.jl.