The source files can be found in examples/.
Clustering optimisers with mixed risks and constraints
The clustering optimiser page covers one risk measure at a time and no constraints. This page covers two things it leaves out:
- a clustering optimiser takes several risk measures at once, and a different one at each level of the hierarchy;
- the hierarchical optimiser still takes weight bounds and fees while the clustering does the spreading.
The data is one year of daily prices for twenty S&P 500 stocks. We solve four HRP runs and four HERC runs on one mixed pair of risk measures, one run per scalariser. One more HERC run takes the same pair under a 10% weight cap and a fee.
Reach for a mixed-risk clustering optimiser when one risk measure does not cover what you want to control and you still want the hierarchy to spread the money. You might combine a tail measure with variance, or measure risk inside a cluster one way and between clusters another. The scalariser sets how the risk terms combine.
using PortfolioOptimisers, PrettyTablesresfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v * 100, digits = 3)) %" : v endend;1. Data and clustering
We compute the prior and the tree once, and every run below reads the same two.
using CSV, TimeSeries, DataFrames, ClarabelX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(X)pr = prior(EmpiricalPrior(), rd)clr = clusterise(ClustersEstimator(; alg = DBHT()), pr.X)slv = Solver(; name = :clarabel, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true))opt = HierarchicalOptimiser(; pe = pr, cle = clr, slv = slv)HierarchicalOptimiser
pe ┼ LowOrderPrior
│ X ┼ 252×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
cle ┼ Clusters
│ res ┼ Clustering.Hclust{Float64}([-1 -13; -7 -4; … ; 12 17; 10 18], [0.1, 0.1111111111111111, 0.125, 0.14285714285714285, 0.16666666666666666, 0.2, 0.25, 0.3333333333333333, 0.5, 1.0, 0.125, 0.14285714285714285, 0.16666666666666666, 0.2, 0.25, 0.3333333333333333, 0.5, 1.0, 2.0], [17, 20, 5, 3, 9, 6, 2, 1, 13, 7, 4, 19, 14, 10, 16, 18, 11, 8, 12, 15], :DBHT)
│ S ┼ 20×20 Matrix{Float64}
│ D ┼ 20×20 Matrix{Float64}
│ P ┼ nothing
│ k ┴ Int64: 4
slv ┼ Solver
│ name ┼ Symbol: :clarabel
│ solver ┼ UnionAll: Clarabel.MOIwrapper.Optimizer
│ settings ┼ Dict{String, Bool}: Dict{String, Bool}("verbose" => 0)
│ check_sol ┼ @NamedTuple{allow_local::Bool, allow_almost::Bool}: (allow_local = true, allow_almost = true)
│ add_bridges ┴ Bool: true
wb ┼ WeightBounds
│ lb ┼ Float64: 0.0
│ ub ┴ Float64: 1.0
fees ┼ nothing
sets ┼ nothing
wf ┼ IterativeWeightFinaliser
│ iter ┴ Int64: 100
strict ┴ Bool: false
2. HRP with mixed risk measures
HierarchicalRiskParity takes one risk measure or a vector of them. When you pass a vector, the scalariser sets how the risks of the measures combine at each split. SumScalariser adds them. MaxScalariser and MinScalariser use the measure whose risk is the largest or the smallest. LogSumExpScalariser takes a smooth maximum, and its gamma sets how close it comes to the largest.
The cell below pairs a tail measure, ConditionalValueatRisk, with a variance, and runs the four scalarisers over that pair. The scale of the variance multiplies its risk by 200 before the scalariser combines the two. That brings a daily variance to the same order of magnitude as a daily conditional value at risk. Read the four weight columns against each other.
r_mix = [ConditionalValueatRisk(), Variance(; settings = RiskMeasureSettings(; scale = 2e2))]hrp_sum = optimise(HierarchicalRiskParity(; r = r_mix, opt = opt, sca = SumScalariser()))hrp_max = optimise(HierarchicalRiskParity(; r = r_mix, opt = opt, sca = MaxScalariser()))hrp_min = optimise(HierarchicalRiskParity(; r = r_mix, opt = opt, sca = MinScalariser()))hrp_lse = optimise(HierarchicalRiskParity(; r = r_mix, opt = opt, sca = LogSumExpScalariser(; gamma = 1e2)))pretty_table(DataFrame(; :assets => rd.nx, :Sum => hrp_sum.w, :Max => hrp_max.w, :Min => hrp_min.w, :LogSumExp => hrp_lse.w); formatters = [resfmt])┌────────┬──────────┬──────────┬──────────┬───────────┐
│ assets │ Sum │ Max │ Min │ LogSumExp │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼──────────┼──────────┼──────────┼───────────┤
│ AAPL │ 3.866 % │ 3.26 % │ 4.801 % │ 3.937 % │
│ AMD │ 1.669 % │ 1.263 % │ 2.678 % │ 1.53 % │
│ BAC │ 3.169 % │ 2.742 % │ 3.744 % │ 3.258 % │
│ BBY │ 3.373 % │ 2.871 % │ 4.403 % │ 3.0 % │
│ CVX │ 5.602 % │ 5.049 % │ 6.128 % │ 5.996 % │
│ GE │ 4.208 % │ 3.879 % │ 4.133 % │ 4.691 % │
│ HD │ 2.751 % │ 2.605 % │ 2.72 % │ 3.118 % │
│ JNJ │ 11.741 % │ 13.136 % │ 10.025 % │ 10.95 % │
│ JPM │ 3.594 % │ 3.24 % │ 3.922 % │ 3.834 % │
│ KO │ 5.384 % │ 6.299 % │ 4.426 % │ 5.189 % │
│ LLY │ 6.556 % │ 5.995 % │ 7.372 % │ 6.223 % │
│ MRK │ 6.076 % │ 6.583 % │ 5.297 % │ 5.813 % │
│ MSFT │ 2.345 % │ 2.06 % │ 2.675 % │ 2.477 % │
│ PEP │ 9.848 % │ 11.24 % │ 8.327 % │ 9.598 % │
│ PFE │ 3.77 % │ 3.589 % │ 3.965 % │ 3.553 % │
│ PG │ 4.506 % │ 5.051 % │ 3.887 % │ 4.444 % │
│ RRC │ 1.714 % │ 1.277 % │ 2.919 % │ 1.541 % │
│ UNH │ 7.473 % │ 7.499 % │ 7.184 % │ 7.552 % │
│ WMT │ 7.732 % │ 8.257 % │ 6.552 % │ 8.344 % │
│ XOM │ 4.625 % │ 4.105 % │ 4.842 % │ 4.951 % │
└────────┴──────────┴──────────┴──────────┴───────────┘3. HERC with mixed inner and outer risks
HierarchicalEqualRiskContribution takes a risk measure and a scalariser at each of its two levels, so it can measure risk inside a cluster one way and between clusters another.
We pass the same pair of risk measures at both levels and run the same four scalarisers at both levels.
herc_sum = optimise(HierarchicalEqualRiskContribution(; opt = opt, ri = r_mix, ro = r_mix, scai = SumScalariser(), scao = SumScalariser()))herc_max = optimise(HierarchicalEqualRiskContribution(; opt = opt, ri = r_mix, ro = r_mix, scai = MaxScalariser(), scao = MaxScalariser()))herc_min = optimise(HierarchicalEqualRiskContribution(; opt = opt, ri = r_mix, ro = r_mix, scai = MinScalariser(), scao = MinScalariser()))herc_lse = optimise(HierarchicalEqualRiskContribution(; opt = opt, ri = r_mix, ro = r_mix, scai = LogSumExpScalariser(; gamma = 1e2), scao = LogSumExpScalariser(; gamma = 1e2)))pretty_table(DataFrame(; :assets => rd.nx, :Sum => herc_sum.w, :Max => herc_max.w, :Min => herc_min.w, :LogSumExp => herc_lse.w); formatters = [resfmt])┌────────┬──────────┬──────────┬──────────┬───────────┐
│ assets │ Sum │ Max │ Min │ LogSumExp │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼──────────┼──────────┼──────────┼───────────┤
│ AAPL │ 2.124 % │ 1.857 % │ 2.628 % │ 2.175 % │
│ AMD │ 0.723 % │ 0.63 % │ 1.445 % │ 0.738 % │
│ BAC │ 2.552 % │ 2.232 % │ 2.998 % │ 2.614 % │
│ BBY │ 1.31 % │ 1.144 % │ 1.969 % │ 1.34 % │
│ CVX │ 5.519 % │ 4.547 % │ 6.078 % │ 5.41 % │
│ GE │ 2.21 % │ 1.934 % │ 2.23 % │ 2.266 % │
│ HD │ 2.739 % │ 2.398 % │ 2.629 % │ 2.809 % │
│ JNJ │ 10.319 % │ 10.791 % │ 7.863 % │ 10.128 % │
│ JPM │ 3.013 % │ 2.636 % │ 3.141 % │ 3.088 % │
│ KO │ 12.774 % │ 13.746 % │ 10.942 % │ 13.001 % │
│ LLY │ 4.226 % │ 4.407 % │ 5.503 % │ 4.136 % │
│ MRK │ 7.883 % │ 8.24 % │ 6.658 % │ 7.733 % │
│ MSFT │ 2.168 % │ 1.896 % │ 2.586 % │ 2.221 % │
│ PEP │ 13.062 % │ 14.058 % │ 10.897 % │ 13.296 % │
│ PFE │ 4.304 % │ 4.492 % │ 4.984 % │ 4.216 % │
│ PG │ 6.489 % │ 6.785 % │ 5.241 % │ 6.368 % │
│ RRC │ 1.517 % │ 1.244 % │ 3.492 % │ 1.48 % │
│ UNH │ 5.279 % │ 5.513 % │ 5.363 % │ 5.174 % │
│ WMT │ 6.933 % │ 7.451 % │ 7.561 % │ 7.047 % │
│ XOM │ 4.857 % │ 4.001 % │ 5.792 % │ 4.759 % │
└────────┴──────────┴──────────┴──────────┴───────────┘At each split the max scalariser uses the measure whose scaled risk is the larger, and the min scalariser uses the smaller one. When one measure is the larger at most splits, the Max column follows that measure and the Min column follows the other. The next plot stacks the eight allocations of sections 2 and 3.
using StatsPlots, GraphRecipesplot_stacked_bar_composition([hrp_sum, hrp_max, hrp_min, hrp_lse, herc_sum, herc_max, herc_min, herc_lse], rd)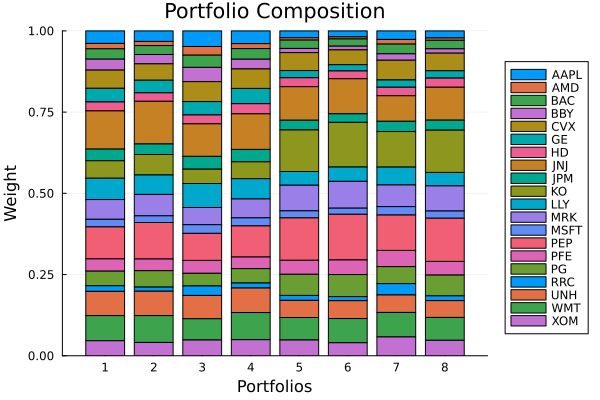
4. Constrained HERC
The hierarchical optimiser takes weight bounds and fees. This run keeps the same pair of risk measures and adds both. We set the cap at 10%, ub = 0.1, which is tighter than the largest weight the unconstrained HERC gives, near 13%. Read the largest holdings of the two columns below against each other.
opt_constrained = HierarchicalOptimiser(; pe = pr, cle = clr, slv = slv, wb = WeightBounds(; lb = 0.0, ub = 0.1), fees = Fees(; l = 0.001))herc_constrained = optimise(HierarchicalEqualRiskContribution(; opt = opt_constrained, ri = r_mix, ro = r_mix, scai = SumScalariser(), scao = SumScalariser()))pretty_table(DataFrame(; :assets => rd.nx, :Unconstrained => herc_sum.w, :Constrained => herc_constrained.w); formatters = [resfmt])┌────────┬───────────────┬─────────────┐
│ assets │ Unconstrained │ Constrained │
│ String │ Float64 │ Float64 │
├────────┼───────────────┼─────────────┤
│ AAPL │ 2.124 % │ 2.342 % │
│ AMD │ 0.723 % │ 0.797 % │
│ BAC │ 2.552 % │ 2.814 % │
│ BBY │ 1.31 % │ 1.444 % │
│ CVX │ 5.519 % │ 6.105 % │
│ GE │ 2.21 % │ 2.437 % │
│ HD │ 2.739 % │ 3.021 % │
│ JNJ │ 10.319 % │ 10.0 % │
│ JPM │ 3.013 % │ 3.322 % │
│ KO │ 12.774 % │ 10.0 % │
│ LLY │ 4.226 % │ 4.604 % │
│ MRK │ 7.883 % │ 8.586 % │
│ MSFT │ 2.168 % │ 2.391 % │
│ PEP │ 13.062 % │ 10.0 % │
│ PFE │ 4.304 % │ 4.689 % │
│ PG │ 6.489 % │ 7.069 % │
│ RRC │ 1.517 % │ 1.679 % │
│ UNH │ 5.279 % │ 5.75 % │
│ WMT │ 6.933 % │ 7.579 % │
│ XOM │ 4.857 % │ 5.372 % │
└────────┴───────────────┴─────────────┘We plot the share of the variance of the constrained portfolio that each asset carries. It measures the variance alone, not the pair of measures the portfolio was built on. As on the clustering optimiser page, factory gives the variance the covariance of the prior before plot_risk_contribution uses it.
rv = factory(Variance(), pr)plot_risk_contribution(rv, herc_constrained, rd)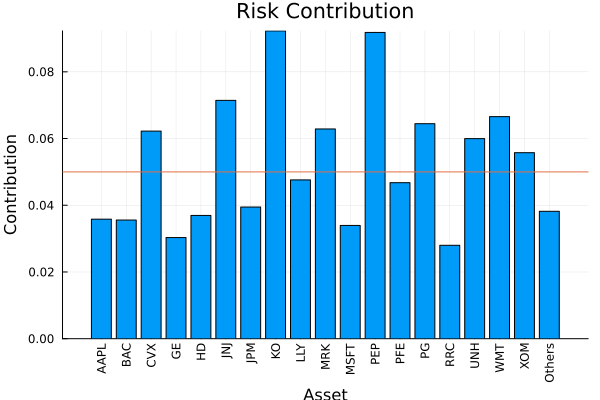
Summary
A clustering optimiser spreads the money through the tree, and you set how it measures risk.
HierarchicalRiskParitygives different weights under each scalariser once you mix risk measures.HierarchicalEqualRiskContributiontakes a different risk measure and a different scalariser inside a cluster and between clusters.HierarchicalOptimisertakes weight bounds and fees for either optimiser.
This page was generated using Literate.jl.