The source files can be found in examples/.
Hyperparameter tuning
Hyperparameter tuning chooses the parameters of an estimator by how they score on the test folds of a cross-validation. This example shows the two searches of PortfolioOptimisers.jl, a grid search and a randomised search. Then it shows a search that scores with many risk measures and many search scorers, and keeps the predictions that it scored.
using PortfolioOptimisers, PrettyTablestsfmt = (v, i, j) -> begin if j == 1 return Date(v) else return v endend;resfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v*100, digits=3)) %" : v endend;1. Setting up
We use the same five years of daily data as the cross-validation example.
As in the cross-validation example, the fields of the estimator you tune must be estimators, not precomputed results. The search fits each candidate again on each fold.
using CSV, TimeSeries, DataFrames, Clarabel, Statistics, StableRNGs, DistributionsX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252 * 5):end]pretty_table(X[(end - 5):end]; formatters = [tsfmt])rd = prices_to_returns(X)slv = [Solver(; name = :clarabel1, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel2, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.95), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel3, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.9), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel4, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.85), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel5, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.8), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel6, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.75), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel7, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.70), check_sol = (; allow_local = true, allow_almost = true))];┌────────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┐
│ timestamp │ AAPL │ AMD │ BAC │ BBY │ CVX │ GE │ HD │ JNJ │ JPM │ KO │ LLY │ MRK │ MSFT │ PEP │ PFE │ PG │ RRC │ UNH │ WMT │ XOM │
│ Date │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┤
│ 2022-12-20 │ 131.916 │ 65.05 │ 31.729 │ 77.371 │ 169.497 │ 62.604 │ 310.342 │ 173.109 │ 127.844 │ 61.841 │ 357.55 │ 108.229 │ 240.67 │ 178.765 │ 49.754 │ 147.661 │ 25.65 │ 516.245 │ 142.919 │ 104.964 │
│ 2022-12-21 │ 135.057 │ 67.68 │ 32.212 │ 78.729 │ 171.49 │ 64.67 │ 314.798 │ 175.09 │ 129.282 │ 62.836 │ 365.872 │ 109.611 │ 243.287 │ 180.017 │ 50.084 │ 149.015 │ 26.574 │ 523.519 │ 144.04 │ 106.312 │
│ 2022-12-22 │ 131.846 │ 63.86 │ 31.927 │ 78.563 │ 168.918 │ 63.727 │ 311.604 │ 174.45 │ 127.814 │ 62.383 │ 363.187 │ 109.739 │ 237.077 │ 178.627 │ 50.065 │ 149.359 │ 25.232 │ 523.072 │ 142.354 │ 104.168 │
│ 2022-12-23 │ 131.477 │ 64.52 │ 32.005 │ 79.432 │ 174.14 │ 63.742 │ 314.177 │ 174.893 │ 128.421 │ 62.855 │ 365.762 │ 110.35 │ 237.614 │ 179.781 │ 50.249 │ 149.781 │ 26.226 │ 527.26 │ 142.641 │ 106.922 │
│ 2022-12-27 │ 129.652 │ 63.27 │ 32.065 │ 79.93 │ 176.329 │ 64.561 │ 314.985 │ 174.844 │ 128.871 │ 63.24 │ 362.76 │ 110.607 │ 235.852 │ 180.58 │ 49.57 │ 151.086 │ 26.375 │ 527.935 │ 142.681 │ 108.408 │
│ 2022-12-28 │ 125.674 │ 62.57 │ 32.301 │ 78.279 │ 173.728 │ 63.883 │ 311.22 │ 174.085 │ 129.575 │ 62.609 │ 363.098 │ 109.581 │ 233.434 │ 179.278 │ 49.25 │ 149.133 │ 24.497 │ 524.422 │ 140.181 │ 106.627 │
└────────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┘2. Hyperparameter tuning
We tune a Stacking estimator, and the search works the same way for the other optimisation estimators, such as NestedClustered. A key of the grid is a string with the property path to the parameter, such as "opti[1].opt.l2.val". The search parses the string into an Accessors.jl lens, an object that returns a copy of the estimator with that one field changed.
A search needs a risk measure, r, to score every fold, and a cross-validation scheme, cv, which defaults to KFold. It also accepts a WalkForwardEstimator, a CombinatorialCrossValidation and a MultipleRandomised. Under a combinatorial scheme, it scores each path instead of each fold.
opt = JuMPOptimiser(; slv = slv)#! `l2` is `nothing` by default, and the key `l2.val` needs an `L2Regularisation` in it.optl2 = JuMPOptimiser(; slv = slv, l2 = L2Regularisation())r = MeanReturnRiskRatio(; rk = LowOrderMoment(; alg = SecondMoment()))st = Stacking(; opti = [MeanRisk(; opt = optl2), RiskBudgeting(; opt = opt)], opto = MeanRisk(; opt = opt))Stacking
pe ┼ EmpiricalPrior
│ ce ┼ PortfolioOptimisersCovariance
│ │ ce ┼ Covariance
│ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ w ┴ nothing
│ │ │ ce ┼ GeneralCovariance
│ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ w ┴ nothing
│ │ │ alg ┼ FullMoment()
│ │ │ w ┴ nothing
│ │ mp ┼ MatrixProcessing
│ │ │ pdm ┼ Posdef
│ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ dn ┼ nothing
│ │ │ dt ┼ nothing
│ │ │ alg ┼ nothing
│ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ me ┼ SimpleExpectedReturns
│ │ w ┴ nothing
│ horizon ┼ nothing
│ fill_limit ┼ nothing
│ x_src ┴ nothing
wb ┼ nothing
fees ┼ nothing
sets ┼ nothing
scale ┼ nothing
opti ┼ 2-element Vector{Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult, TimeDependent{<:AbstractVector{<:Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult}}}, TimeDependent{<:TimeDependentOptimiserCallable}, TimeDependent{<:PreviousWeightsFunction}, TimeDependent{<:Union{Function, Type}}}}
│ MeanRisk ⋯
│ RiskBudgeting ⋯
opto ┼ MeanRisk
│ opt ┼ JuMPOptimiser
│ │ pe ┼ EmpiricalPrior
│ │ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ │ ce ┼ Covariance
│ │ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ alg ┼ FullMoment()
│ │ │ │ │ w ┴ nothing
│ │ │ │ mp ┼ MatrixProcessing
│ │ │ │ │ pdm ┼ Posdef
│ │ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ │ dn ┼ nothing
│ │ │ │ │ dt ┼ nothing
│ │ │ │ │ alg ┼ nothing
│ │ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ w ┴ nothing
│ │ │ horizon ┼ nothing
│ │ │ fill_limit ┼ nothing
│ │ │ x_src ┴ nothing
│ │ slv ┼ 7-element Vector{Solver}
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ │ Solver ⋯
│ │ cbe ┼ ConstraintBlock
│ │ │ wb ┼ WeightBounds
│ │ │ │ lb ┼ Float64: 0.0
│ │ │ │ ub ┴ Float64: 1.0
│ │ │ sbgt ┼ nothing
│ │ │ gbgt ┼ nothing
│ │ │ lt ┼ nothing
│ │ │ st ┼ nothing
│ │ │ lcse ┼ nothing
│ │ │ cte ┼ nothing
│ │ │ gcarde ┼ nothing
│ │ │ sgcarde ┼ nothing
│ │ │ smtx ┼ nothing
│ │ │ sgmtx ┼ nothing
│ │ │ slt ┼ nothing
│ │ │ sst ┼ nothing
│ │ │ sglt ┼ nothing
│ │ │ sgst ┼ nothing
│ │ │ tn ┼ nothing
│ │ │ sets ┼ nothing
│ │ │ tr ┼ nothing
│ │ │ ple ┼ nothing
│ │ │ ccnt ┼ nothing
│ │ │ cobj ┼ nothing
│ │ │ ss ┼ nothing
│ │ │ card ┼ nothing
│ │ │ scard ┼ nothing
│ │ │ l2c ┼ nothing
│ │ │ lpc ┼ nothing
│ │ │ linfc ┼ nothing
│ │ │ l1 ┼ nothing
│ │ │ l2 ┼ nothing
│ │ │ lp ┼ nothing
│ │ │ linf ┼ nothing
│ │ │ xbgt ┴ Bool: false
│ │ bgt ┼ Float64: 1.0
│ │ fees ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ nothing
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ nothing
│ │ sc ┼ Int64: 1
│ │ so ┼ Int64: 1
│ │ strict ┴ Bool: false
│ r ┼ Variance
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 1.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: true
│ │ sigma ┼ nothing
│ │ chol ┼ nothing
│ │ rc ┼ nothing
│ │ alg ┼ SquaredSOCRiskExpr()
│ │ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ │ ratio_alg ┼ SquareRootRatio()
│ │ corner ┴ nothing
│ obj ┼ MinimumRisk()
│ wi ┼ nothing
│ fb ┴ nothing
cv ┼ nothing
scorer ┼ nothing
wf ┼ IterativeWeightFinaliser
│ iter ┴ Int64: 100
ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
fb ┼ nothing
strict ┼ Bool: false
pcol ┴ RenormaliseActive()
2.1 Grid cross validation search
GridSearchCrossValidation tries every point of a parameter grid with search_cross_validation, and keeps the point with the best mean test score.
A grid is a vector of pairs. The first item of a pair is the key of a parameter, and the second is a vector of the values to try. A dictionary of the same pairs also works. The search takes the product of the values in a grid. A Dict has no fixed order, which matters to a randomised search, as section 2.2 explains.
You can give a vector of grids. The search expands each grid on its own and joins the results into one list of candidates.
A literal vector of grids whose values have different types has the element type Vector. The constructor accepts it, checks that each element is a grid, and narrows the element type to the union of the types of the grids. A vector of dictionaries works in the same way.
We search four grids. n_best = 3 keeps the three best candidates over all of them, in rank order. The default n_best = 1 keeps the best one alone.
p = [["opti[2].opt.l1" => range(; start = 0.0005, stop = 0.0008, length = 3), "opti[1].opt.l2.val" => range(; start = 0.0004, stop = 0.0007, length = 3)], ["opti[1].opt.l2.val" => range(; start = 0.0004, stop = 0.0007, length = 3)], ["opti[2].opt.l1" => range(; start = 0.0009, stop = 0.0012, length = 3)], ["opti[2]" => [MeanRisk(; opt = opt, obj = MaximumUtility()), MeanRisk(; opt = opt, obj = MaximumRatio())]]]gs_cv = GridSearchCrossValidation(p; r = r, n_best = 3)GridSearchCrossValidation
p ┼ 4-element Vector{Union{Vector{Pair{String, StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}}}, Vector{Pair{String, Vector{MeanRisk{JuMPOptimiser{EmpiricalPrior{PortfolioOptimisersCovariance{Covariance{SimpleExpectedReturns{Nothing, Nothing, Nothing}, GeneralCovariance{SimpleCovariance, Nothing, Nothing}, FullMoment, Nothing, Nothing, Nothing}, MatrixProcessing{Posdef{UnionAll, @NamedTuple{}}, Nothing, Nothing, Nothing, NTuple{4, Symbol}}, Nothing}, SimpleExpectedReturns{Nothing, Nothing, Nothing}, Nothing, Nothing, Nothing, Nothing, Nothing}, Vector{Solver{Symbol, UnionAll, __T_settings, @NamedTuple{allow_local::Bool, allow_almost::Bool}, Bool} where __T_settings}, ConstraintBlock{WeightBounds{Float64, Float64}, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Bool}, Float64, Nothing, ArithmeticReturn{JuMPReturnsSettings{Float64, Nothing, Bool, Bool, Bool}, Nothing, Nothing, EigenFallbackSquareRoot}, Nothing, Int64, Int64, Bool, Nothing}, Variance{RiskMeasureSettings{Float64, Nothing, Bool}, Nothing, Nothing, Nothing, SquaredSOCRiskExpr, EigenFallbackSquareRoot, SquareRootRatio, Nothing}, __T_obj, Nothing, Nothing} where __T_obj}}}}}
cv ┼ KFold
│ n ┼ Int64: 5
│ purged_size ┼ Int64: 0
│ embargo_size ┼ Int64: 0
│ wd ┼ nothing
│ fa ┼ nothing
│ store_weight_path ┼ Bool: false
│ strict ┴ Bool: false
r ┼ MeanReturnRiskRatio
│ settings ┼ HierarchicalRiskMeasureSettings
│ │ scale ┴ Float64: 1.0
│ rt ┼ MeanReturn
│ │ settings ┼ HierarchicalRiskMeasureSettings
│ │ │ scale ┴ Float64: 1.0
│ │ w ┼ nothing
│ │ flag ┴ Bool: false
│ rk ┼ LowOrderMoment
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 1.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: true
│ │ w ┼ nothing
│ │ mu ┼ nothing
│ │ alg ┼ SecondMoment
│ │ │ ve ┼ SimpleVariance
│ │ │ │ me ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ corrected ┴ Bool: true
│ │ │ alg1 ┼ FullMoment()
│ │ │ alg2 ┴ SquaredSOCRiskExpr()
│ sca ┼ nothing
│ rf ┴ Float64: 0.0
r_sca ┼ nothing
scorer ┼ HighestMeanScore
│ scale ┴ Float64: 1.0
s_sca ┼ nothing
n_best ┼ Int64: 3
ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
train_score ┼ Bool: false
rank_prediction ┼ Bool: false
kwargs ┴ @NamedTuple{}: NamedTuple()
We run the search. The four grids give 3 × 3 + 3 + 3 + 2 = 17 candidates. The result has these fields.
optis the best estimator.test_scoreshas one row per fold and one column per candidate.train_scoresisnothingunless you settrain_score = true.lens_gridandval_gridgive the keys and the values of every candidate.idxis the index of the best candidate.rankedholds then_bestbest estimators, best first, soranked[1]isopt.rank_idxholds the column of each one intest_scores, andrank_scoresholds its mean test score.path_idsgives the path of each row oftest_scores. It isnothinghere, because the default scheme has one path.rank_predictionsisnothingunless you setrank_prediction = true. Section 2.3 shows it.
The best candidate has the highest mean test score. The search negates a measure for which a lower value is better, such as a risk measure, and keeps a ratio as it is. Here the measure is a ratio, and the highest mean ratio wins.
gs_res1 = search_cross_validation(st, gs_cv, rd)SearchCrossValidationResult
opt ┼ Stacking
│ pe ┼ EmpiricalPrior
│ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ ce ┼ Covariance
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ w ┴ nothing
│ │ │ │ alg ┼ FullMoment()
│ │ │ │ w ┴ nothing
│ │ │ mp ┼ MatrixProcessing
│ │ │ │ pdm ┼ Posdef
│ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ dn ┼ nothing
│ │ │ │ dt ┼ nothing
│ │ │ │ alg ┼ nothing
│ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ me ┼ SimpleExpectedReturns
│ │ │ w ┴ nothing
│ │ horizon ┼ nothing
│ │ fill_limit ┼ nothing
│ │ x_src ┴ nothing
│ wb ┼ nothing
│ fees ┼ nothing
│ sets ┼ nothing
│ scale ┼ nothing
│ opti ┼ 2-element Vector{Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult, TimeDependent{<:AbstractVector{<:Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult}}}, TimeDependent{<:TimeDependentOptimiserCallable}, TimeDependent{<:PreviousWeightsFunction}, TimeDependent{<:Union{Function, Type}}}}
│ │ MeanRisk ⋯
│ │ RiskBudgeting ⋯
│ opto ┼ MeanRisk
│ │ opt ┼ JuMPOptimiser
│ │ │ pe ┼ EmpiricalPrior
│ │ │ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ │ │ ce ┼ Covariance
│ │ │ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ alg ┼ FullMoment()
│ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ mp ┼ MatrixProcessing
│ │ │ │ │ │ pdm ┼ Posdef
│ │ │ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ │ │ dn ┼ nothing
│ │ │ │ │ │ dt ┼ nothing
│ │ │ │ │ │ alg ┼ nothing
│ │ │ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ horizon ┼ nothing
│ │ │ │ fill_limit ┼ nothing
│ │ │ │ x_src ┴ nothing
│ │ │ slv ┼ 7-element Vector{Solver}
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ cbe ┼ ConstraintBlock
│ │ │ │ wb ┼ WeightBounds
│ │ │ │ │ lb ┼ Float64: 0.0
│ │ │ │ │ ub ┴ Float64: 1.0
│ │ │ │ sbgt ┼ nothing
│ │ │ │ gbgt ┼ nothing
│ │ │ │ lt ┼ nothing
│ │ │ │ st ┼ nothing
│ │ │ │ lcse ┼ nothing
│ │ │ │ cte ┼ nothing
│ │ │ │ gcarde ┼ nothing
│ │ │ │ sgcarde ┼ nothing
│ │ │ │ smtx ┼ nothing
│ │ │ │ sgmtx ┼ nothing
│ │ │ │ slt ┼ nothing
│ │ │ │ sst ┼ nothing
│ │ │ │ sglt ┼ nothing
│ │ │ │ sgst ┼ nothing
│ │ │ │ tn ┼ nothing
│ │ │ │ sets ┼ nothing
│ │ │ │ tr ┼ nothing
│ │ │ │ ple ┼ nothing
│ │ │ │ ccnt ┼ nothing
│ │ │ │ cobj ┼ nothing
│ │ │ │ ss ┼ nothing
│ │ │ │ card ┼ nothing
│ │ │ │ scard ┼ nothing
│ │ │ │ l2c ┼ nothing
│ │ │ │ lpc ┼ nothing
│ │ │ │ linfc ┼ nothing
│ │ │ │ l1 ┼ nothing
│ │ │ │ l2 ┼ nothing
│ │ │ │ lp ┼ nothing
│ │ │ │ linf ┼ nothing
│ │ │ │ xbgt ┴ Bool: false
│ │ │ bgt ┼ Float64: 1.0
│ │ │ fees ┼ nothing
│ │ │ ret ┼ ArithmeticReturn
│ │ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ │ lb ┼ nothing
│ │ │ │ │ rte ┼ Bool: true
│ │ │ │ │ fee ┼ Bool: true
│ │ │ │ │ mic ┴ Bool: true
│ │ │ │ ucs ┼ nothing
│ │ │ │ mu ┼ nothing
│ │ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ │ sca ┼ nothing
│ │ │ sc ┼ Int64: 1
│ │ │ so ┼ Int64: 1
│ │ │ strict ┴ Bool: false
│ │ r ┼ Variance
│ │ │ settings ┼ RiskMeasureSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ ub ┼ nothing
│ │ │ │ rke ┴ Bool: true
│ │ │ sigma ┼ nothing
│ │ │ chol ┼ nothing
│ │ │ rc ┼ nothing
│ │ │ alg ┼ SquaredSOCRiskExpr()
│ │ │ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ │ │ ratio_alg ┼ SquareRootRatio()
│ │ │ corner ┴ nothing
│ │ obj ┼ MinimumRisk()
│ │ wi ┼ nothing
│ │ fb ┴ nothing
│ cv ┼ nothing
│ scorer ┼ nothing
│ wf ┼ IterativeWeightFinaliser
│ │ iter ┴ Int64: 100
│ ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
│ fb ┼ nothing
│ strict ┼ Bool: false
│ pcol ┴ RenormaliseActive()
test_scores ┼ 5×17 Matrix{Float64}
train_scores ┼ nothing
lens_grid ┼ 17-element Vector{Vector{ComposedFunction{O, Accessors.PropertyLens{:opti}} where O}}
val_grid ┼ 17-element Vector{Tuple{Any, Vararg{Float64}}}
idx ┼ Int64: 6
ranked ┼ 3-element Vector{Stacking}
│ Stacking ⋯
│ Stacking ⋯
│ Stacking ⋯
rank_idx ┼ Vector{Int64}: [6, 5, 4]
rank_scores ┼ Vector{Float64}: [10.591679129275379, 10.591679126817867, 10.591679125380358]
rank_predictions ┼ nothing
path_ids ┴ nothing
The table gives the keys and the values of the best candidate. The loop after it prints every value next to the same field read from the chosen estimator.
pretty_table(DataFrame("Lens" => gs_res1.lens_grid[gs_res1.idx], "Value" => collect(gs_res1.val_grid[gs_res1.idx])))for (lens, val) in zip(gs_res1.lens_grid[gs_res1.idx], gs_res1.val_grid[gs_res1.idx]) println("$(lpad("lens:", 12)) $lens\n$(lpad("val:", 12)) $val\n$(lpad("Field value:", 12)) $(lens(gs_res1.opt))\n")end┌────────────────────────────────────────────────────────────┬─────────┐
│ Lens │ Value │
│ ComposedFunction{O, Accessors.PropertyLens{:opti}} where O │ Float64 │
├────────────────────────────────────────────────────────────┼─────────┤
│ _.opti[2].opt.l1 │ 0.0008 │
│ _.opti[1].opt.l2.val │ 0.00055 │
└────────────────────────────────────────────────────────────┴─────────┘
lens: (@o _.opti[2].opt.l1)
val: 0.0008
Field value: 0.0008
lens: (@o _.opti[1].opt.l2.val)
val: 0.00055
Field value: 0.00055We optimise the best estimator on the full data and plot its weights.
using StatsPlotsres_gs1 = optimise(gs_res1.opt, rd)plot_composition(res_gs1, rd)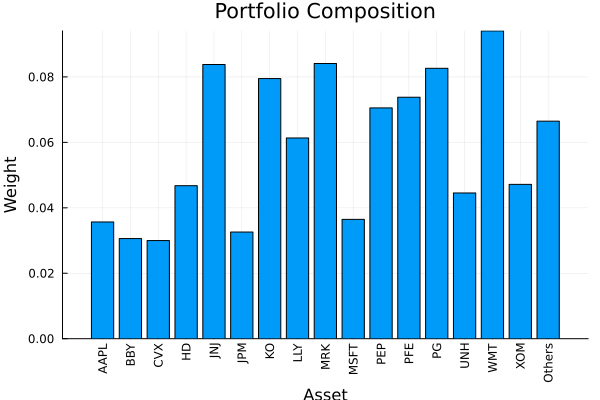
The search keeps configurations, not fitted results. The table gives the column, the mean test score and the standard deviation of the test scores over the folds of each kept candidate. We optimise each kept candidate on the full data, as we did for opt.
pretty_table(DataFrame("Rank" => eachindex(gs_res1.ranked), "Column" => gs_res1.rank_idx, "Mean score" => gs_res1.rank_scores, "Std score" => vec(std(gs_res1.test_scores[:, gs_res1.rank_idx]; dims = 1))))res_ranked = [optimise(cand, rd) for cand in gs_res1.ranked]plot_composition(res_ranked[2], rd)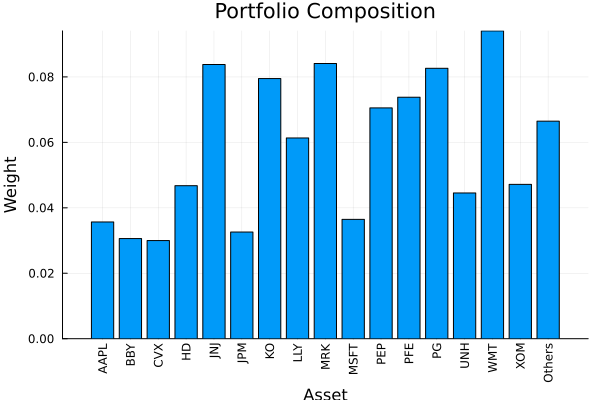
2.2 Randomised cross validation search
RandomisedSearchCrossValidation draws n_iter trials from the grid, and then runs a grid search over the trials with search_cross_validation. It takes the same grids as GridSearchCrossValidation. A parameter can also take a Distributions.Distribution in place of a vector of values.
A trial is one candidate. It sets every parameter of one grid at the same time, so the search fits n_iter candidates, however many parameters it tunes.
- If every value is a vector, the search draws
n_iterdistinct candidates of the grid search, each with the same probability. It keeps them in the order of the grid search. If the grid holdsn_itercandidates or fewer, the search takes all of them. - If a value is a distribution, each trial picks one grid with equal probability. Then it draws one value from each distribution and one entry from each vector of that grid. Two trials can then be the same.
The search draws from one random number generator, rng, trial by trial and parameter by parameter. The order of the grids and of the parameters therefore changes the trials. To repeat a search, keep that order fixed. Use an OrderedDict from OrderedCollections or a vector for each grid.
2.2.1 Sampling from a predefined parameter space
We sample from the same grids as before, with n_iter = 8. Every value is in a vector, so the search draws 8 of the 17 candidates of the grid search, without replacement.
rs_cv1 = RandomisedSearchCrossValidation(p; rng = StableRNG(42), r = r, n_iter = 8)RandomisedSearchCrossValidation
p ┼ 4-element Vector{Union{Vector{Pair{String, StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}}}, Vector{Pair{String, Vector{MeanRisk{JuMPOptimiser{EmpiricalPrior{PortfolioOptimisersCovariance{Covariance{SimpleExpectedReturns{Nothing, Nothing, Nothing}, GeneralCovariance{SimpleCovariance, Nothing, Nothing}, FullMoment, Nothing, Nothing, Nothing}, MatrixProcessing{Posdef{UnionAll, @NamedTuple{}}, Nothing, Nothing, Nothing, NTuple{4, Symbol}}, Nothing}, SimpleExpectedReturns{Nothing, Nothing, Nothing}, Nothing, Nothing, Nothing, Nothing, Nothing}, Vector{Solver{Symbol, UnionAll, __T_settings, @NamedTuple{allow_local::Bool, allow_almost::Bool}, Bool} where __T_settings}, ConstraintBlock{WeightBounds{Float64, Float64}, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Bool}, Float64, Nothing, ArithmeticReturn{JuMPReturnsSettings{Float64, Nothing, Bool, Bool, Bool}, Nothing, Nothing, EigenFallbackSquareRoot}, Nothing, Int64, Int64, Bool, Nothing}, Variance{RiskMeasureSettings{Float64, Nothing, Bool}, Nothing, Nothing, Nothing, SquaredSOCRiskExpr, EigenFallbackSquareRoot, SquareRootRatio, Nothing}, __T_obj, Nothing, Nothing} where __T_obj}}}}}
cv ┼ KFold
│ n ┼ Int64: 5
│ purged_size ┼ Int64: 0
│ embargo_size ┼ Int64: 0
│ wd ┼ nothing
│ fa ┼ nothing
│ store_weight_path ┼ Bool: false
│ strict ┴ Bool: false
r ┼ MeanReturnRiskRatio
│ settings ┼ HierarchicalRiskMeasureSettings
│ │ scale ┴ Float64: 1.0
│ rt ┼ MeanReturn
│ │ settings ┼ HierarchicalRiskMeasureSettings
│ │ │ scale ┴ Float64: 1.0
│ │ w ┼ nothing
│ │ flag ┴ Bool: false
│ rk ┼ LowOrderMoment
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 1.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: true
│ │ w ┼ nothing
│ │ mu ┼ nothing
│ │ alg ┼ SecondMoment
│ │ │ ve ┼ SimpleVariance
│ │ │ │ me ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ corrected ┴ Bool: true
│ │ │ alg1 ┼ FullMoment()
│ │ │ alg2 ┴ SquaredSOCRiskExpr()
│ sca ┼ nothing
│ rf ┴ Float64: 0.0
r_sca ┼ nothing
scorer ┼ HighestMeanScore
│ scale ┴ Float64: 1.0
s_sca ┼ nothing
n_best ┼ Int64: 1
ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
n_iter ┼ Int64: 8
rng ┼ StableRNGs.LehmerRNG: StableRNGs.LehmerRNG(state=0x00000000000000000000000000000055)
seed ┼ nothing
train_score ┼ Bool: false
rank_prediction ┼ Bool: false
kwargs ┴ @NamedTuple{}: NamedTuple()
The search fits 8 candidates, where the grid search fitted 17.
rs_res1 = search_cross_validation(st, rs_cv1, rd)SearchCrossValidationResult
opt ┼ Stacking
│ pe ┼ EmpiricalPrior
│ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ ce ┼ Covariance
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ w ┴ nothing
│ │ │ │ alg ┼ FullMoment()
│ │ │ │ w ┴ nothing
│ │ │ mp ┼ MatrixProcessing
│ │ │ │ pdm ┼ Posdef
│ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ dn ┼ nothing
│ │ │ │ dt ┼ nothing
│ │ │ │ alg ┼ nothing
│ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ me ┼ SimpleExpectedReturns
│ │ │ w ┴ nothing
│ │ horizon ┼ nothing
│ │ fill_limit ┼ nothing
│ │ x_src ┴ nothing
│ wb ┼ nothing
│ fees ┼ nothing
│ sets ┼ nothing
│ scale ┼ nothing
│ opti ┼ 2-element Vector{Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult, TimeDependent{<:AbstractVector{<:Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult}}}, TimeDependent{<:TimeDependentOptimiserCallable}, TimeDependent{<:PreviousWeightsFunction}, TimeDependent{<:Union{Function, Type}}}}
│ │ MeanRisk ⋯
│ │ RiskBudgeting ⋯
│ opto ┼ MeanRisk
│ │ opt ┼ JuMPOptimiser
│ │ │ pe ┼ EmpiricalPrior
│ │ │ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ │ │ ce ┼ Covariance
│ │ │ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ alg ┼ FullMoment()
│ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ mp ┼ MatrixProcessing
│ │ │ │ │ │ pdm ┼ Posdef
│ │ │ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ │ │ dn ┼ nothing
│ │ │ │ │ │ dt ┼ nothing
│ │ │ │ │ │ alg ┼ nothing
│ │ │ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ horizon ┼ nothing
│ │ │ │ fill_limit ┼ nothing
│ │ │ │ x_src ┴ nothing
│ │ │ slv ┼ 7-element Vector{Solver}
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ cbe ┼ ConstraintBlock
│ │ │ │ wb ┼ WeightBounds
│ │ │ │ │ lb ┼ Float64: 0.0
│ │ │ │ │ ub ┴ Float64: 1.0
│ │ │ │ sbgt ┼ nothing
│ │ │ │ gbgt ┼ nothing
│ │ │ │ lt ┼ nothing
│ │ │ │ st ┼ nothing
│ │ │ │ lcse ┼ nothing
│ │ │ │ cte ┼ nothing
│ │ │ │ gcarde ┼ nothing
│ │ │ │ sgcarde ┼ nothing
│ │ │ │ smtx ┼ nothing
│ │ │ │ sgmtx ┼ nothing
│ │ │ │ slt ┼ nothing
│ │ │ │ sst ┼ nothing
│ │ │ │ sglt ┼ nothing
│ │ │ │ sgst ┼ nothing
│ │ │ │ tn ┼ nothing
│ │ │ │ sets ┼ nothing
│ │ │ │ tr ┼ nothing
│ │ │ │ ple ┼ nothing
│ │ │ │ ccnt ┼ nothing
│ │ │ │ cobj ┼ nothing
│ │ │ │ ss ┼ nothing
│ │ │ │ card ┼ nothing
│ │ │ │ scard ┼ nothing
│ │ │ │ l2c ┼ nothing
│ │ │ │ lpc ┼ nothing
│ │ │ │ linfc ┼ nothing
│ │ │ │ l1 ┼ nothing
│ │ │ │ l2 ┼ nothing
│ │ │ │ lp ┼ nothing
│ │ │ │ linf ┼ nothing
│ │ │ │ xbgt ┴ Bool: false
│ │ │ bgt ┼ Float64: 1.0
│ │ │ fees ┼ nothing
│ │ │ ret ┼ ArithmeticReturn
│ │ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ │ lb ┼ nothing
│ │ │ │ │ rte ┼ Bool: true
│ │ │ │ │ fee ┼ Bool: true
│ │ │ │ │ mic ┴ Bool: true
│ │ │ │ ucs ┼ nothing
│ │ │ │ mu ┼ nothing
│ │ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ │ sca ┼ nothing
│ │ │ sc ┼ Int64: 1
│ │ │ so ┼ Int64: 1
│ │ │ strict ┴ Bool: false
│ │ r ┼ Variance
│ │ │ settings ┼ RiskMeasureSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ ub ┼ nothing
│ │ │ │ rke ┴ Bool: true
│ │ │ sigma ┼ nothing
│ │ │ chol ┼ nothing
│ │ │ rc ┼ nothing
│ │ │ alg ┼ SquaredSOCRiskExpr()
│ │ │ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ │ │ ratio_alg ┼ SquareRootRatio()
│ │ │ corner ┴ nothing
│ │ obj ┼ MinimumRisk()
│ │ wi ┼ nothing
│ │ fb ┴ nothing
│ cv ┼ nothing
│ scorer ┼ nothing
│ wf ┼ IterativeWeightFinaliser
│ │ iter ┴ Int64: 100
│ ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
│ fb ┼ nothing
│ strict ┼ Bool: false
│ pcol ┴ RenormaliseActive()
test_scores ┼ 5×8 Matrix{Float64}
train_scores ┼ nothing
lens_grid ┼ 8-element Vector{Vector{ComposedFunction{O, Accessors.PropertyLens{:opti}} where O}}
val_grid ┼ 8-element Vector{Tuple{Any, Vararg{Float64}}}
idx ┼ Int64: 4
ranked ┼ 1-element Vector{Stacking}
│ Stacking ⋯
rank_idx ┼ Vector{Int64}: [4]
rank_scores ┼ Vector{Float64}: [10.591679129275379]
rank_predictions ┼ nothing
path_ids ┴ nothing
We read the best candidate of the randomised search in the same way.
pretty_table(DataFrame("Lens" => rs_res1.lens_grid[rs_res1.idx], "Value" => collect(rs_res1.val_grid[rs_res1.idx])))for (lens, val) in zip(rs_res1.lens_grid[rs_res1.idx], rs_res1.val_grid[rs_res1.idx]) println("$(lpad("lens:", 12)) $lens\n$(lpad("val:", 12)) $val\n$(lpad("Field value:", 12)) $(lens(rs_res1.opt))\n")endres_rs1 = optimise(rs_res1.opt, rd)plot_composition(res_rs1, rd)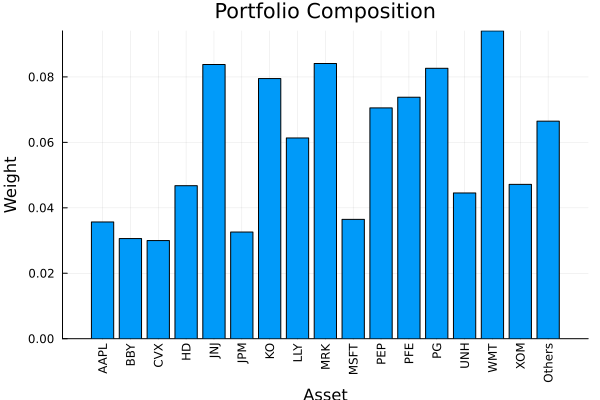
2.2.2 Sampling from a distribution
We now mix vectors and distributions, with n_iter = 10. The constructor of RandomisedSearchCrossValidation checks that every value is a vector or a distribution.
p = [["opti[2].opt.l1" => range(; start = 0.0005, stop = 0.0008, length = 3), "opti[1].opt.l2.val" => LogUniform(0.0003, 0.1)], ["opti[1].opt.l2.val" => LogUniform(0.001, 0.1)], ["opti[2].opt.l1" => range(; start = 0.0009, stop = 0.0012, length = 3)], ["opti[2]" => [MeanRisk(; opt = opt, obj = MaximumUtility()), MeanRisk(; opt = opt, obj = MaximumRatio())]]]rs_cv2 = RandomisedSearchCrossValidation(p; rng = StableRNG(42), r = r, n_iter = 10)RandomisedSearchCrossValidation
p ┼ 4-element Vector{Vector{Pair{String, Any}}}
cv ┼ KFold
│ n ┼ Int64: 5
│ purged_size ┼ Int64: 0
│ embargo_size ┼ Int64: 0
│ wd ┼ nothing
│ fa ┼ nothing
│ store_weight_path ┼ Bool: false
│ strict ┴ Bool: false
r ┼ MeanReturnRiskRatio
│ settings ┼ HierarchicalRiskMeasureSettings
│ │ scale ┴ Float64: 1.0
│ rt ┼ MeanReturn
│ │ settings ┼ HierarchicalRiskMeasureSettings
│ │ │ scale ┴ Float64: 1.0
│ │ w ┼ nothing
│ │ flag ┴ Bool: false
│ rk ┼ LowOrderMoment
│ │ settings ┼ RiskMeasureSettings
│ │ │ scale ┼ Float64: 1.0
│ │ │ ub ┼ nothing
│ │ │ rke ┴ Bool: true
│ │ w ┼ nothing
│ │ mu ┼ nothing
│ │ alg ┼ SecondMoment
│ │ │ ve ┼ SimpleVariance
│ │ │ │ me ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ corrected ┴ Bool: true
│ │ │ alg1 ┼ FullMoment()
│ │ │ alg2 ┴ SquaredSOCRiskExpr()
│ sca ┼ nothing
│ rf ┴ Float64: 0.0
r_sca ┼ nothing
scorer ┼ HighestMeanScore
│ scale ┴ Float64: 1.0
s_sca ┼ nothing
n_best ┼ Int64: 1
ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
n_iter ┼ Int64: 10
rng ┼ StableRNGs.LehmerRNG: StableRNGs.LehmerRNG(state=0x00000000000000000000000000000055)
seed ┼ nothing
train_score ┼ Bool: false
rank_prediction ┼ Bool: false
kwargs ┴ @NamedTuple{}: NamedTuple()
Two grids hold a distribution, so each of the 10 trials picks one of the four grids with equal probability. A trial of the first grid draws one value of opti[1].opt.l2.val from its distribution and one of the three values of opti[2].opt.l1. A trial of the fourth grid picks one of the two estimators. That makes 10 candidates. Two trials of the fourth grid can pick the same estimator, and then two candidates are the same.
rs_res2 = search_cross_validation(st, rs_cv2, rd)SearchCrossValidationResult
opt ┼ Stacking
│ pe ┼ EmpiricalPrior
│ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ ce ┼ Covariance
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ w ┴ nothing
│ │ │ │ alg ┼ FullMoment()
│ │ │ │ w ┴ nothing
│ │ │ mp ┼ MatrixProcessing
│ │ │ │ pdm ┼ Posdef
│ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ dn ┼ nothing
│ │ │ │ dt ┼ nothing
│ │ │ │ alg ┼ nothing
│ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ me ┼ SimpleExpectedReturns
│ │ │ w ┴ nothing
│ │ horizon ┼ nothing
│ │ fill_limit ┼ nothing
│ │ x_src ┴ nothing
│ wb ┼ nothing
│ fees ┼ nothing
│ sets ┼ nothing
│ scale ┼ nothing
│ opti ┼ 2-element Vector{Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult, TimeDependent{<:AbstractVector{<:Union{NonFiniteAllocationOptimisationEstimator, NonFiniteAllocationOptimisationResult}}}, TimeDependent{<:TimeDependentOptimiserCallable}, TimeDependent{<:PreviousWeightsFunction}, TimeDependent{<:Union{Function, Type}}}}
│ │ MeanRisk ⋯
│ │ RiskBudgeting ⋯
│ opto ┼ MeanRisk
│ │ opt ┼ JuMPOptimiser
│ │ │ pe ┼ EmpiricalPrior
│ │ │ │ ce ┼ PortfolioOptimisersCovariance
│ │ │ │ │ ce ┼ Covariance
│ │ │ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ ce ┼ GeneralCovariance
│ │ │ │ │ │ │ ce ┼ SimpleCovariance: SimpleCovariance(true)
│ │ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ │ alg ┼ FullMoment()
│ │ │ │ │ │ w ┴ nothing
│ │ │ │ │ mp ┼ MatrixProcessing
│ │ │ │ │ │ pdm ┼ Posdef
│ │ │ │ │ │ │ alg ┼ UnionAll: NearestCorrelationMatrix.Newton
│ │ │ │ │ │ │ kwargs ┴ @NamedTuple{}: NamedTuple()
│ │ │ │ │ │ dn ┼ nothing
│ │ │ │ │ │ dt ┼ nothing
│ │ │ │ │ │ alg ┼ nothing
│ │ │ │ │ │ order ┴ NTuple{4, Symbol}: (:pdm, :dn, :dt, :alg)
│ │ │ │ me ┼ SimpleExpectedReturns
│ │ │ │ │ w ┴ nothing
│ │ │ │ horizon ┼ nothing
│ │ │ │ fill_limit ┼ nothing
│ │ │ │ x_src ┴ nothing
│ │ │ slv ┼ 7-element Vector{Solver}
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ │ Solver ⋯
│ │ │ cbe ┼ ConstraintBlock
│ │ │ │ wb ┼ WeightBounds
│ │ │ │ │ lb ┼ Float64: 0.0
│ │ │ │ │ ub ┴ Float64: 1.0
│ │ │ │ sbgt ┼ nothing
│ │ │ │ gbgt ┼ nothing
│ │ │ │ lt ┼ nothing
│ │ │ │ st ┼ nothing
│ │ │ │ lcse ┼ nothing
│ │ │ │ cte ┼ nothing
│ │ │ │ gcarde ┼ nothing
│ │ │ │ sgcarde ┼ nothing
│ │ │ │ smtx ┼ nothing
│ │ │ │ sgmtx ┼ nothing
│ │ │ │ slt ┼ nothing
│ │ │ │ sst ┼ nothing
│ │ │ │ sglt ┼ nothing
│ │ │ │ sgst ┼ nothing
│ │ │ │ tn ┼ nothing
│ │ │ │ sets ┼ nothing
│ │ │ │ tr ┼ nothing
│ │ │ │ ple ┼ nothing
│ │ │ │ ccnt ┼ nothing
│ │ │ │ cobj ┼ nothing
│ │ │ │ ss ┼ nothing
│ │ │ │ card ┼ nothing
│ │ │ │ scard ┼ nothing
│ │ │ │ l2c ┼ nothing
│ │ │ │ lpc ┼ nothing
│ │ │ │ linfc ┼ nothing
│ │ │ │ l1 ┼ nothing
│ │ │ │ l2 ┼ nothing
│ │ │ │ lp ┼ nothing
│ │ │ │ linf ┼ nothing
│ │ │ │ xbgt ┴ Bool: false
│ │ │ bgt ┼ Float64: 1.0
│ │ │ fees ┼ nothing
│ │ │ ret ┼ ArithmeticReturn
│ │ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ │ lb ┼ nothing
│ │ │ │ │ rte ┼ Bool: true
│ │ │ │ │ fee ┼ Bool: true
│ │ │ │ │ mic ┴ Bool: true
│ │ │ │ ucs ┼ nothing
│ │ │ │ mu ┼ nothing
│ │ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ │ sca ┼ nothing
│ │ │ sc ┼ Int64: 1
│ │ │ so ┼ Int64: 1
│ │ │ strict ┴ Bool: false
│ │ r ┼ Variance
│ │ │ settings ┼ RiskMeasureSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ ub ┼ nothing
│ │ │ │ rke ┴ Bool: true
│ │ │ sigma ┼ nothing
│ │ │ chol ┼ nothing
│ │ │ rc ┼ nothing
│ │ │ alg ┼ SquaredSOCRiskExpr()
│ │ │ mtx_sqrt ┼ EigenFallbackSquareRoot()
│ │ │ ratio_alg ┼ SquareRootRatio()
│ │ │ corner ┴ nothing
│ │ obj ┼ MinimumRisk()
│ │ wi ┼ nothing
│ │ fb ┴ nothing
│ cv ┼ nothing
│ scorer ┼ nothing
│ wf ┼ IterativeWeightFinaliser
│ │ iter ┴ Int64: 100
│ ex ┼ Transducers.ThreadedEx{@NamedTuple{}}: Transducers.ThreadedEx()
│ fb ┼ nothing
│ strict ┼ Bool: false
│ pcol ┴ RenormaliseActive()
test_scores ┼ 5×10 Matrix{Float64}
train_scores ┼ nothing
lens_grid ┼ 10-element Vector{Vector{ComposedFunction{O, Accessors.PropertyLens{:opti}} where O}}
val_grid ┼ 10-element Vector{Tuple{Any, Vararg{Float64}}}
idx ┼ Int64: 2
ranked ┼ 1-element Vector{Stacking}
│ Stacking ⋯
rank_idx ┼ Vector{Int64}: [2]
rank_scores ┼ Vector{Float64}: [10.500653442663225]
rank_predictions ┼ nothing
path_ids ┴ nothing
We read off the best candidate of the second search.
pretty_table(DataFrame("Lens" => rs_res2.lens_grid[rs_res2.idx], "Value" => collect(rs_res2.val_grid[rs_res2.idx])))for (lens, val) in zip(rs_res2.lens_grid[rs_res2.idx], rs_res2.val_grid[rs_res2.idx]) println("$(lpad("lens:", 12)) $lens\n$(lpad("val:", 12)) $val\n$(lpad("Field value:", 12)) $(lens(rs_res2.opt))\n")endres_rs2 = optimise(rs_res2.opt, rd)plot_composition(res_rs2, rd)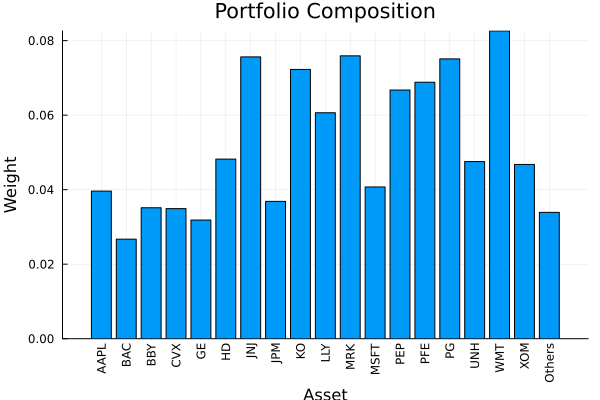
The plot puts the weights of the three best portfolios side by side: the grid search, the randomised search over vectors, and the randomised search with distributions.
plot_stacked_bar_composition([res_gs1, res_rs1, res_rs2], rd)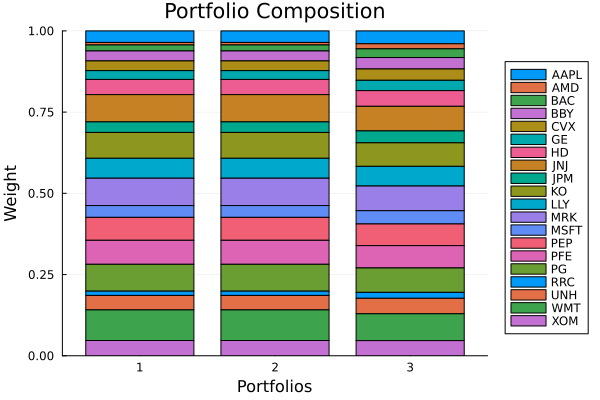
2.3 Many risk measures and many search scorers
A search can score each fold with a vector of risk measures in r, and order the candidates with a vector of search scorers in scorer. We score with a ratio and with a risk measure. A higher ratio is better, and a lower risk is better. The search orients each measure before it combines them. It negates a measure for which a lower value is better, and multiplies each value by the scale of its measure. So every score is higher-is-better, and two measures of mixed orientation can share one vector.
We search a grid of nine candidates. The ratio divides the mean return by the ConditionalValueatRisk, so the two measures have values of about the same size.
p_mm = [["opti[2].opt.l1" => [0.0005, 0.001, 0.002], "opti[1].opt.l2.val" => [0.0005, 0.005, 0.05]]]r_mm = [MeanReturnRiskRatio(; rk = ConditionalValueatRisk()), ConditionalValueatRisk()]2-element Vector{AbstractBaseRiskMeasure}:
MeanReturnRiskRatio
settings ┼ HierarchicalRiskMeasureSettings
│ scale ┴ Float64: 1.0
rt ┼ MeanReturn
│ settings ┼ HierarchicalRiskMeasureSettings
│ │ scale ┴ Float64: 1.0
│ w ┼ nothing
│ flag ┴ Bool: false
rk ┼ ConditionalValueatRisk
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ alpha ┼ Float64: 0.05
│ w ┴ nothing
sca ┼ nothing
rf ┴ Float64: 0.0
ConditionalValueatRisk
settings ┼ RiskMeasureSettings
│ scale ┼ Float64: 1.0
│ ub ┼ nothing
│ rke ┴ Bool: true
alpha ┼ Float64: 0.05
w ┴ nothing
2.3.1 One score for each fold
The field r_sca combines the measures in each fold. Its default nothing gives the sum, so the score of a fold is the ratio minus the CVaR. test_scores is one matrix, as for one measure, and the search gives one ranking.
mm_sum = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm), rd);size(mm_sum.test_scores), mm_sum.idx((5, 9), 1)2.3.2 One ranking for each measure
EachValue in r_sca does not combine the measures. The search keeps one score matrix for each measure, and ranks the candidates by each measure apart, as the multi-metric search of sklearn does. opt, idx, ranked, rank_idx and rank_scores then hold one entry for each measure, in the order of r, and so does rank_predictions under rank_prediction = true.
mm_each = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm, r_sca = EachValue()), rd);pretty_table(DataFrame("Measure" => ["Ratio", "CVaR"], "Column" => mm_each.idx, "Mean score" => [s[1] for s in mm_each.rank_scores]))┌─────────┬────────┬────────────┐
│ Measure │ Column │ Mean score │
│ String │ Int64 │ Float64 │
├─────────┼────────┼────────────┤
│ Ratio │ 9 │ 0.0337414 │
│ CVaR │ 1 │ -0.0264294 │
└─────────┴────────┴────────────┘The search takes no refit, where sklearn takes a refit argument. A refit is a call to optimise. We fit the winner of each measure on the full data and compare the weights.
res_each = [optimise(o, rd) for o in mm_each.opt]plot_stacked_bar_composition(res_each, rd)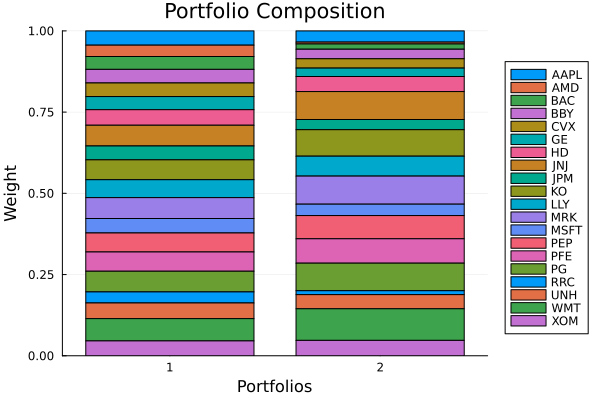
2.3.3 Combine the measures in each fold, or once for each candidate
A reduction in r_sca combines the measures in each fold, and then the search scorer reduces the folds. PerCandidate(sca) takes the two stages in the other order. The search scorer reduces the folds of each measure, and then sca combines the values of each candidate. For the sum and HighestMeanScore the two orders give the same value, because the mean of a sum is the sum of the means. For a scorer that is not linear in the folds, the two orders differ.
A search scorer can be a function. It reads the score matrix, with one row per fold and one column per candidate, and returns one value per column, higher is better. worst_fold scores a candidate by its worst fold.
worst_fold(X) = vec(minimum(X; dims = 1))mm_fold = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm, scorer = worst_fold), rd);mm_cand = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm, r_sca = PerCandidate(), scorer = worst_fold), rd);pretty_table(DataFrame("r_sca" => ["nothing", "PerCandidate()"], "Column" => [mm_fold.idx, mm_cand.idx], "Score" => [mm_fold.rank_scores[1], mm_cand.rank_scores[1]]))┌────────────────┬────────┬────────────┐
│ r_sca │ Column │ Score │
│ String │ Int64 │ Float64 │
├────────────────┼────────┼────────────┤
│ nothing │ 7 │ -0.0377149 │
│ PerCandidate() │ 1 │ -0.0448777 │
└────────────────┴────────┴────────────┘The first search keeps the candidate whose worst fold has the highest sum of the two scores. The second search keeps the candidate with the highest sum of its worst ratio and its worst CVaR. The two worst values can come from different folds. Under PerCandidate, test_scores holds one matrix for each measure, as under EachValue(), but the search gives one ranking.
2.3.4 Many search scorers, and the predictions of the kept candidates
scorer takes a vector of search scorers. The field s_sca combines the values of the scorers of each candidate. Its default nothing gives the sum, and each built-in scorer holds a scale, its weight in the sum. Here each candidate scores the sum of its mean and of its worst fold.
mm_ssum = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm, scorer = [HighestMeanScore(), worst_fold]), rd);mm_ssum.idx, mm_ssum.rank_scores(7, [-0.03202023692535314])s_sca = EachValue() lets each scorer rank the candidates alone. Under EachValue() in both r_sca and s_sca, the search keeps a K × L matrix of rankings, with row k for measure k and column l for scorer l. We keep the two best candidates of each ranking.
rank_prediction = true also keeps the prediction that the search scored for each kept candidate. A prediction holds one optimisation Result for each fold, so the switch costs memory for every candidate of the grid until the search ends. Its default is false.
mm_kl = search_cross_validation(st, GridSearchCrossValidation(p_mm; r = r_mm, r_sca = EachValue(), scorer = [HighestMeanScore(), worst_fold], s_sca = EachValue(), n_best = 2, rank_prediction = true), rd);pretty_table(DataFrame("Measure" => ["Ratio", "CVaR"], "Mean" => mm_kl.idx[:, 1], "Worst fold" => mm_kl.idx[:, 2]))┌─────────┬───────┬────────────┐
│ Measure │ Mean │ Worst fold │
│ String │ Int64 │ Int64 │
├─────────┼───────┼────────────┤
│ Ratio │ 9 │ 1 │
│ CVaR │ 1 │ 1 │
└─────────┴───────┴────────────┘mm_kl.opt[k, l] is the winner of measure k under scorer l. We fit the winner of the CVaR under the worst fold on the full data.
res_kl = optimise(mm_kl.opt[2, 2], rd)plot_composition(res_kl, rd)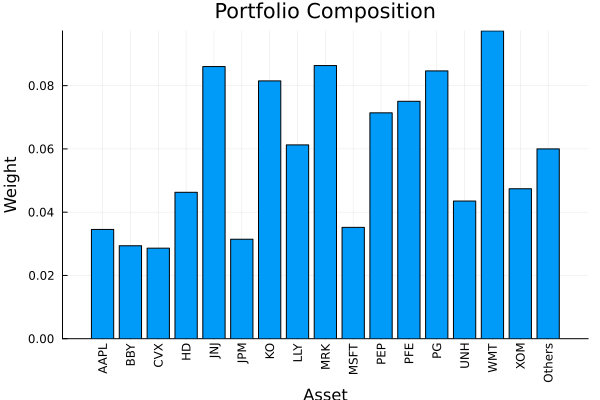
mm_kl.rank_predictions[k, l][j] is the prediction of the candidate mm_kl.ranked[k, l][j]. It is the object that the search scored, with no copy and no refit. The risk of each fold of the prediction, with the sign of the search, gives the column of the candidate in test_scores. The CVaR is a risk measure, so its sign is negative.
pred_kl = mm_kl.rank_predictions[2, 2][1]pretty_table(DataFrame("Fold" => eachindex(pred_kl.pred), "-CVaR of the prediction" => [-expected_risk(r_mm[2], p) for p in pred_kl.pred], "test_scores" => mm_kl.test_scores[2][:, mm_kl.rank_idx[2, 2][1]]))┌───────┬─────────────────────────┬─────────────┐
│ Fold │ -CVaR of the prediction │ test_scores │
│ Int64 │ Float64 │ Float64 │
├───────┼─────────────────────────┼─────────────┤
│ 1 │ -0.0250827 │ -0.0250827 │
│ 2 │ -0.0160159 │ -0.0160159 │
│ 3 │ -0.0521854 │ -0.0521854 │
│ 4 │ -0.0152615 │ -0.0152615 │
│ 5 │ -0.0236015 │ -0.0236015 │
└───────┴─────────────────────────┴─────────────┘A kept prediction goes into the same functions as the output of cross_val_predict. plot_cv_scores plots the CVaR of each fold of the winner.
plot_cv_scores(r_mm[2], pred_kl)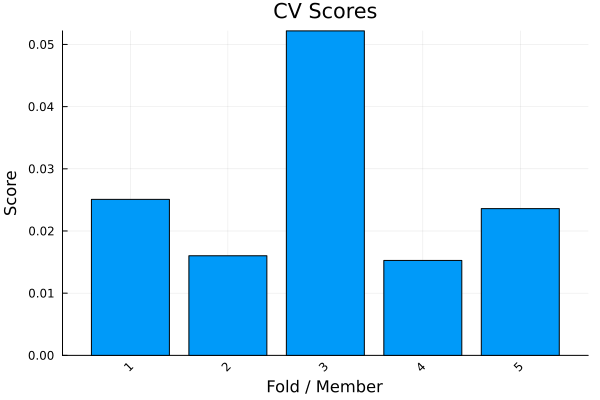
You can tune any estimator that cross-validation accepts. You can also tune a Pipeline, and the pipelines example tunes an asset filter and a gap fill.
This page was generated using Literate.jl.