The source files can be found in examples/.
Regularisation
This example shows one of the simplest ways to improve the robustness of portfolios, regularisation penalties.
Section 2 states every coefficient as a number. Section 3 puts a Calibration Rule in the same slots, which computes the number from the sample in front of it, and it adds the three norm ceilings l2c, lpc and linfc that bound a norm rather than price one.
using PortfolioOptimisers, PrettyTables# Format for pretty tables.tsfmt = (v, i, j) -> begin if j == 1 return Date(v) else return v endend;resfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v*100, digits=3)) %" : v endend;mmtfmt = (v, i, j) -> begin if i == j == 1 return v else return isa(v, Number) ? "$(round(v*100, digits=3)) %" : v endend;summary_row = (data, j) -> begin if j == 1 return "N/A" else return number_effective_assets(data[:, j]) endend#11 (generic function with 1 method)1. Setting up
We will use the same data as the previous example.
using CSV, TimeSeries, DataFrames, ClarabelX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]pretty_table(X[(end - 5):end]; formatters = [tsfmt])# Compute the returnsrd = prices_to_returns(X)pr = prior(EmpiricalPrior(), rd)slv = [Solver(; name = :clarabel1, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel2, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.95), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel3, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.9), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel4, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.85), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel5, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.8), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel6, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.75), check_sol = (; allow_local = true, allow_almost = true)), Solver(; name = :clarabel7, solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => 0.70), check_sol = (; allow_local = true, allow_almost = true))];┌────────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┐
│ timestamp │ AAPL │ AMD │ BAC │ BBY │ CVX │ GE │ HD │ JNJ │ JPM │ KO │ LLY │ MRK │ MSFT │ PEP │ PFE │ PG │ RRC │ UNH │ WMT │ XOM │
│ Date │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┤
│ 2022-12-20 │ 131.916 │ 65.05 │ 31.729 │ 77.371 │ 169.497 │ 62.604 │ 310.342 │ 173.109 │ 127.844 │ 61.841 │ 357.55 │ 108.229 │ 240.67 │ 178.765 │ 49.754 │ 147.661 │ 25.65 │ 516.245 │ 142.919 │ 104.964 │
│ 2022-12-21 │ 135.057 │ 67.68 │ 32.212 │ 78.729 │ 171.49 │ 64.67 │ 314.798 │ 175.09 │ 129.282 │ 62.836 │ 365.872 │ 109.611 │ 243.287 │ 180.017 │ 50.084 │ 149.015 │ 26.574 │ 523.519 │ 144.04 │ 106.312 │
│ 2022-12-22 │ 131.846 │ 63.86 │ 31.927 │ 78.563 │ 168.918 │ 63.727 │ 311.604 │ 174.45 │ 127.814 │ 62.383 │ 363.187 │ 109.739 │ 237.077 │ 178.627 │ 50.065 │ 149.359 │ 25.232 │ 523.072 │ 142.354 │ 104.168 │
│ 2022-12-23 │ 131.477 │ 64.52 │ 32.005 │ 79.432 │ 174.14 │ 63.742 │ 314.177 │ 174.893 │ 128.421 │ 62.855 │ 365.762 │ 110.35 │ 237.614 │ 179.781 │ 50.249 │ 149.781 │ 26.226 │ 527.26 │ 142.641 │ 106.922 │
│ 2022-12-27 │ 129.652 │ 63.27 │ 32.065 │ 79.93 │ 176.329 │ 64.561 │ 314.985 │ 174.844 │ 128.871 │ 63.24 │ 362.76 │ 110.607 │ 235.852 │ 180.58 │ 49.57 │ 151.086 │ 26.375 │ 527.935 │ 142.681 │ 108.408 │
│ 2022-12-28 │ 125.674 │ 62.57 │ 32.301 │ 78.279 │ 173.728 │ 63.883 │ 311.22 │ 174.085 │ 129.575 │ 62.609 │ 363.098 │ 109.581 │ 233.434 │ 179.278 │ 49.25 │ 149.133 │ 24.497 │ 524.422 │ 140.181 │ 106.627 │
└────────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┘2. Regularised portfolios
The optimal regularisation penalty value depends on the data, the investor preferences, and type of regularisation. The specific choice of penalty value is so volatile that it can only be estimated via grid search cross-validation or similar techniques, but the "optimal" (to some definition of optimal) value will also change over time as the market conditions change. Therefore, we will simply show how to set up and solve a regularised portfolio optimisation problem, without attempting to find the optimal penalty value.
We will use the same small penalty for all regularisations to illustrate how they differ.
- L1 regularisation (also known as Lasso regularisation) adds a penalty proportional to the sum of the absolute values of the portfolio weights. This encourages sparsity in the portfolio, leading to fewer assets being selected.
- L2 regularisation (also known as Ridge regularisation) adds a penalty proportional to the sum of the squares of the portfolio weights. This discourages large weights and promotes diversification.
- Lp regularisation via
LpRegularisationadds a penalty proportional to the p-norm of the portfolio weights, wherep > 1is a positive real number. - L-Inf regularisation adds a penalty proportional to the maximum absolute value of the portfolio weights. This limits the influence of any single asset in the portfolio.
2.1 Efficient frontier
opts = [JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, ret = ArithmeticReturn(; settings = JuMPReturnsSettings(; lb = Frontier(; N = 50)))),# JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, ret = ArithmeticReturn(; settings = JuMPReturnsSettings(; lb = Frontier(; N = 50))), bgt = 1, l1 = 4e-4),# JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, ret = ArithmeticReturn(; settings = JuMPReturnsSettings(; lb = Frontier(; N = 50))), bgt = 1, l2 = L2Regularisation(; val = 4e-4)),# JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, ret = ArithmeticReturn(; settings = JuMPReturnsSettings(; lb = Frontier(; N = 50))), bgt = 1, lp = LpRegularisation(; p = 5, val = 4e-4)),# JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, ret = ArithmeticReturn(; settings = JuMPReturnsSettings(; lb = Frontier(; N = 50))), bgt = 1, linf = 4e-4)]nocs = [MeanRisk(; opt = opt) for opt in opts]ress = optimise.(nocs)5-element Vector{MeanRiskResult{JuMPOptimisationResult{ProcessedJuMPOptimiserAttributes{LowOrderPrior{Matrix{Float64}, Nothing, Vector{Float64}, Matrix{Float64}, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing}, WeightBounds{StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}, StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}}, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, Nothing, ArithmeticReturn{JuMPReturnsSettings{Float64, Frontier{Int64, Int64, LinearBound}, Bool, Bool, Bool}, Nothing, Vector{Float64}}, SumScalariser, Nothing}, Vector{OptimisationReturnCode}, Vector{JuMPOptimisationSolution}, Model}, Variance{RiskMeasureSettings{Float64, Nothing, Bool}, Matrix{Float64}, Nothing, Nothing, SquaredSOCRiskExpr}, Nothing}}:
MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ Frontier
│ │ │ │ │ N ┼ Int64: 50
│ │ │ │ │ factor ┼ Int64: 1
│ │ │ │ │ bound ┴ LinearBound()
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┴ 20-element Vector{Float64}
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ 50-element Vector{OptimisationSuccess}
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ sol ┼ 50-element Vector{JuMPOptimisationSolution}
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 62
│ │ ├ num_constraints: 50
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 3
│ │ │ ├ AffExpr in MOI.GreaterThan{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 2
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ ├ VariableRef in MOI.GreaterThan{Float64}: 40
│ │ │ └ VariableRef in MOI.Parameter{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :decomposition_contract, :dev_1, :k, :lbgt, :lw, :obj_expr, :ret, :ret_1, :ret_frontier, :ret_lb_1, :ret_lb_var_1, :ret_vec, :risk, :risk_vec, :sbgt, :sc, :so, :sw, :variance_flag, :variance_risk_1, :w, :w_lb, :w_lw, :w_sw, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┴ SquaredSOCRiskExpr()
fb ┴ nothing
MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ Frontier
│ │ │ │ │ N ┼ Int64: 50
│ │ │ │ │ factor ┼ Int64: 1
│ │ │ │ │ bound ┴ LinearBound()
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┴ 20-element Vector{Float64}
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ 50-element Vector{OptimisationSuccess}
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ sol ┼ 50-element Vector{JuMPOptimisationSolution}
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 63
│ │ ├ num_constraints: 51
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 3
│ │ │ ├ AffExpr in MOI.GreaterThan{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 2
│ │ │ ├ Vector{AffExpr} in MOI.NormOneCone: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ ├ VariableRef in MOI.GreaterThan{Float64}: 40
│ │ │ └ VariableRef in MOI.Parameter{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :cl1_noc, :decomposition_contract, :dev_1, :k, :l1, :lbgt, :lw, :obj_expr, :op, :ret, :ret_1, :ret_frontier, :ret_lb_1, :ret_lb_var_1, :ret_vec, :risk, :risk_vec, :sbgt, :sc, :so, :sw, :t_l1, :variance_flag, :variance_risk_1, :w, :w_lb, :w_lw, :w_sw, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┴ SquaredSOCRiskExpr()
fb ┴ nothing
MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ Frontier
│ │ │ │ │ N ┼ Int64: 50
│ │ │ │ │ factor ┼ Int64: 1
│ │ │ │ │ bound ┴ LinearBound()
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┴ 20-element Vector{Float64}
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ 50-element Vector{OptimisationSuccess}
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ sol ┼ 50-element Vector{JuMPOptimisationSolution}
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 63
│ │ ├ num_constraints: 51
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 3
│ │ │ ├ AffExpr in MOI.GreaterThan{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 2
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 2
│ │ │ ├ VariableRef in MOI.GreaterThan{Float64}: 40
│ │ │ └ VariableRef in MOI.Parameter{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :cl2_soc_1, :decomposition_contract, :dev_1, :k, :l2_1, :lbgt, :lw, :obj_expr, :op, :ret, :ret_1, :ret_frontier, :ret_lb_1, :ret_lb_var_1, :ret_vec, :risk, :risk_vec, :sbgt, :sc, :so, :sw, :t_l2_1, :variance_flag, :variance_risk_1, :w, :w_lb, :w_lw, :w_sw, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┴ SquaredSOCRiskExpr()
fb ┴ nothing
MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ Frontier
│ │ │ │ │ N ┼ Int64: 50
│ │ │ │ │ factor ┼ Int64: 1
│ │ │ │ │ bound ┴ LinearBound()
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┴ 20-element Vector{Float64}
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ 50-element Vector{OptimisationSuccess}
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ sol ┼ 50-element Vector{JuMPOptimisationSolution}
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 83
│ │ ├ num_constraints: 71
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 4
│ │ │ ├ AffExpr in MOI.GreaterThan{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 2
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ ├ Vector{AffExpr} in MOI.PowerCone{Float64}: 20
│ │ │ ├ VariableRef in MOI.GreaterThan{Float64}: 40
│ │ │ └ VariableRef in MOI.Parameter{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :clp_1, :cslp_1, :decomposition_contract, :dev_1, :k, :lbgt, :lp_1, :lw, :obj_expr, :op, :r_lp_1, :ret, :ret_1, :ret_frontier, :ret_lb_1, :ret_lb_var_1, :ret_vec, :risk, :risk_vec, :sbgt, :sc, :so, :sw, :t_lp_1, :variance_flag, :variance_risk_1, :w, :w_lb, :w_lw, :w_sw, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┴ SquaredSOCRiskExpr()
fb ┴ nothing
MeanRiskResult
jr ┼ JuMPOptimisationResult
│ pa ┼ ProcessedJuMPOptimiserAttributes
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┴ nothing
│ │ wb ┼ WeightBounds
│ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ lt ┼ nothing
│ │ st ┼ nothing
│ │ lcsr ┼ nothing
│ │ ctr ┼ nothing
│ │ gcardr ┼ nothing
│ │ sgcardr ┼ nothing
│ │ smtx ┼ nothing
│ │ sgmtx ┼ nothing
│ │ slt ┼ nothing
│ │ sst ┼ nothing
│ │ sglt ┼ nothing
│ │ sgst ┼ nothing
│ │ tn ┼ nothing
│ │ fees ┼ nothing
│ │ plr ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ Frontier
│ │ │ │ │ N ┼ Int64: 50
│ │ │ │ │ factor ┼ Int64: 1
│ │ │ │ │ bound ┴ LinearBound()
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┴ 20-element Vector{Float64}
│ │ sca ┼ SumScalariser()
│ │ imsk ┴ nothing
│ retcode ┼ 50-element Vector{OptimisationSuccess}
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ │ OptimisationSuccess ⋯
│ sol ┼ 50-element Vector{JuMPOptimisationSolution}
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ │ JuMPOptimisationSolution ⋯
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: QuadExpr
│ │ ├ num_variables: 63
│ │ ├ num_constraints: 51
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 3
│ │ │ ├ AffExpr in MOI.GreaterThan{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 2
│ │ │ ├ Vector{AffExpr} in MOI.NormInfinityCone: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ ├ VariableRef in MOI.GreaterThan{Float64}: 40
│ │ │ └ VariableRef in MOI.Parameter{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :cdev_soc_1, :clinf_nic, :decomposition_contract, :dev_1, :k, :lbgt, :linf, :lw, :obj_expr, :op, :ret, :ret_1, :ret_frontier, :ret_lb_1, :ret_lb_var_1, :ret_vec, :risk, :risk_vec, :sbgt, :sc, :so, :sw, :t_linf, :variance_flag, :variance_risk_1, :w, :w_lb, :w_lw, :w_sw, :w_ub
r ┼ Variance
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ rc ┼ nothing
│ alg ┴ SquaredSOCRiskExpr()
fb ┴ nothing
Let's plot the efficient frontiers.
using StatsPlots, GraphRecipesr = Variance()Variance
settings ┼ RiskMeasureSettings
│ scale ┼ Float64: 1.0
│ ub ┼ nothing
│ rke ┴ Bool: true
sigma ┼ nothing
chol ┼ nothing
rc ┼ nothing
alg ┴ SquaredSOCRiskExpr()
No regularisation portfolio weights.
plot_stacked_area_composition(ress[1].w, rd.nx; kwargs = (; xlabel = "Portfolios", ylabel = "Weight", title = "No regularisation", legend = :outerright))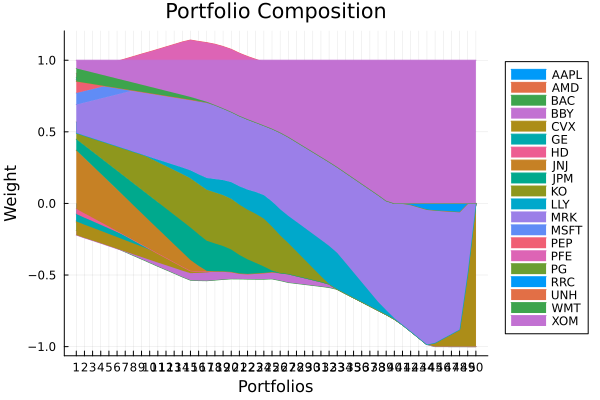
No regularisation frontier.
plot_measures(ress[1].w, pr; x = r, y = ExpectedReturn(; rt = ress[1].ret), c = ExpectedReturnRiskRatio(; rt = ress[1].ret, rk = r, rf = 4.2 / 100 / 252), title = "No regularisation", xlabel = "Variance", ylabel = "Arithmetic Return", colorbar_title = "\nRisk/Return Ratio", right_margin = 6Plots.mm)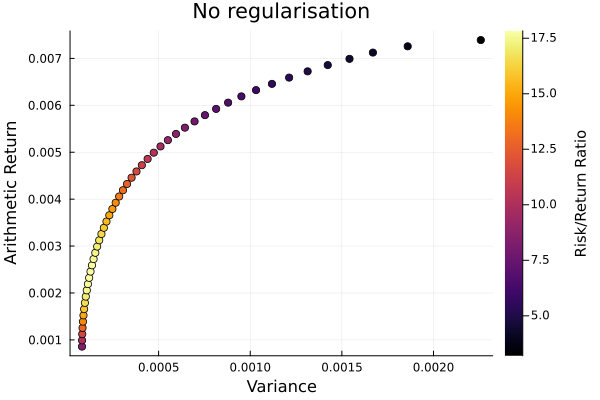
L1 regularisation portfolio weights. As expected, the portfolio is sparsified, with fewer assets with non-zero weight.
plot_stacked_area_composition(ress[2].w, rd.nx; kwargs = (; xlabel = "Portfolios", ylabel = "Weight", title = "L1 regularisation", legend = :outerright))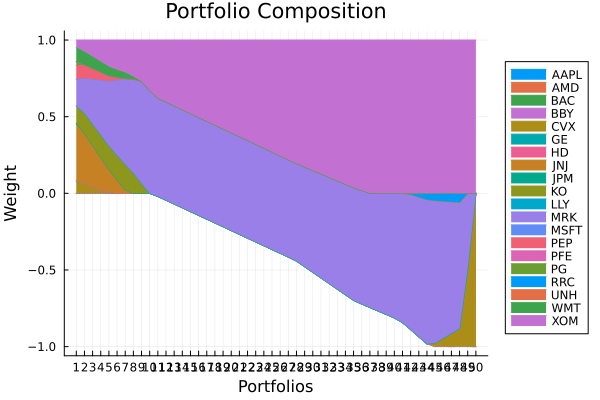
L1 regularisation frontier. The sparsification makes the pareto front non-smooth.
plot_measures(ress[2].w, pr; x = r, y = ExpectedReturn(; rt = ress[2].ret), c = ExpectedReturnRiskRatio(; rt = ress[1].ret, rk = r, rf = 4.2 / 100 / 252), title = "L1 regularisation", xlabel = "Variance", ylabel = "Arithmetic Return", colorbar_title = "\nRisk/Return Ratio", right_margin = 6Plots.mm)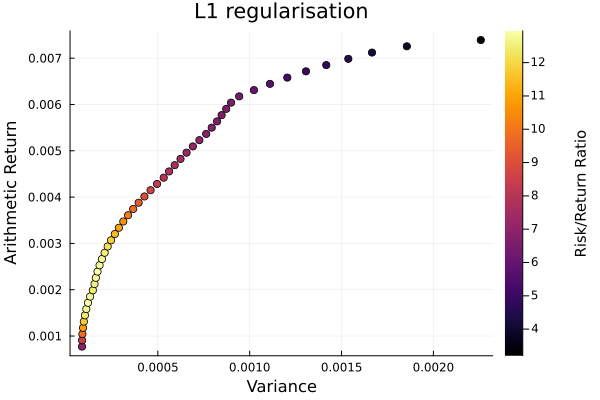
L2 regularisation portfolio weights. Even values of p-norms smooth out the weights, leading to more diversified portfolios. The higher the value, the more highly penalised larger deviations from the mean weight become. This is similar to how moments of even order behave.
plot_stacked_area_composition(ress[3].w, rd.nx; kwargs = (; xlabel = "Portfolios", ylabel = "Weight", title = "L2 regularisation", legend = :outerright))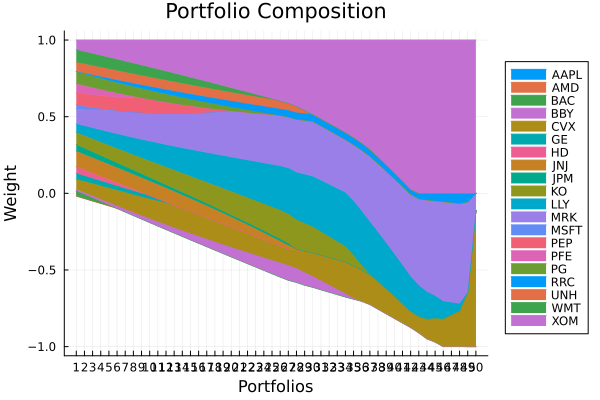
L2 regularisation frontier.
plot_measures(ress[3].w, pr; x = r, y = ExpectedReturn(; rt = ress[3].ret), c = ExpectedReturnRiskRatio(; rt = ress[1].ret, rk = r, rf = 4.2 / 100 / 252), title = "L2 regularisation", xlabel = "Variance", ylabel = "Arithmetic Return", colorbar_title = "\nRisk/Return Ratio", right_margin = 6Plots.mm)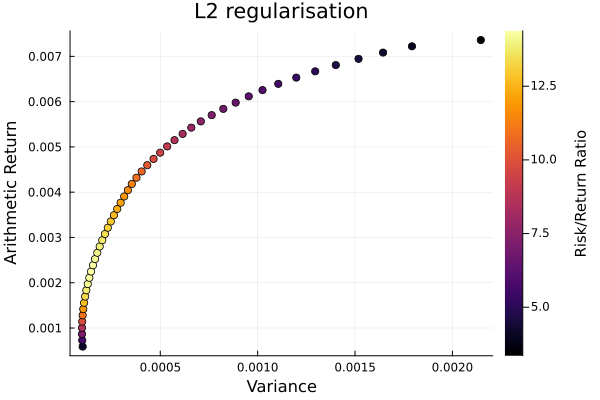
Lp regularisation portfolio weights. The higher the value of p, the closer the behaviour is to L-Inf regularisation, where the maximum absolute weight is penalised. This leads to portfolios where all weights are more similar in magnitude, but does not smear the negative weights into positive values like the L2 norm.
plot_stacked_area_composition(ress[4].w, rd.nx; kwargs = (; xlabel = "Portfolios", ylabel = "Weight", title = "Lp (p = 5) regularisation", legend = :outerright))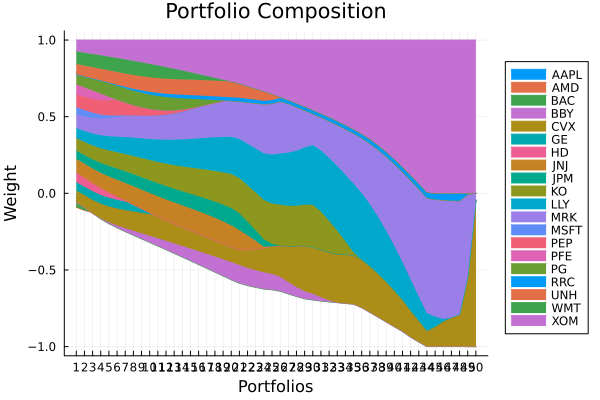
Lp regularisation frontier.
plot_measures(ress[4].w, pr; x = r, y = ExpectedReturn(; rt = ress[4].ret), c = ExpectedReturnRiskRatio(; rt = ress[1].ret, rk = r, rf = 4.2 / 100 / 252), title = "Lp (p = 5) regularisation", xlabel = "Variance", ylabel = "Arithmetic Return", colorbar_title = "\nRisk/Return Ratio", right_margin = 6Plots.mm)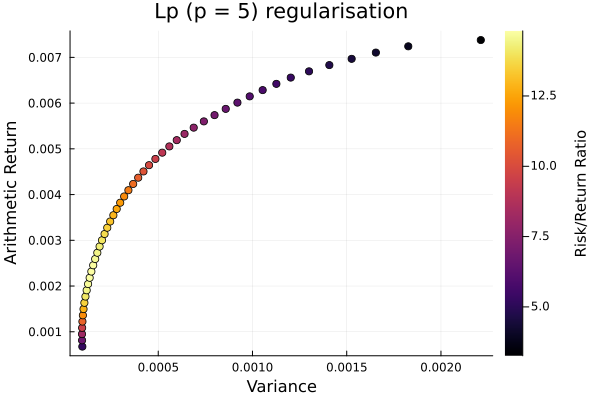
L-Inf regularisation portfolio weights.
plot_stacked_area_composition(ress[5].w, rd.nx; kwargs = (; xlabel = "Portfolios", ylabel = "Weight", title = "L-Inf regularisation", legend = :outerright))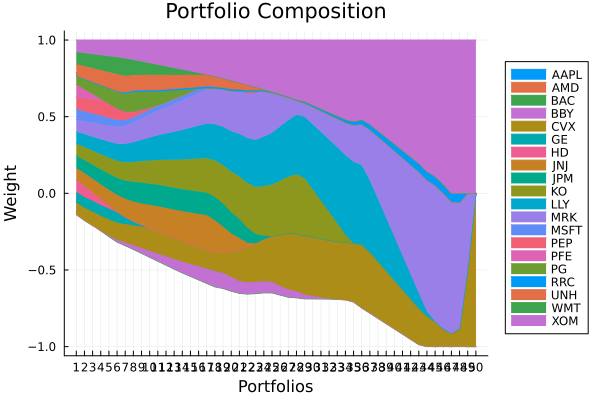
L-Inf regularisation frontier.
plot_measures(ress[5].w, pr; x = r, y = ExpectedReturn(; rt = ress[5].ret), c = ExpectedReturnRiskRatio(; rt = ress[1].ret, rk = r, rf = 4.2 / 100 / 252), title = "L-Inf regularisation", xlabel = "Variance", ylabel = "Arithmetic Return", colorbar_title = "\nRisk/Return Ratio", right_margin = 6Plots.mm)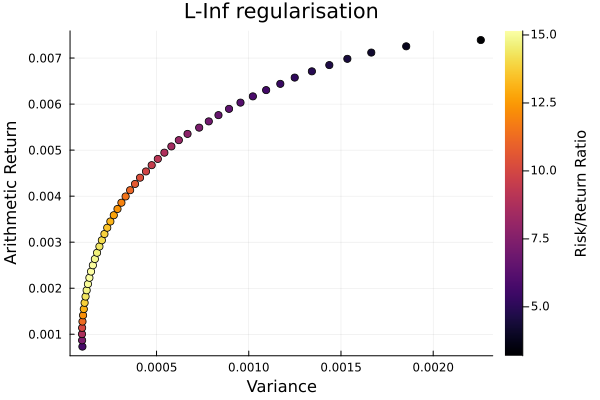
2.2 Minimum risk portfolios
Lets view only the minimum risk portfolios for each regularisation to get more insight into what regularisation does.
opts = [JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1),# no regularisation JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, l1 = 4e-4),# L1 regularisation JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, l2 = L2Regularisation(; val = 4e-4)),# L2 regularisation JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, lp = LpRegularisation(; p = 5, val = 4e-4)),# Lp regularisation with p = 5 JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, linf = 4e-4)]# L-Inf regularisationnocs = [MeanRisk(; opt = opt) for opt in opts]ress = optimise.(nocs)pretty_table(DataFrame(:Assets => rd.nx, :No_Reg => ress[1].w, :L1 => ress[2].w, :L2 => ress[3].w, :L5 => ress[4].w, :LInf => ress[5].w); formatters = [resfmt], summary_rows = [summary_row], summary_row_labels = ["# Eff. Assets"])┌───────────────┬────────┬───────────┬──────────┬──────────┬──────────┬──────────┐
│ │ Assets │ No_Reg │ L1 │ L2 │ L5 │ LInf │
│ │ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├───────────────┼────────┼───────────┼──────────┼──────────┼──────────┼──────────┤
│ │ AAPL │ -11.866 % │ 0.0 % │ 1.136 % │ -3.026 % │ -5.751 % │
│ │ AMD │ -1.55 % │ 0.0 % │ -2.963 % │ -6.029 % │ -7.437 % │
│ │ BAC │ -5.46 % │ 0.0 % │ 3.488 % │ 4.28 % │ 1.181 % │
│ │ BBY │ -3.234 % │ 0.0 % │ 1.035 % │ -1.015 % │ -1.935 % │
│ │ CVX │ 9.487 % │ 7.415 % │ 6.57 % │ 7.553 % │ 7.879 % │
│ │ GE │ 5.203 % │ 0.823 % │ 3.871 % │ 5.501 % │ 6.838 % │
│ │ HD │ 3.621 % │ 0.0 % │ 4.194 % │ 6.143 % │ 7.879 % │
│ │ JNJ │ 40.958 % │ 36.981 % │ 10.221 % │ 9.019 % │ 7.879 % │
│ │ JPM │ 7.738 % │ 0.762 % │ 4.252 % │ 5.446 % │ 7.879 % │
│ │ KO │ 12.0 % │ 11.098 % │ 7.952 % │ 8.217 % │ 7.879 % │
│ │ LLY │ -7.707 % │ 0.0 % │ 5.655 % │ 6.507 % │ 7.878 % │
│ │ MRK │ 19.792 % │ 17.462 % │ 9.638 % │ 8.719 % │ 7.879 % │
│ │ MSFT │ 8.105 % │ 0.0 % │ 2.536 % │ 4.917 % │ 7.071 % │
│ │ PEP │ 13.7 % │ 8.969 % │ 7.992 % │ 8.234 % │ 7.879 % │
│ │ PFE │ -4.513 % │ 0.0 % │ 5.999 % │ 6.673 % │ 7.879 % │
│ │ PG │ 1.787 % │ 2.399 % │ 7.873 % │ 8.145 % │ 7.879 % │
│ │ RRC │ -1.68 % │ 0.0 % │ 0.153 % │ -1.8 % │ -2.388 % │
│ │ UNH │ -1.188 % │ 0.0 % │ 5.939 % │ 6.862 % │ 7.879 % │
│ │ WMT │ 9.161 % │ 9.356 % │ 8.205 % │ 8.32 % │ 7.879 % │
│ │ XOM │ 5.649 % │ 4.734 % │ 6.254 % │ 7.334 % │ 7.879 % │
├───────────────┼────────┼───────────┼──────────┼──────────┼──────────┼──────────┤
│ # Eff. Assets │ N/A │ 3.28601 │ 4.88263 │ 13.8946 │ 11.588 │ 9.971 │
└───────────────┴────────┴───────────┴──────────┴──────────┴──────────┴──────────┘The effect of each regularisation depends on the relative values of the objective function with respect to the value of the relevant norm of the optimised portfolio weights multiplied by the penalty.
Generally, regularised portfolios tend to have more effective assets than unregularised ones. The number of effective assets is different to the sparsity in that it measures the concentration of weights as 1/(w ⋅ w), rather than counting the number of non-zero (or near zero) weights. Usually, the larger the number of effective assets, the more diversified the portfolio. Sparsity is a non-smooth measure, while the number of effective assets is smooth, so a portfolio can have higher sparsity and still have a larger number of effective assets.
It is possible to combine multiple regularisation penalties in the same optimisation problem by simultaneously specifying multiple regularisation keywords in the JuMPOptimiser. This can be useful to combine the benefits of different regularisations, such as sparsity and diversification, but can make the optimisation more difficult to solve and interpret.
3. A rule in place of a penalty value
Every coefficient section 2 states as a number is a calibration slot. A slot takes the number itself, and it takes a Calibration Rule, which computes the number from the prior result of the sample in front of it. The rule resolves where the model is built, so a cross-validation over folds of unequal length refits the coefficient on every fold and nothing else about the optimiser moves. The calibration example shows the slot on a risk measure. This section reads all seven slots this example owns.
The four penalty coefficients are ambiguity radii. A norm penalty is the support function of a ball in the dual of the penalised norm, so its coefficient is the radius of that ball and its slot takes a rule of the ambiguity-radius family.
The three norm ceilings l2c, lpc and linfc bound a norm rather than price one, so they are a different quantity and their slots take a family of their own, the norm-ceiling rules. A ceiling is a diversification statement: its reciprocal is a floor on the effective number of assets.
3.1 One rule reads the slot it stands in
DualNormRadius returns the sampling error of the mean vector, measured in the ground metric of the slot. The ground metric is the dual of the norm the slot penalises, so the rule reads the slot's own key and answers a different number for every key. Every other radius rule returns one number for every slot.
numfmt = (v, i, j) -> begin return isa(v, AbstractFloat) ? round(v; sigdigits = 4) : vend;dnr = DualNormRadius(; confidence = 0.95)lp5 = CalibrationContext(; p = 5)radius_table = DataFrame(:slot => ["l1", "linf", "l2, val", "lp, val, p = 5"], :penalised_norm => ["1", "Inf", "2", "5"], :ground_metric => ["Inf", "1", "2", "1.25"], :radius => [dnr(:l1, pr, nothing, nothing, CalibrationContext()), dnr(:linf, pr, nothing, nothing, CalibrationContext()), dnr(:l2reg_val, pr, nothing, nothing, CalibrationContext()), dnr(:lpreg_val, pr, nothing, nothing, lp5)])pretty_table(radius_table; formatters = [numfmt])┌────────────────┬────────────────┬───────────────┬──────────┐
│ slot │ penalised_norm │ ground_metric │ radius │
│ String │ String │ String │ Float64 │
├────────────────┼────────────────┼───────────────┼──────────┤
│ l1 │ 1 │ Inf │ 0.0041 │
│ linf │ Inf │ 1 │ 0.04173 │
│ l2, val │ 2 │ 2 │ 0.009974 │
│ lp, val, p = 5 │ 5 │ 1.25 │ 0.0233 │
└────────────────┴────────────────┴───────────────┴──────────┘The l1 and linf rows are the reading to take away. One rule, one sample and one confidence level give two coefficients an order of magnitude apart, because an L1 penalty is priced in the ∞-norm of the error and an L-Inf penalty in its 1-norm. The lp row needs the penalty's own p, because no key can name the conjugate order. The rule holds no order of its own: the penalty site states it in a CalibrationContext, and the lp5 context above stands in for that site because the rule runs outside it here.
The slot takes the rule, and the coefficient appears when the model is built. The two runs below differ only in what stands in l1, and they hold the same weights.
l1_rule = JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, l1 = DualNormRadius())l1_num = JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, l1 = dnr(:l1, pr, nothing, nothing, CalibrationContext()))res_rule = optimise(MeanRisk(; opt = l1_rule))res_num = optimise(MeanRisk(; opt = l1_num))println("largest weight difference = $(maximum(abs, res_rule.w - res_num.w))")largest weight difference = 0.03.2 Two rates, and the one the universe sets
RateRadius shrinks the ball as c / sqrt(T), which is the rate a sample mean's own error falls at. DimensionalRateRadius shrinks it at the rate the number of assets sets, which is far slower over a wide universe: the exponent is 1 / max(N, 2) rather than 1 / 2. The table reads both rules over three windows of the same record.
X_all = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)rate_table = DataFrame()for T in (252, 630, 1260) pr_T = prior(EmpiricalPrior(), prices_to_returns(X_all[(end - T):end])) push!(rate_table, (; T = size(pr_T.X, 1), N = size(pr_T.X, 2), rate = RateRadius(; c = 0.02)(:l1, pr_T, nothing, nothing, CalibrationContext()), dimensional = DimensionalRateRadius(; confidence = 0.95)(:l1, pr_T, nothing, nothing, CalibrationContext())))endpretty_table(rate_table; formatters = [numfmt])┌───────┬───────┬───────────┬─────────────┐
│ T │ N │ rate │ dimensional │
│ Int64 │ Int64 │ Float64 │ Float64 │
├───────┼───────┼───────────┼─────────────┤
│ 252 │ 20 │ 0.00126 │ 0.01613 │
│ 630 │ 20 │ 0.0007968 │ 0.01441 │
│ 1260 │ 20 │ 0.0005634 │ 0.01537 │
└───────┴───────┴───────────┴─────────────┘The rate radius falls by the square root of the ratio of the lengths. The dimensional radius barely moves, and it does not fall monotonically either: over this universe the exponent is 1 / 20, so a fivefold record buys almost nothing, and what movement the column holds comes from the scale the rule reads off each window rather than from the length of it.
3.3 The three norm ceilings
EffectiveAssetFloor is the one rule of the ceiling family. It states a fraction of the universe to hold effective, and returns the ceiling on the norm that meets it. The order-p effective number of assets is (sum(abs.(w) .^ p))^(1 / (1 - p)), and the ceiling is the number that holds it at or above fraction * N.
The order belongs to the constraint rather than to the rule, so each site states it in a CalibrationContext. A rule run outside a site needs a context that names p, exactly as the lp radius above did.
N = size(pr.X, 2)println("universe = $N assets, floor = $(0.5 * N) effective assets")eaf = EffectiveAssetFloor(; fraction = 0.5)ceiling_table = DataFrame(:slot => ["l2c", "lpc, p = 5", "linfc"], :norm_order => ["2", "5", "Inf"], :ceiling => [eaf(:l2c, pr, nothing, nothing, CalibrationContext(; p = 2)), eaf(:lpc, pr, nothing, nothing, CalibrationContext(; p = 5)), eaf(:linfc, pr, nothing, nothing, CalibrationContext(; p = Inf))])pretty_table(ceiling_table; formatters = [numfmt])universe = 20 assets, floor = 10.0 effective assets
┌────────────┬────────────┬─────────┐
│ slot │ norm_order │ ceiling │
│ String │ String │ Float64 │
├────────────┼────────────┼─────────┤
│ l2c │ 2 │ 0.3162 │
│ lpc, p = 5 │ 5 │ 0.1585 │
│ linfc │ Inf │ 0.1 │
└────────────┴────────────┴─────────┘One rule serves the three slots, and each site reads it against its own norm order.
ceil_rule = EffectiveAssetFloor(; fraction = 0.5)copts = [JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1),# no ceiling JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, l2c = ceil_rule),# 2-norm ceiling JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, lpc = LpRegularisation(; p = 5, val = ceil_rule)),# 5-norm ceiling JuMPOptimiser(; pe = pr, slv = slv, wb = WeightBounds(; lb = -1, ub = 1), sbgt = 1, bgt = 1, linfc = ceil_rule)]# Inf-norm ceilingcress = [optimise(MeanRisk(; opt = opt)) for opt in copts]n_eff_p(w, p) = isinf(p) ? inv(maximum(abs, w)) : sum(abs.(w) .^ p)^inv(1 - p)ceiling_orders = [2, 2, 5, Inf]effective_table = DataFrame(:ceiling => ["none", "l2c", "lpc, p = 5", "linfc"], :p => ceiling_orders, :n_eff_2 => [number_effective_assets(r.w) for r in cress], :n_eff_p => [n_eff_p(r.w, p) for (r, p) in zip(cress, ceiling_orders)])pretty_table(effective_table; formatters = [numfmt])┌────────────┬─────────┬─────────┬─────────┐
│ ceiling │ p │ n_eff_2 │ n_eff_p │
│ String │ Float64 │ Float64 │ Float64 │
├────────────┼─────────┼─────────┼─────────┤
│ none │ 2.0 │ 3.286 │ 3.286 │
│ l2c │ 2.0 │ 10.0 │ 10.0 │
│ lpc, p = 5 │ 5.0 │ 9.157 │ 10.0 │
│ linfc │ Inf │ 8.571 │ 10.0 │
└────────────┴─────────┴─────────┴─────────┘Every ceiling meets its own order's floor, which is the n_eff_p column. The n_eff_2 column is number_effective_assets, which is the order-2 reading alone, so only the l2c row is read against the order its ceiling was written for. The two columns are one number on that row and two numbers on the others, and that is a statement about which order the reading uses rather than about a ceiling that missed.
The rule refuses a resolution whose context names no order, and the message names the three slots that state one.
try eaf(:l2c, pr, nothing, nothing, CalibrationContext())catch e println(sprint(showerror, e))endArgumentError: `CalibrationContext.p` is `nothing` while the rule in `l2c` is being resolved. A ceiling is read against one norm order, the order belongs to the constraint, and each constraint site states it in the context. Place the rule in `l2c`, `lpc` or `linfc`, or state `p` in the context.This page was generated using Literate.jl.