The source files can be found in examples/.
Feature matrices as a distance source
Every clustering optimiser met so far builds its hierarchy from the returns: a covariance estimate becomes a correlation, a correlation becomes a distance, and the distance becomes a dendrogram. That route can only ever see structure the price history contains.
A FeatureDistance replaces the returns with an assets × features matrix. Feature k is any per-asset quantity you can name — a sector membership, a factor loading, a position in the asset network, a trailing characteristic — and two assets are close when their feature rows point the same way. The output is an ordinary distance matrix, so every consumer that takes a distance estimator takes this one: ClustersEstimator, NetworkEstimator, the clustering optimisers, and the phylogeny and centrality constraint families.
The matrix itself is never stored. An AssetPanel holds the values, one Panel Field per named quantity, and feature_matrix stacks the fields a selector names into the matrix a distance measures. Building it where it is measured is what lets one panel serve a taxonomy, a fundamentals table and a factor model at once.
The point of the exercise is exogenous structure. A classification, a mandate, a supply chain or a factor model brings in relationships the returns do not contain; feeding the returns graph back in as features is a different and more subtle tool, covered in §4.
Reach for a FeatureDistance when you can name the structure you want the allocation to respect and it is not in the price history — a sector or country taxonomy, a regulatory bucketing, an ESG classification, a factor exposure profile. Reach for it too when you want the hierarchy to stop churning between rebalances: an exogenous classification does not move when the covariance does, which is worth a large turnover reduction (§9). Stay with the ordinary correlation distance when the structure you care about is co-movement.
using PortfolioOptimisers, CSV, TimeSeries, DataFrames, PrettyTables, Clarabel, StatsPlots, GraphRecipes, Statistics, LinearAlgebra, Clusteringresfmt = (v, i, j) -> begin return if j == 1 v else isa(v, AbstractFloat) ? "$(round(v*100, digits=3)) %" : v endend;1. ReturnsResult data and a classification
The same twenty-name S&P 500 slice as the other optimiser examples, plus an illustrative two-level classification. The two levels are nested: every industry belongs to exactly one sector, so agreeing on an industry implies agreeing on a sector.
X = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd0 = prices_to_returns(X)pr = prior(EmpiricalPrior(), rd0)slv = Solver(; name = :clarabel, solver = Clarabel.Optimizer, settings = Dict("verbose" => false), check_sol = (; allow_local = true, allow_almost = true))sector = Dict("AAPL" => "Technology", "AMD" => "Technology", "MSFT" => "Technology", "BAC" => "Financials", "JPM" => "Financials", "CVX" => "Energy", "XOM" => "Energy", "RRC" => "Energy", "GE" => "Industrials", "BBY" => "ConsumerDiscretionary", "HD" => "ConsumerDiscretionary", "KO" => "ConsumerStaples", "PEP" => "ConsumerStaples", "PG" => "ConsumerStaples", "WMT" => "ConsumerStaples", "JNJ" => "HealthCare", "LLY" => "HealthCare", "MRK" => "HealthCare", "PFE" => "HealthCare", "UNH" => "HealthCare")industry = Dict("AAPL" => "ConsumerHardware", "AMD" => "Semiconductors", "MSFT" => "Software", "BAC" => "Banks", "JPM" => "Banks", "CVX" => "IntegratedOil", "XOM" => "IntegratedOil", "RRC" => "ExplorationProduction", "GE" => "Conglomerates", "BBY" => "SpecialtyRetail", "HD" => "SpecialtyRetail", "KO" => "Beverages", "PEP" => "Beverages", "PG" => "HouseholdProducts", "WMT" => "MassMerchants", "JNJ" => "Pharmaceuticals", "LLY" => "Pharmaceuticals", "MRK" => "Pharmaceuticals", "PFE" => "Pharmaceuticals", "UNH" => "ManagedCare")Dict{String, String} with 20 entries:
"AAPL" => "ConsumerHardware"
"MSFT" => "Software"
"RRC" => "ExplorationProduction"
"LLY" => "Pharmaceuticals"
"UNH" => "ManagedCare"
"CVX" => "IntegratedOil"
"KO" => "Beverages"
"PEP" => "Beverages"
"HD" => "SpecialtyRetail"
"AMD" => "Semiconductors"
"XOM" => "IntegratedOil"
"JPM" => "Banks"
"PFE" => "Pharmaceuticals"
"BAC" => "Banks"
"GE" => "Conglomerates"
"PG" => "HouseholdProducts"
"MRK" => "Pharmaceuticals"
"JNJ" => "Pharmaceuticals"
"WMT" => "MassMerchants"
"BBY" => "SpecialtyRetail"The classification travels on a UniverseSets. Every key an asset view has to follow must carry the xkey prefix — "nx_sector", not "sector" — because that prefix is what port_opt_view slices alongside the asset names.
sets = UniverseSets(; xkey = "nx", dict = Dict("nx" => rd0.nx, "nx_sector" => [sector[a] for a in rd0.nx], "nx_industry" => [industry[a] for a in rd0.nx]))taxonomy = ["nx_sector", "nx_industry"]pretty_table(DataFrame("Asset" => rd0.nx, "Sector" => [sector[a] for a in rd0.nx], "Industry" => [industry[a] for a in rd0.nx]); title = "The classification the Asset Panel will carry") The classification the Asset Panel will carry
┌────────┬───────────────────────┬───────────────────────┐
│ Asset │ Sector │ Industry │
│ String │ String │ String │
├────────┼───────────────────────┼───────────────────────┤
│ AAPL │ Technology │ ConsumerHardware │
│ AMD │ Technology │ Semiconductors │
│ BAC │ Financials │ Banks │
│ BBY │ ConsumerDiscretionary │ SpecialtyRetail │
│ CVX │ Energy │ IntegratedOil │
│ GE │ Industrials │ Conglomerates │
│ HD │ ConsumerDiscretionary │ SpecialtyRetail │
│ JNJ │ HealthCare │ Pharmaceuticals │
│ JPM │ Financials │ Banks │
│ KO │ ConsumerStaples │ Beverages │
│ LLY │ HealthCare │ Pharmaceuticals │
│ MRK │ HealthCare │ Pharmaceuticals │
│ MSFT │ Technology │ Software │
│ PEP │ ConsumerStaples │ Beverages │
│ PFE │ HealthCare │ Pharmaceuticals │
│ PG │ ConsumerStaples │ HouseholdProducts │
│ RRC │ Energy │ ExplorationProduction │
│ UNH │ HealthCare │ ManagedCare │
│ WMT │ ConsumerStaples │ MassMerchants │
│ XOM │ Energy │ IntegratedOil │
└────────┴───────────────────────┴───────────────────────┘2. From a classification to an Asset Panel
panel_input bridges one UniverseSets key to one raw Panel Field, and dispatches on what the key holds: a vector of strings becomes a CategoricalPanelInput, a vector of numbers a NumericPanelInput. The vector form maps over several keys, which is what a nested taxonomy is. The field is named by stripping the xkey prefix, so "nx_sector" becomes the Panel Field "sector".
asset_panel turns the raw inputs into the AssetPanel a carrier holds. A categorical field stores integer codes over its levels rather than an indicator block, so the panel carries the classification once however many levels it has.
inputs = panel_input(sets, taxonomy)pnl = asset_panel(inputs)pretty_table(DataFrame("Panel Field" => [f.name for f in pnl.pf], "Kind" => [string(nameof(typeof(f))) for f in pnl.pf], "Levels" => [length(PortfolioOptimisers.panel_field_labels(f)) for f in pnl.pf]); title = "One Panel Field per level of the classification")One Panel Field per level of the classification
┌─────────────┬───────────────────────┬────────┐
│ Panel Field │ Kind │ Levels │
│ String │ String │ Int64 │
├─────────────┼───────────────────────┼────────┤
│ sector │ CategoricalPanelField │ 7 │
│ industry │ CategoricalPanelField │ 13 │
└─────────────┴───────────────────────┴────────┘feature_matrix stacks the panel into the matrix a distance measures, and feature_labels names its columns. A categorical field gives one 0/1 column per level, so Z[i, k] == 1 when asset i belongs to group k.
Take the column names from feature_labels rather than rebuilding the order by hand: a label is the Feature Selector entry that picks out exactly its own column, so the label vector is itself a selector, and stacking the panel against it rebuilds the same matrix. That round trip is what makes the labels safe to rely on.
Z = feature_matrix(pnl)nz = feature_labels(pnl)pretty_table(DataFrame(["Asset" => rd0.nx; [string(first(nz[k]), "=", last(nz[k])) => Z[:, k] for k in 1:6]...]); title = "The first six feature columns (of $(length(nz)))")println("The labels rebuild the matrix: ", feature_matrix(pnl, nz) == Z) The first six feature columns (of 20)
┌────────┬──────────────────────────────┬────────────────────────┬───────────────┬───────────────────┬───────────────────┬────────────────────┐
│ Asset │ sector=ConsumerDiscretionary │ sector=ConsumerStaples │ sector=Energy │ sector=Financials │ sector=HealthCare │ sector=Industrials │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼──────────────────────────────┼────────────────────────┼───────────────┼───────────────────┼───────────────────┼────────────────────┤
│ AAPL │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ AMD │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ BAC │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │
│ BBY │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ CVX │ 0.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │
│ GE │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │
│ HD │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ JNJ │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ JPM │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │
│ KO │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ LLY │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ MRK │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ MSFT │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ PEP │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ PFE │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ PG │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ RRC │ 0.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │
│ UNH │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ WMT │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ XOM │ 0.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │
└────────┴──────────────────────────────┴────────────────────────┴───────────────┴───────────────────┴───────────────────┴────────────────────┘
The labels rebuild the matrix: true2.1 Why this panel needs no standardisation
A categorical Panel Field is a partition: each asset lands in exactly one level, so every row of its indicator block carries exactly one 1, and a panel of L categorical fields gives every asset a row of norm sqrt(L). The cosine between two assets is then exactly
cos(i, j) = shared(i, j) / Lthe count of classification levels they agree on, divided by the number of levels. That makes AngularDist — the default metric — take only L + 1 distinct values, and bounds the distance by 0.5 rather than 1.0 because the cosine can never go negative.
This is a property of the categorical kind, not of panels in general. A numeric or tensor field carries values on its own scale and has no such guarantee.
D = distance(FeatureDistance(), Z; dims = 1)levels = sort(unique(round.(D; digits = 6)))pretty_table(DataFrame("Quantity" => ["Feature columns", "Levels agreed on (L)", "Row norm (every row, = sqrt(L))", "Distinct distances", "The distances themselves"], "Value" => [string(size(Z, 2)), string(length(taxonomy)), string(round(norm(Z[1, :]); digits = 4)), string(length(levels)), string(round.(levels; digits = 4))]); title = "The feature distance this classification produces") The feature distance this classification produces
┌─────────────────────────────────┬────────────────────┐
│ Quantity │ Value │
│ String │ String │
├─────────────────────────────────┼────────────────────┤
│ Feature columns │ 20 │
│ Levels agreed on (L) │ 2 │
│ Row norm (every row, = sqrt(L)) │ 1.4142 │
│ Distinct distances │ 3 │
│ The distances themselves │ [0.0, 0.3333, 0.5] │
└─────────────────────────────────┴────────────────────┘Three distances, one per agreement level, up to floating-point noise in acos: 0.0 for two assets in the same industry, 1/3 for two in the same sector but different industries, and 0.5 for two sharing nothing.
2.2 The clustering it produces
The panel rides on the ReturnsResult, because it is data, not configuration. The distance estimator goes into an ordinary ClustersEstimator through its de slot, and clusterise reads the panel off the carrier it is handed.
rd = ReturnsResult(; nx = rd0.nx, X = rd0.X, ts = rd0.ts, pnl = pnl)onc = OptimalNumberClusters(;)cle_cor = ClustersEstimator(; onc = onc)cle_fea = ClustersEstimator(; de = FeatureDistance(), onc = onc)clr_cor = clusterise(cle_cor, rd)clr_fea = clusterise(cle_fea, rd)pretty_table(DataFrame("Asset" => rd.nx, "Sector" => [sector[a] for a in rd.nx], "Correlation cut" => assignments(clr_cor), "Feature cut" => assignments(clr_fea)); title = "Cluster assignments according to correlation and feature distance")Cluster assignments according to correlation and feature distance
┌────────┬───────────────────────┬─────────────────┬─────────────┐
│ Asset │ Sector │ Correlation cut │ Feature cut │
│ String │ String │ Int64 │ Int64 │
├────────┼───────────────────────┼─────────────────┼─────────────┤
│ AAPL │ Technology │ 1 │ 1 │
│ AMD │ Technology │ 1 │ 1 │
│ BAC │ Financials │ 1 │ 1 │
│ BBY │ ConsumerDiscretionary │ 1 │ 1 │
│ CVX │ Energy │ 1 │ 2 │
│ GE │ Industrials │ 1 │ 1 │
│ HD │ ConsumerDiscretionary │ 1 │ 1 │
│ JNJ │ HealthCare │ 2 │ 3 │
│ JPM │ Financials │ 1 │ 1 │
│ KO │ ConsumerStaples │ 2 │ 4 │
│ LLY │ HealthCare │ 2 │ 3 │
│ MRK │ HealthCare │ 2 │ 3 │
│ MSFT │ Technology │ 1 │ 1 │
│ PEP │ ConsumerStaples │ 2 │ 4 │
│ PFE │ HealthCare │ 2 │ 3 │
│ PG │ ConsumerStaples │ 2 │ 4 │
│ RRC │ Energy │ 1 │ 2 │
│ UNH │ HealthCare │ 2 │ 3 │
│ WMT │ ConsumerStaples │ 2 │ 4 │
│ XOM │ Energy │ 1 │ 2 │
└────────┴───────────────────────┴─────────────────┴─────────────┘On this universe the two agree exactly at four clusters and diverge as the cut goes finer. That is worth reading carefully, because it is the honest result rather than the flattering one: a sector classification and a one-year correlation see the same coarse structure here, and the feature route earns its keep in the fine structure, in the merge order, and — most of all — in what happens when the sample moves (§9).
agreement = DataFrame("k" => 2:10, "Adjusted Rand index" => [round(randindex(cutree(clr_cor.res; k = k), cutree(clr_fea.res; k = k))[1]; digits = 3) for k in 2:10])pretty_table(agreement; title = "How far the two hierarchies agree, cut by cut")How far the two hierarchies agree, cut by cut
┌───────┬─────────────────────┐
│ k │ Adjusted Rand index │
│ Int64 │ Float64 │
├───────┼─────────────────────┤
│ 2 │ 0.332 │
│ 3 │ 0.5 │
│ 4 │ 1.0 │
│ 5 │ 0.728 │
│ 6 │ 0.707 │
│ 7 │ 0.879 │
│ 8 │ 0.699 │
│ 9 │ 0.768 │
│ 10 │ 0.692 │
└───────┴─────────────────────┘Plot the clusters for the feature distance clustering.
plot_clusters(clr_fea, rd.nx)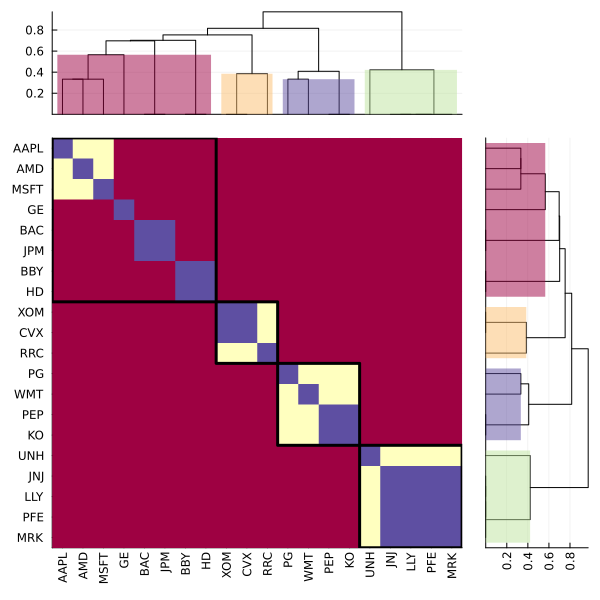
Plot the clusters for the correlation clustering.
plot_clusters(clr_cor, rd.nx)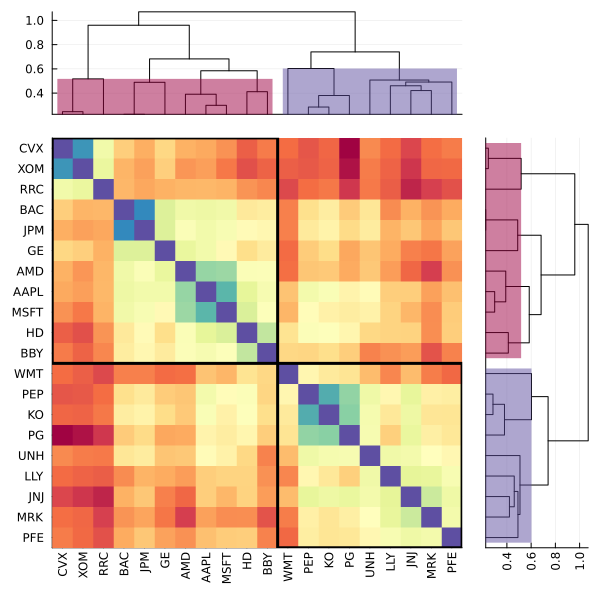
Feeding both hierarchies to HierarchicalRiskParity shows the allocation moving. Nothing on the optimiser selects the feature source: the panel is on the carrier, and the distance estimator reads it.
hrp_cor = optimise(HierarchicalRiskParity(; opt = HierarchicalOptimiser(; pe = pr, cle = cle_cor, slv = slv), r = Variance()), rd)hrp_fea = optimise(HierarchicalRiskParity(; opt = HierarchicalOptimiser(; pe = pr, cle = cle_fea, slv = slv), r = Variance()), rd)pretty_table(DataFrame("Asset" => rd.nx, "HRP correlation" => hrp_cor.w, "HRP features" => hrp_fea.w, "Difference" => hrp_fea.w - hrp_cor.w); formatters = [resfmt], title = "Same risk measure, same prior, two hierarchies")plot_stacked_bar_composition([hrp_cor, hrp_fea], rd; xticks = (1:2, ["Correlation", "Features"]))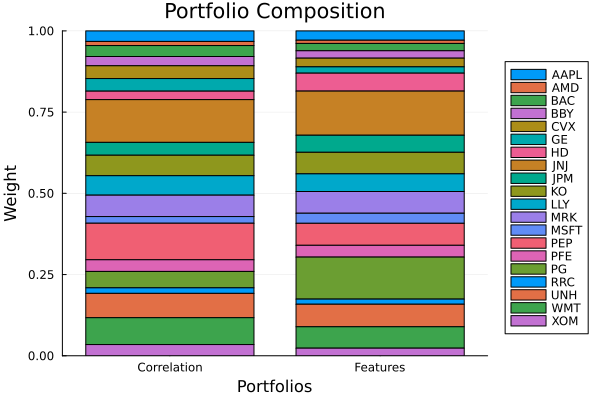
3. Where the panel comes from: the carrier, or a producer
FeatureDistance's ape slot decides which panel gets measured, and it has two settings:
ape = nothing, the default, reads the panel the data carrier holds. This is §2: you built the panel, so you named its fields and you know what is in it.ape = <producer>builds a panel at the point of use, from the prior and the returns the subproblem was handed. A producer is anAbstractAssetPanelEstimator, and the library ships two.
A producer never consults the carrier's panel, and the carrier's panel is never derived. There is one panel per route and no precedence rule to remember.
The rule that separates them is refitting. A carried panel is data, so a fold slices it. A produced panel is recomputed on the subproblem's own returns, so a fold refits it. §8 is where that difference becomes visible.
3.1 RegressionPanel — factor loadings
RegressionPanel reads the loadings a factor prior has already fitted, so an asset's feature row is its position in the factor coordinate system. This is endogenous — the loadings come from the same returns — but it is a genuinely different reading of them: two assets can load alike and still co-move weakly.
The panel it returns holds one TensorPanelField named "loadings", whose trailing axis is labelled with the factor names off the carrier. Loadings are signed, which matters for the metric choice in §5.
F = TimeArray(CSV.File(joinpath(@__DIR__, "..", "Factors.csv.gz")); timestamp = :Date)[(end - 252):end]rdf = prices_to_returns(price_ingestion(PriceIngestion(), X; F = F))pr_loadings = prior(FactorPrior(), rdf)pnl_loadings = asset_panel(RegressionPanel(), pr_loadings, rdf, rdf.X)Z_loadings = feature_matrix(pnl_loadings)pretty_table(DataFrame(["Asset" => rd.nx; [last(l) => Z_loadings[:, k] for (k, l) in pairs(feature_labels(pnl_loadings))]...]); formatters = [(v, i, j) -> j == 1 ? v : round(v; digits = 4)], title = "Factor loadings as a Panel Field") Factor loadings as a Panel Field
┌────────┬─────────┬─────────┬─────────┬─────────┬─────────┐
│ Asset │ MTUM │ QUAL │ SIZE │ USMV │ VLUE │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼─────────┼─────────┼─────────┼─────────┼─────────┤
│ AAPL │ 0.0 │ 1.9094 │ -0.7676 │ 0.0 │ 0.0 │
│ AMD │ 0.377 │ 3.0672 │ 0.0 │ -2.1767 │ 0.0 │
│ BAC │ 0.2536 │ 0.0 │ 0.0 │ -0.5916 │ 1.2588 │
│ BBY │ -0.6824 │ 1.2054 │ 0.0 │ 0.0 │ 0.6803 │
│ CVX │ 0.2959 │ 0.0 │ 0.0 │ -0.8437 │ 1.0085 │
│ GE │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.1353 │
│ HD │ -0.3604 │ 0.8314 │ 0.0 │ 0.5918 │ 0.0 │
│ JNJ │ -0.1454 │ 0.0 │ -0.8823 │ 1.3659 │ 0.3754 │
│ JPM │ 0.0 │ -0.6254 │ 0.4967 │ 0.0 │ 1.1515 │
│ KO │ -0.2146 │ -0.487 │ 0.0 │ 1.3327 │ 0.2825 │
│ LLY │ 0.2717 │ 0.0 │ -0.9266 │ 1.6874 │ 0.0 │
│ MRK │ 0.0 │ 0.0 │ -1.1839 │ 1.356 │ 0.5509 │
│ MSFT │ 0.0 │ 2.0455 │ -0.4585 │ 0.0 │ -0.5295 │
│ PEP │ -0.1564 │ 0.0 │ -0.6833 │ 1.5089 │ 0.2629 │
│ PFE │ 0.0 │ 0.0 │ -0.9477 │ 1.3855 │ 0.521 │
│ PG │ -0.2512 │ 0.0 │ -0.7663 │ 1.666 │ 0.3126 │
│ RRC │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.2234 │
│ UNH │ 0.3807 │ -0.9579 │ 0.0 │ 1.7058 │ 0.0 │
│ WMT │ -0.3598 │ 0.0 │ 0.0 │ 1.1136 │ 0.0 │
│ XOM │ 0.4151 │ -0.9477 │ 0.0 │ 0.0 │ 1.2728 │
└────────┴─────────┴─────────┴─────────┴─────────┴─────────┘A producer that reads a prior needs one, so the prior result is the object clusterise is handed and the data carrier rides beside it as a keyword.
de_loadings = FeatureDistance(; ape = RegressionPanel())clr_loadings = clusterise(ClustersEstimator(; de = de_loadings, onc = onc), pr_loadings; rd = rdf)println("The producer and the panel agree exactly: ", clr_loadings.D == distance(FeatureDistance(), Z_loadings; dims = 1))The producer and the panel agree exactly: true3.2 PhylogenyPanel — the returns graph
PhylogenyPanel turns the asset network into a square assets × assets field: column k reads "how close is this asset to asset k". It is the most endogenous of the routes — the graph is filtered out of the correlation — so it does not bring in outside structure. What it does bring is a graded reading of the network that phylogeny_matrix throws away: that routine accumulates a walk count and then clamps it to 0/1, destroying the step count, while this one keeps it.
Its source is always an estimator, never a precomputed result, so the graph is rebuilt on whatever universe the subproblem hands it. It reads no prior, which makes it the one producer that runs at a pre-prior site such as preselection.
ape_graph = PhylogenyPanel(; pl = NetworkEstimator(; sep = HopCount(; n = 2)), alg = Proximity(; decay = LinearDecay()))pnl_graph = asset_panel(ape_graph, nothing, rd, rd.X)Z_graph = feature_matrix(pnl_graph)pretty_table(DataFrame(["Asset" => rd.nx; [rd.nx[k] => Z_graph[:, k] for k in 1:6]...]); formatters = [(v, i, j) -> j == 1 ? v : round(v; digits = 4)], title = "The first six columns of the graph Panel Field") The first six columns of the graph Panel Field
┌────────┬─────────┬─────────┬─────────┬─────────┬─────────┬─────────┐
│ Asset │ AAPL │ AMD │ BAC │ BBY │ CVX │ GE │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────┼─────────┼─────────┼─────────┼─────────┼─────────┼─────────┤
│ AAPL │ 3.0 │ 2.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │
│ AMD │ 2.0 │ 3.0 │ 0.0 │ 0.0 │ 1.0 │ 2.0 │
│ BAC │ 0.0 │ 0.0 │ 3.0 │ 0.0 │ 0.0 │ 1.0 │
│ BBY │ 0.0 │ 0.0 │ 0.0 │ 3.0 │ 0.0 │ 0.0 │
│ CVX │ 0.0 │ 1.0 │ 0.0 │ 0.0 │ 3.0 │ 2.0 │
│ GE │ 1.0 │ 2.0 │ 1.0 │ 0.0 │ 2.0 │ 3.0 │
│ HD │ 1.0 │ 0.0 │ 0.0 │ 2.0 │ 0.0 │ 0.0 │
│ JNJ │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ JPM │ 0.0 │ 1.0 │ 2.0 │ 0.0 │ 1.0 │ 2.0 │
│ KO │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ LLY │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ MRK │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ MSFT │ 2.0 │ 1.0 │ 0.0 │ 1.0 │ 0.0 │ 0.0 │
│ PEP │ 2.0 │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ PFE │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ PG │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ RRC │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 1.0 │ 0.0 │
│ UNH │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ WMT │ 1.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 0.0 │
│ XOM │ 0.0 │ 0.0 │ 0.0 │ 0.0 │ 2.0 │ 1.0 │
└────────┴─────────┴─────────┴─────────┴─────────┴─────────┴─────────┘Read the diagonal: 3 is the asset itself, 2 a direct neighbour, 1 a two-hop neighbour, 0 unreachable within the budget. §4 explains where those numbers come from — and why they are the one decay setting whose scale depends on the budget.
3.3 The three routes side by side
routes = DataFrame("Route" => ["The carrier's panel", "RegressionPanel", "PhylogenyPanel"], "`ape`" => ["nothing", "RegressionPanel()", "PhylogenyPanel(; …)"], "Feature axis" => ["whatever you named", "factors", "the assets"], "Shape here" => [string(size(Z)), string(size(Z_loadings)), string(size(Z_graph))], "Exogenous" => ["depends on the source", "no", "no"], "Signed" => ["depends on the source", "yes", "no"], "Under a fold" => ["sliced", "refitted", "refitted"])pretty_table(routes; title = "The three routes a Feature Matrix takes") The three routes a Feature Matrix takes
┌─────────────────────┬─────────────────────┬────────────────────┬────────────┬───────────────────────┬───────────────────────┬──────────────┐
│ Route │ `ape` │ Feature axis │ Shape here │ Exogenous │ Signed │ Under a fold │
│ String │ String │ String │ String │ String │ String │ String │
├─────────────────────┼─────────────────────┼────────────────────┼────────────┼───────────────────────┼───────────────────────┼──────────────┤
│ The carrier's panel │ nothing │ whatever you named │ (20, 20) │ depends on the source │ depends on the source │ sliced │
│ RegressionPanel │ RegressionPanel() │ factors │ (20, 5) │ no │ yes │ refitted │
│ PhylogenyPanel │ PhylogenyPanel(; …) │ the assets │ (20, 20) │ no │ no │ refitted │
└─────────────────────┴─────────────────────┴────────────────────┴────────────┴───────────────────────┴───────────────────────┴──────────────┘4. Two knobs on the graph producer, and neither implies the other
PhylogenyPanel is driven by two settings that live on two different objects:
sepon theNetworkEstimatordecides which pairs are related — how far apart two assets may sit and still score above zero.HopCountcounts edges with a budget ofnof them;PathLengthsums distances along the shortest path with a budgetdmaxin those units.decayonProximitydecides how strongly a related pair scores as separation grows.
Setting one does not imply the other, and getting that wrong produces no error at all. The confusion is easy to fall into because the default pairing hides it: under LinearDecay with HopCount, the budget is the top of the scale, so changing sep appears to change the fall-off too. Under any other decay the two separate cleanly.
separations = ["HopCount(; n = 2)" => HopCount(; n = 2), "PathLength(; dmax = 1.0)" => PathLength(; dmax = 1.0)]decays = ["LinearDecay()" => LinearDecay(), "ExponentialDecay()" => ExponentialDecay(), "ReciprocalDecay()" => ReciprocalDecay(), "NoDecay()" => NoDecay()]function graph_panel(sep, decay) ape = PhylogenyPanel(; pl = NetworkEstimator(; sep = sep), alg = Proximity(; decay = decay)) return asset_panel(ape, nothing, rd, rd.X)endsweep = DataFrame()for (sname, sep) in separations, (dname, decay) in decays png = graph_panel(sep, decay) Zg = feature_matrix(png) off = [Zg[i, j] for i in axes(Zg, 1) for j in axes(Zg, 2) if i != j] clg = clusterise(cle_fea, ReturnsResult(; nx = rd.nx, X = rd.X, ts = rd.ts, pnl = png)) append!(sweep, DataFrame("Separation" => sname, "Decay" => dname, "Self score" => Zg[1, 1], "Largest off-diagonal" => maximum(off), "Related pairs" => count(!iszero, off), "ARI vs correlation" => randindex(cutree(clr_cor.res; k = 4), cutree(clg.res; k = 4))[1]))endpretty_table(sweep; formatters = [(v, i, j) -> isa(v, AbstractFloat) ? round(v; digits = 4) : v], title = "Four decays crossed against two separations") Four decays crossed against two separations
┌──────────────────────────┬────────────────────┬────────────┬──────────────────────┬───────────────┬────────────────────┐
│ Separation │ Decay │ Self score │ Largest off-diagonal │ Related pairs │ ARI vs correlation │
│ String │ String │ Float64 │ Float64 │ Int64 │ Float64 │
├──────────────────────────┼────────────────────┼────────────┼──────────────────────┼───────────────┼────────────────────┤
│ HopCount(; n = 2) │ LinearDecay() │ 3.0 │ 2.0 │ 96 │ 0.4762 │
│ HopCount(; n = 2) │ ExponentialDecay() │ 1.0 │ 0.3679 │ 96 │ 0.4762 │
│ HopCount(; n = 2) │ ReciprocalDecay() │ 1.0 │ 0.5 │ 96 │ 0.5053 │
│ HopCount(; n = 2) │ NoDecay() │ 1.0 │ 1.0 │ 96 │ 0.2842 │
│ PathLength(; dmax = 1.0) │ LinearDecay() │ 2.0 │ 1.7747 │ 94 │ 0.4471 │
│ PathLength(; dmax = 1.0) │ ExponentialDecay() │ 1.0 │ 0.7983 │ 94 │ 0.5274 │
│ PathLength(; dmax = 1.0) │ ReciprocalDecay() │ 1.0 │ 0.8161 │ 94 │ 0.4471 │
│ PathLength(; dmax = 1.0) │ NoDecay() │ 1.0 │ 1.0 │ 94 │ 0.2842 │
└──────────────────────────┴────────────────────┴────────────┴──────────────────────┴───────────────┴────────────────────┘Read the table down the columns rather than across the rows:
Related pairsmoves with the separation and never with the decay. Which pairs are related issep's question alone.Self scoreis1.0for every decay exceptLinearDecay, where it is the budget plus one —3underHopCount(; n = 2),2underPathLength(; dmax = 1.0). The other three pinf(0) = 1and set the fall-off from their own parameter, independently of how far the budget looks. That is the whole of the coincidence: under the default pairing the budget doubles as the scale, and under every other it does not.ARI vs correlationmoves with both. The decay is not cosmetic — it changes the distance and the clusters that come out of it.NoDecayis not "no truncation". The budget still cuts, so it gives1inside and0outside: a neighbourhood indicator, not a matrix of ones. It is also the only decay on which the two separations reach the same clustering, because an indicator throws away everything except the support, and these two supports differ by two pairs in ninety-six.
plot(1:size(sweep, 1), sweep[!, "ARI vs correlation"]; marker = :circle, legend = false, xticks = (1:size(sweep, 1), [string(first(split(r.Separation, "(")), " / ", first(split(r.Decay, "("))) for r in eachrow(sweep)]), xrotation = 45, ylabel = "Adjusted Rand index against the correlation cut", title = "Both knobs move the clustering")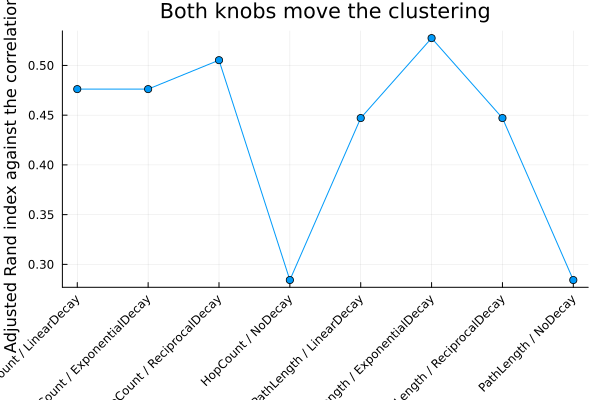
PathLength() with no dmax means the whole connected component. On this path that is a sensible choice — the budget only sets where the fall-off reaches zero, and the decay still grades everything inside it. On the constraint path the identical setting selects instead of shaping, so it declares every reachable pair related and forbids all pairwise co-movement, optimising successfully into a one-asset portfolio. See Phylogeny and centrality constraints §2.2 for that end of it. The bare default also makes the scale of the field depend on the sample — §8.3.
5. Metrics, and the similarity slot
FeatureDistance's metric field takes any Distances.SemiMetric, including one you define. The default is AngularDist, which is the arc-cosine of the cosine similarity scaled to [0, 1] and delegates to Distances' BLAS gemm path.
The choice is not free. Metrics differ in what they are defined on, and one of them fails silently on input outside its domain, which is why the library checks the domain rather than trusting it.
metrics = ["AngularDist()" => AngularDist(), "Distances.CosineDist()" => PortfolioOptimisers.Distances.CosineDist(), "Distances.Jaccard()" => PortfolioOptimisers.Distances.Jaccard()]metric_rows = DataFrame()for (mname, metric) in metrics de = FeatureDistance(; metric = metric) Dm = distance(de, Z; dims = 1) append!(metric_rows, DataFrame("Metric" => mname, "Default similarity" => strip(string(de.sim)), "Maximum distance" => round(maximum(Dm); digits = 4), "Distinct values" => length(unique(round.(Dm; digits = 6)))))endpretty_table(metric_rows; title = "Three metrics on the same classification panel") Three metrics on the same classification panel
┌────────────────────────┬────────────────────────┬──────────────────┬─────────────────┐
│ Metric │ Default similarity │ Maximum distance │ Distinct values │
│ String │ SubString{String} │ Float64 │ Int64 │
├────────────────────────┼────────────────────────┼──────────────────┼─────────────────┤
│ AngularDist() │ AngularSimilarity() │ 0.5 │ 3 │
│ Distances.CosineDist() │ ComplementSimilarity() │ 1.0 │ 3 │
│ Distances.Jaccard() │ ComplementSimilarity() │ 1.0 │ 3 │
└────────────────────────┴────────────────────────┴──────────────────┴─────────────────┘On a partition matrix all three order the pairs identically — only the scale differs, and AngularDist stops at 0.5 because a non-negative matrix admits no negative cosine. They part company as soon as the matrix is signed:
signed_metric = try distance(FeatureDistance(; metric = PortfolioOptimisers.Distances.Jaccard()), Z_loadings; dims = 1) "no error"catch err sprint(showerror, err)endprintln(signed_metric)DomainError with [0.0 1.90943 … 0.0 0.0; 0.37705 3.06717 … -2.17672 0.0; … ; -0.359849 0.0 … 1.1136 0.0; 0.415139 -0.947715 … 0.0 1.27277]:
all(x -> 0 <= x, Z) must hold. Got
count(x -> !(0 <= x), Z) => 23Distances.Jaccard is the Ruzicka form, defined only on non-negative reals, and on signed input it returns values up to 2 with no complaint at all — straight into a clustering routine. The domain check turns that silence into the error above; it covers Distances.BrayCurtis and Distances.ChiSqDist too. Signed Panel Fields — factor loadings above all — want AngularDist or Distances.CosineDist.
The sim slot
Clustering consumers call cor_and_dist, not distance, so a feature distance owes a similarity matrix as well. sim supplies it, defaulted from the metric by default_similarity: AngularDist gets AngularSimilarity, which recovers the cosine exactly as cos(πD), and everything else gets ComplementSimilarity's 1 - D. Set it explicitly to override.
S_fea, D_fea = cor_and_dist(FeatureDistance(), nothing, rd.X; rd = rd)println("S and D share provenance: ", size(S_fea) == size(D_fea))S and D share provenance: true6. Both shapes: static and time-varying
A panel is either static — every field is assets or assets × labels, with no mask — or time-varying, with an observation axis leading every field and an active and an estimation mask beside them. The shape is a property of the panel, and feature_matrix follows it: a static panel stacks to assets × features, a time-varying one to observations × assets × features.
A time-varying matrix has to become one distance matrix somehow, and the alg field says how — an open family with four members.
Here the features are two trailing characteristics that genuinely move: annualised realised volatility over twenty-one days, and cumulative return over sixty-three. They are ordinary numeric Panel Fields, so asset_panel builds them exactly as it built the taxonomy.
T, N = size(rd.X)Zvol = zeros(T, N)Zmom = zeros(T, N)for t in 1:T, i in 1:N Zvol[t, i] = std(view(rd.X, max(1, t - 20):t, i)) * sqrt(252) Zmom[t, i] = sum(view(rd.X, max(1, t - 62):t, i))endZvol[1, :] .= Zvol[2, :]pnl_tv = asset_panel([NumericPanelInput(; name = "volatility", vals = Zvol), NumericPanelInput(; name = "momentum", vals = Zmom)])Ztv = feature_matrix(pnl_tv)collapses = ["LastObservation()" => LastObservation(), "AggregateFeatures()" => AggregateFeatures(), "AggregateDistances()" => AggregateDistances(), "StackObservations()" => StackObservations()]collapse_rows = DataFrame()for (cname, alg) in collapses Dc = distance(FeatureDistance(; alg = alg), Ztv; dims = 1) D1 = distance(FeatureDistance(; alg = alg), reshape(Ztv[end, :, :], 1, N, 2); dims = 1) append!(collapse_rows, DataFrame("Collapse" => cname, "Mean distance" => round(mean(Dc); digits = 4), "Maximum distance" => round(maximum(Dc); digits = 4), "Mean at T = 1" => round(mean(D1); digits = 6)))endpretty_table(collapse_rows; title = "Four collapse rules on one $(size(Ztv, 1))×$(size(Ztv, 2))×$(size(Ztv, 3)) Feature Matrix") Four collapse rules on one 252×20×2 Feature Matrix
┌──────────────────────┬───────────────┬──────────────────┬───────────────┐
│ Collapse │ Mean distance │ Maximum distance │ Mean at T = 1 │
│ String │ Float64 │ Float64 │ Float64 │
├──────────────────────┼───────────────┼──────────────────┼───────────────┤
│ LastObservation() │ 0.1243 │ 0.4684 │ 0.12428 │
│ AggregateFeatures() │ 0.0739 │ 0.2265 │ 0.12428 │
│ AggregateDistances() │ 0.1163 │ 0.2197 │ 0.12428 │
│ StackObservations() │ 0.1613 │ 0.2731 │ 0.12428 │
└──────────────────────┴───────────────┴──────────────────┴───────────────┘The four rules give four different answers, and they are different in kind:
LastObservation(the default) takes the most recent slice and ignores the rest.AggregateFeaturesaverages the features first, then measures once.AggregateDistancesmeasures each period, then averages the distance matrices. It refusesMedianCollapseat construction, because a convex combination of metrics is a metric while a median of distance matrices is not.StackObservationsconcatenates every period into one long coordinate vector. It is the most scale-exposed of the four, since a period with large magnitudes dominates.
The last column is the degeneracy that shows they are the same idea: at one observation all four agree exactly. A static panel never reads alg at all — it is inert there, not an error, because one estimator serves both shapes.
Both aggregating rules take observation weights on a w field, so an exponential decay or an entropy-pooling posterior reaches the collapse.
plot([distance(FeatureDistance(; alg = alg), Ztv; dims = 1)[1, :] for (_, alg) in collapses]; label = reshape([c for (c, _) in collapses], 1, :), marker = :circle, xticks = (1:N, rd.nx), xrotation = 90, ylabel = "Distance from AAPL", title = "The collapse rule is a modelling choice, not a detail")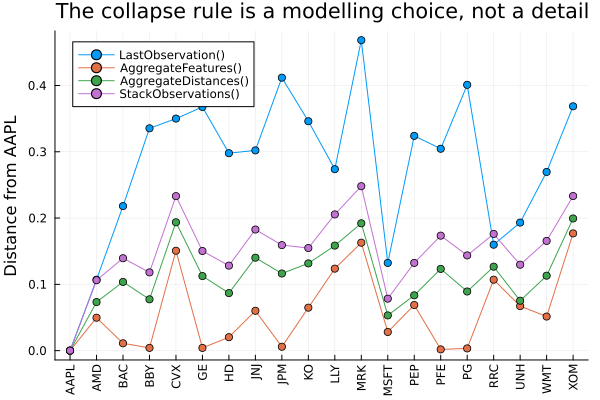
6.1 A static field on a time-varying panel is lifted, not copied
A panel is one shape throughout, so a static input that meets a time-varying one is lifted: asset_panel wraps its values in a RepeatedLeading, which stores them once and indexes a leading observation axis. Mixing a classification that never moves with characteristics that move every day therefore costs the memory of the classification, not of the classification times the observation count.
pnl_mixed = asset_panel([panel_input(sets, taxonomy); NumericPanelInput(; name = "volatility", vals = Zvol); NumericPanelInput(; name = "momentum", vals = Zmom)])held(f) = isa(f, CategoricalPanelField) ? f.codes : f.valsstored(v) = isa(v, PortfolioOptimisers.RepeatedLeading) ? length(v.parent) : length(v)pretty_table(DataFrame("Panel Field" => [f.name for f in pnl_mixed.pf], "Values type" => [string(nameof(typeof(held(f)))) for f in pnl_mixed.pf], "Shape it presents" => [string(size(held(f))) for f in pnl_mixed.pf], "Entries stored" => [stored(held(f)) for f in pnl_mixed.pf]); title = "A lifted field presents an observation axis it does not store") A lifted field presents an observation axis it does not store
┌─────────────┬─────────────────┬───────────────────┬────────────────┐
│ Panel Field │ Values type │ Shape it presents │ Entries stored │
│ String │ String │ String │ Int64 │
├─────────────┼─────────────────┼───────────────────┼────────────────┤
│ sector │ RepeatedLeading │ (252, 20) │ 20 │
│ industry │ RepeatedLeading │ (252, 20) │ 20 │
│ volatility │ Array │ (252, 20) │ 5040 │
│ momentum │ Array │ (252, 20) │ 5040 │
└─────────────┴─────────────────┴───────────────────┴────────────────┘7. The selector reads one namespace
FeatureDistance's sel field names what to stack, and it reads the panel's own field index — there is no second namespace and no integer column to count. An entry takes one of four forms:
| Entry | Columns it contributes |
|---|---|
"name" | every column of that Panel Field |
"name" => ["a", "b"] | the levels or labels listed, in that order |
"name" => "a" | one level or label |
"name" => :observed | that field's observed mask, one 0/1 column |
Entries may be mixed, the vector order is the column order, and nothing — the default — is every field's values in field order. A bare name is the values alone, never the mask.
selectors = ["nothing (every field)" => nothing, "[\"sector\"]" => ["sector"], "[\"industry\"]" => ["industry"], "[\"sector\" => \"Energy\", \"industry\"]" => ["sector" => "Energy", "industry"], "[\"sector\" => [\"Energy\", \"HealthCare\"]]" => ["sector" => ["Energy", "HealthCare"]]]selector_rows = DataFrame()for (sname, sel) in selectors Zs = feature_matrix(pnl, sel) Ds = distance(FeatureDistance(), Zs; dims = 1) append!(selector_rows, DataFrame("Selector" => sname, "Columns" => size(Zs, 2), "Distinct distances" => length(unique(round.(Ds; digits = 6))), "Maximum distance" => round(maximum(Ds); digits = 4)))endpretty_table(selector_rows; title = "One namespace, five cuts of the same panel") One namespace, five cuts of the same panel
┌────────────────────────────────────────┬─────────┬────────────────────┬──────────────────┐
│ Selector │ Columns │ Distinct distances │ Maximum distance │
│ String │ Int64 │ Int64 │ Float64 │
├────────────────────────────────────────┼─────────┼────────────────────┼──────────────────┤
│ nothing (every field) │ 20 │ 3 │ 0.5 │
│ ["sector"] │ 7 │ 2 │ 0.5 │
│ ["industry"] │ 13 │ 2 │ 0.5 │
│ ["sector" => "Energy", "industry"] │ 14 │ 3 │ 0.5 │
│ ["sector" => ["Energy", "HealthCare"]] │ 2 │ 3 │ 1.0 │
└────────────────────────────────────────┴─────────┴────────────────────┴──────────────────┘Cutting to "sector" alone gives two distances rather than three: the industry level is what separated same-sector pairs. Cutting to two levels of one field moves the bound as well. An asset that belongs to neither kept level has a zero feature row, so the maximum distance goes to 1.0 rather than the 0.5 a whole partition guarantees.
The selector goes on the estimator, so the cut is configuration and the panel is data:
de_coarse = FeatureDistance(; sel = ["sector"])clr_coarse = clusterise(ClustersEstimator(; de = de_coarse, onc = onc), rd)println("The coarse cut and the full panel differ: ", clr_coarse.D != clr_fea.D)println("The estimator's own labels: ", feature_labels(de_coarse, pr, rd, rd.X))The coarse cut and the full panel differ: true
The estimator's own labels: ["sector" => "ConsumerDiscretionary", "sector" => "ConsumerStaples", "sector" => "Energy", "sector" => "Financials", "sector" => "HealthCare", "sector" => "Industrials", "sector" => "Technology"]7.1 strict, and an entry the panel does not carry
strict is the library-wide rule, and it applies here to a name, a level or a label the panel does not carry. Under strict = false — the default — the entry is dropped with a warning, and under strict = true it raises. Dropping is what lets one estimator serve a universe whose panel loses a field, which is the ordinary case inside a fold.
dropped = feature_matrix(pnl, ["not_a_field", "sector"])println("The unknown entry was dropped: ", size(dropped, 2) == 7)strict_error = try feature_matrix(pnl, ["not_a_field", "sector"]; strict = true) "no error"catch err sprint(showerror, err)endprintln(strict_error)┌ Warning: `sel` names `not_a_field`, which is not a Panel Field of the Asset Panel. It holds 2: sector, industry. Under `strict = false` the entry is dropped.
└ @ PortfolioOptimisers ~/work/PortfolioOptimisers.jl/PortfolioOptimisers.jl/src/01_Base/06_Messages.jl:267
The unknown entry was dropped: true
ArgumentError: `sel` names `not_a_field`, which is not a Panel Field of the Asset Panel. It holds 2: sector, industry. Under `strict = false` the entry is dropped.7.2 The observed mask is a column you can select
A Panel Field built from a table with gaps records which cells were observed, and the mask survives the fill. "name" => :observed puts it in the matrix as one 0/1 column, so "reported at all" becomes a feature in its own right — which is often the sharpest signal a sparse fundamentals table carries. On a field with no mask the column is all ones, which is the honest reading: nothing was missing.
Zgap = copy(Zvol)Zgap[1:40, 1:3] .= NaNpnl_gap = asset_panel([NumericPanelInput(; name = "volatility", vals = Zgap, alg = BackwardPanelFill())])Zobs = feature_matrix(pnl_gap, ["volatility" => :observed])Zboth = feature_matrix(pnl_gap, ["volatility", "volatility" => :observed])pretty_table(DataFrame("Selector entry" => ["[\"volatility\"]", "[\"volatility\" => :observed]", "both, in that order"], "Shape" => [string(size(feature_matrix(pnl_gap, ["volatility"]))), string(size(Zobs)), string(size(Zboth))], "Mean of the last column" => [round(mean(Zgap[.!isnan.(Zgap)]); digits = 4), round(mean(Zobs); digits = 4), round(mean(selectdim(Zboth, 3, 2)); digits = 4)]); title = "The mask a fill policy left behind") The mask a fill policy left behind
┌─────────────────────────────┬──────────────┬─────────────────────────┐
│ Selector entry │ Shape │ Mean of the last column │
│ String │ String │ Float64 │
├─────────────────────────────┼──────────────┼─────────────────────────┤
│ ["volatility"] │ (252, 20, 1) │ 0.3092 │
│ ["volatility" => :observed] │ (252, 20, 1) │ 0.9762 │
│ both, in that order │ (252, 20, 2) │ 0.9762 │
└─────────────────────────────┴──────────────┴─────────────────────────┘8. Under a fold, and under a meta-optimiser
8.1 The square case: slicing and measuring do not commute
The rule is features_are_assets, and it compares names, not axis lengths: when a tensor Panel Field's labels are the carrier's asset names, the field's label axis is the asset axis, so an asset view slices it too. That makes a square, asset-keyed field the one shape where measuring a subproblem is not the same as reading a subproblem out of the universe's distance matrix. Nothing records the fact — it is derived at the view, by name.
rd_square = ReturnsResult(; nx = rd.nx, X = rd.X, ts = rd.ts, pnl = pnl_graph)subset = [1, 2, 3, 5, 8, 10, 13, 17]view_square = PortfolioOptimisers.port_opt_view(rd_square, subset)view_rect = PortfolioOptimisers.port_opt_view(rd, subset)commute = DataFrame("Feature axis" => ["The assets (square)", "Taxonomy levels (rectangular)"], "Shape of the view" => [string(size(feature_matrix(view_square.pnl))), string(size(feature_matrix(view_rect.pnl)))], "Largest disagreement" => [maximum(abs, distance(FeatureDistance(), Z_graph; dims = 1)[subset, subset] - distance(FeatureDistance(), feature_matrix(view_square.pnl); dims = 1)), maximum(abs, distance(FeatureDistance(), Z; dims = 1)[subset, subset] - distance(FeatureDistance(), feature_matrix(view_rect.pnl); dims = 1))])pretty_table(commute; formatters = [(v, i, j) -> isa(v, AbstractFloat) ? round(v; digits = 4) : v], title = "Measuring the subproblem against measuring the universe") Measuring the subproblem against measuring the universe
┌───────────────────────────────┬───────────────────┬──────────────────────┐
│ Feature axis │ Shape of the view │ Largest disagreement │
│ String │ String │ Float64 │
├───────────────────────────────┼───────────────────┼──────────────────────┤
│ The assets (square) │ (8, 8) │ 0.0768 │
│ Taxonomy levels (rectangular) │ (8, 20) │ 0.0 │
└───────────────────────────────┴───────────────────┴──────────────────────┘The rectangular case agrees to the last bit: its columns are the same twenty groups whichever assets you keep, so slicing rows and measuring commute. The square case does not, and the gap is not noise — it is the difference between "how close are these two assets within this cluster" and "how close are they in the whole universe". Neither reading is wrong; they are different questions, and the shape of the field is what chooses between them.
A produced panel never faces the choice. A producer refits on whatever universe it is handed, so PhylogenyPanel rebuilds the graph on the cluster rather than cutting a description of the universe down to it.
8.2 A meta-optimiser's outer problem
A meta-optimiser's outer problem is defined over synthetic assets — sub-portfolios, clusters, predictions — which have no rows in any panel. The outer problem is nevertheless feature-capable: the inner universe's panel is collapsed onto the synthetic assets by the inner weights, one field at a time, so an outer FeatureDistance measures the sub-portfolios' features rather than failing.
The collapse is closed on the panel, not on the matrix. A numeric field stays numeric, a tensor field stays tensor, and a categorical field becomes a tensor field of membership fractions over its own levels — so a cluster's row reads "this cluster's weighted-average membership of each group", and a selector that named "sector" resolves unchanged on the outer panel.
nco = NestedClustered(; pe = pr, cle = cle_fea, opti = HierarchicalRiskParity(; opt = HierarchicalOptimiser(; pe = pr, cle = cle_cor, slv = slv), r = Variance()), opto = HierarchicalRiskParity(; opt = HierarchicalOptimiser(; cle = cle_fea, slv = slv), r = Variance()))res_nco = optimise(nco, rd)println("Outer problem solved on the collapsed panel: ", isa(res_nco.retcode, OptimisationSuccess))Outer problem solved on the collapsed panel: trueA square, asset-keyed field is contracted on both axes at once, so it stays square on the synthetic universe. A mask collapses as the support of its convex combination, (Wᵀ · m) .> 0: a synthetic asset is observed when any asset that funds it was.
8.3 A bare PathLength() makes the scale sample-dependent
PathLength with no dmax resolves its budget to the graph's observed diameter. Under LinearDecay the top of the scale is the budget plus one, so a diameter that moves between folds moves the whole field with it. Rolling a one-year window forward a quarter at a time over five years:
Xb = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 1260):end]rdb = prices_to_returns(Xb)windows = [(i, i + 251) for i in 1:63:(size(rdb.X, 1) - 251)]function window_row(lo, hi) Xw = prior(EmpiricalPrior(), rdb.X[lo:hi, :]).X seps = separation_matrix(PathLength(), NetworkEstimator(), Xw) Zbare = phylogeny_features(Proximity(; decay = LinearDecay()), NetworkEstimator(; sep = PathLength()), Xw) Zfixed = phylogeny_features(Proximity(; decay = LinearDecay()), NetworkEstimator(; sep = PathLength(; dmax = 1.5)), Xw) return (; Window = "$(lo)–$(hi)", var"Observed diameter" = maximum(filter(isfinite, seps)), var"Self score, bare" = Zbare[1, 1], var"Self score, dmax = 1.5" = Zfixed[1, 1])enddiameters = DataFrame([window_row(lo, hi) for (lo, hi) in windows])pretty_table(diameters; formatters = [(v, i, j) -> isa(v, AbstractFloat) ? round(v; digits = 4) : v], title = "The bare budget follows the sample; a stated one does not")plot(1:length(windows), diameters[!, "Self score, bare"]; marker = :circle, label = "PathLength()", xlabel = "Rolling window", ylabel = "Top of the scale", title = "A data-dependent budget moves the whole Panel Field")plot!(1:length(windows), diameters[!, "Self score, dmax = 1.5"]; marker = :square, label = "PathLength(; dmax = 1.5)")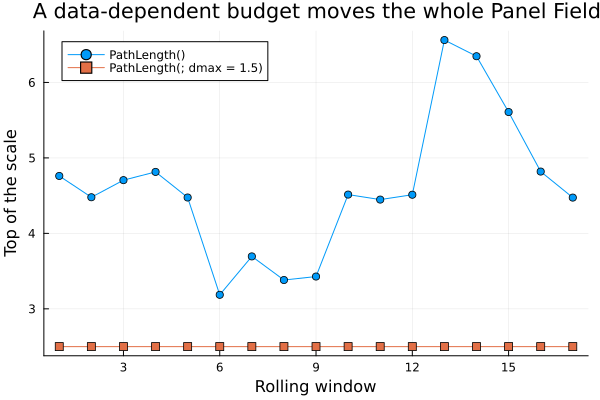
The diameter roughly doubles across these windows and the scale follows it exactly. What makes that worse than it sounds is how it moves. The difference between a bare budget and a stated one is a constant added to every in-budget entry, not a factor multiplying them:
Xw1 = prior(EmpiricalPrior(), rdb.X[1:252, :]).XZ_bare = phylogeny_features(Proximity(; decay = LinearDecay()), NetworkEstimator(; sep = PathLength()), Xw1)Z_fixed = phylogeny_features(Proximity(; decay = LinearDecay()), NetworkEstimator(; sep = PathLength(; dmax = 3.0)), Xw1)shared = (Z_bare .!= 0) .&& (Z_fixed .!= 0)D_bare = distance(FeatureDistance(), Z_bare; dims = 1)D_scaled = distance(FeatureDistance(), 7.3 .* Z_bare; dims = 1)Z_shifted = copy(Z_bare)Z_shifted[Z_bare .!= 0] .+= 1.0D_shifted = distance(FeatureDistance(), Z_shifted; dims = 1)pretty_table(DataFrame("Quantity" => ["Distinct differences on the shared support", "The difference itself", "Distance change from rescaling by 7.3", "Distance change from adding 1.0 on the support"], "Value" => [string(length(unique(round.(Z_bare[shared] - Z_fixed[shared]; digits = 8)))), string(round(first(unique(round.(Z_bare[shared] - Z_fixed[shared]; digits = 8))); digits = 6)), string(round(maximum(abs, D_scaled - D_bare); digits = 12)), string(round(maximum(abs, D_shifted - D_bare); digits = 4))]); title = "A shift is not a rescale, and only one of them is invisible") A shift is not a rescale, and only one of them is invisible
┌────────────────────────────────────────────────┬──────────┐
│ Quantity │ Value │
│ String │ String │
├────────────────────────────────────────────────┼──────────┤
│ Distinct differences on the shared support │ 1 │
│ The difference itself │ 0.761185 │
│ Distance change from rescaling by 7.3 │ 0.0 │
│ Distance change from adding 1.0 on the support │ 0.0603 │
└────────────────────────────────────────────────┴──────────┘AngularDist is invariant to rescaling an asset's whole row — that is why the third row is zero to machine precision — but a shift changes the direction the row points, and the fourth row is the proof. So a moving diameter is not absorbed by the metric's invariance: it reshapes the distance fold by fold.
Two ways out, and both are one keyword:
- State a numeric
dmax, which pins the budget and the scale across every fold. - Use a decay that pins
f(0) = 1—ExponentialDecay,ReciprocalDecayorNoDecay— which never had the exposure in the first place.
9. A walk-forward backtest
The sharpest argument for an exogenous panel is what it does to stability. A correlation hierarchy is refitted from scratch every fold and moves whenever the covariance does; a classification does not move at all. Walking forward over five years with one-year training windows and quarterly rebalances:
sets_bt = UniverseSets(; xkey = "nx", dict = Dict("nx" => rdb.nx, "nx_sector" => [sector[a] for a in rdb.nx], "nx_industry" => [industry[a] for a in rdb.nx]))rdbz = ReturnsResult(; nx = rdb.nx, X = rdb.X, ts = rdb.ts, pnl = asset_panel(panel_input(sets_bt, taxonomy)))walk = IndexWalkForward(252, 63)bt_cor = cross_val_predict(HierarchicalRiskParity(; opt = HierarchicalOptimiser(; pe = EmpiricalPrior(), cle = ClustersEstimator(), slv = slv), r = Variance()), rdb, walk)bt_fea = cross_val_predict(HierarchicalRiskParity(; opt = HierarchicalOptimiser(; pe = EmpiricalPrior(), cle = ClustersEstimator(; de = FeatureDistance()), slv = slv), r = Variance()), rdbz, walk)function backtest_row(name, p) r = p.mrd.X turn = mean(abs, reduce(vcat, [p.pred[i + 1].res.w - p.pred[i].res.w for i in 1:(length(p.pred) - 1)])) return (; Hierarchy = name, var"Annual return" = mean(r) * 252, var"Annual volatility" = std(r) * sqrt(252), var"Sharpe ratio" = mean(r) / std(r) * sqrt(252), var"Maximum drawdown" = expected_risk(MaximumDrawdown(), p), var"Mean weight change" = turn)endpretty_table(DataFrame([backtest_row("Correlation", bt_cor), backtest_row("Classification", bt_fea)]); formatters = [(v, i, j) -> isa(v, AbstractFloat) ? round(v; digits = 4) : v], title = "Out-of-sample, $(length(bt_cor.pred)) quarterly rebalances") Out-of-sample, 16 quarterly rebalances
┌────────────────┬───────────────┬───────────────────┬──────────────┬──────────────────┬────────────────────┐
│ Hierarchy │ Annual return │ Annual volatility │ Sharpe ratio │ Maximum drawdown │ Mean weight change │
│ String │ Float64 │ Float64 │ Float64 │ Float64 │ Float64 │
├────────────────┼───────────────┼───────────────────┼──────────────┼──────────────────┼────────────────────┤
│ Correlation │ 0.197 │ 0.1956 │ 1.0071 │ 0.3085 │ 0.0124 │
│ Classification │ 0.1977 │ 0.1956 │ 1.0108 │ 0.2915 │ 0.0054 │
└────────────────┴───────────────┴───────────────────┴──────────────┴──────────────────┴────────────────────┘Return and volatility are effectively identical, and the drawdown is a little better. The interesting column is the last one: the classification hierarchy changes its weights by less than half as much between rebalances. That is not a modelling trick — it follows directly from where the structure comes from. A sector does not move when a correlation does, so the dendrogram, the merge order and the recursive bisection all stay put, and the only thing left moving is the risk estimate inside each cluster.
That is the trade to weigh. An exogenous panel gives up the ability to react to a structural break the returns can see, and buys a hierarchy that does not churn.
plot_portfolio_cumulative_returns(bt_fea)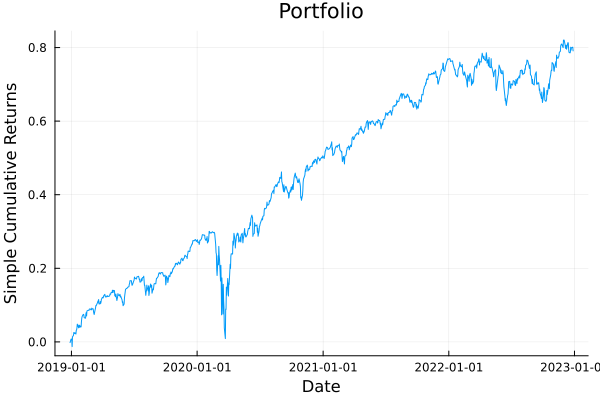
10. Summary
- An
AssetPanelis the data, one Panel Field per named quantity, and it rides on theReturnsResultbeside the returns.feature_matrixstacks it where a distance measures it, and nothing stores the result. FeatureDistanceturns that matrix into a distance, so every clustering, network and constraint consumer takes it unchanged.apepicks the panel:nothingreads the carrier's, a producer builds one at the point of use.RegressionPanelandPhylogenyPanelare the two the library ships, and both are endogenous. The exogenous route — the one the whole exercise exists for — is the carrier's own panel, whichpanel_inputfills from a taxonomy.selreads one namespace, the panel's own field index: a name, a name with the levels or labels it keeps, or a name with its observed mask.strictdecides whether an absent entry is dropped or raises.PhylogenyPanelhas two independent knobs on two different objects:sepchooses which pairs are related,decayhow strongly. Neither implies the other, and the default pairing hides the difference.- Under a fold a carried panel is sliced and a produced one is refitted. A square, asset-keyed field is sliced on its label axis too, so measuring a subproblem and reading it out of the universe's distance matrix are different questions.
- A bare
PathLength()makes the scale of a graph field follow the sample, and a shift is not somethingAngularDist's scale invariance absorbs.
This page was generated using Literate.jl.