The source files can be found in examples/.
Near optimal centering
A plain optimiser returns the one point that maximises or minimises its objective, such as the maximum-ratio portfolio or the minimum-variance portfolio. That point often sits in a corner of the feasible set. It puts most of the money on a few assets, and a small change to the inputs moves it a long way. NearOptimalCentering, or NOC, gives up a little of the objective to move less. It returns the analytic centre of the near-optimal region, which holds the portfolios whose objective is close to the best one. bins sets the size of that region by splitting the efficient frontier into that many steps.
The efficient-frontier page and the Pareto-surface page both use NOC to trace a curve. This page asks a different question, which is how far the centred portfolio sits from the extreme point of the same objective.
Reach for NOC when the MeanRisk objective is the one you want and its corner solution is not. You get a portfolio with a high risk-adjusted return that does not rest on two assets, and it moves less when the prior changes. Use UnconstrainedNearOptimalCentering when weight bounds and budgets are the only constraints the centred portfolio must meet, and ConstrainedNearOptimalCentering when it must also meet the linear, cardinality, turnover and other constraints you set, which is a harder solve. If the extreme point is what you want, use MeanRisk.
using PortfolioOptimisers, PrettyTablesresfmt = (v, i, j) -> begin if j == 1 return v else return isa(v, Number) ? "$(round(v*100, digits=3)) %" : v endend;1. Data
We use one year of daily prices for twenty S&P 500 stocks.
using CSV, TimeSeries, DataFramesX = TimeArray(CSV.File(joinpath(@__DIR__, "..", "SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(X)ReturnsResult
nx ┼ 20-element Vector{String}
X ┼ 252×20 Matrix{Float64}
nf ┼ nothing
F ┼ nothing
nb ┼ nothing
B ┼ nothing
ne ┼ nothing
E ┼ nothing
ts ┼ 252-element Vector{Date}
iv ┼ nothing
ivpa ┼ nothing
pnl ┴ nothing
2. Prior and solvers
NOC splits the frontier into bins and then centres inside a region, so it solves a harder problem than a plain MeanRisk. One solver setting can fail to converge on it. We pass a vector of solvers whose max_step_fraction falls from one to the next, and the optimiser tries each in turn until one returns a solution.
We also pass StandardDeviation, which is NOC's default risk measure and states risk as a second-order cone. A plain Variance states it as a quadratic expression. NOC warns on a quadratic risk expression and then fails to solve on this data, so reach for StandardDeviation here.
using Clarabelslv = [Solver(; name = Symbol("clarabel$i"), solver = Clarabel.Optimizer, settings = Dict("verbose" => false, "max_step_fraction" => f), check_sol = (; allow_local = true, allow_almost = true)) for (i, f) in enumerate((0.99, 0.95, 0.9, 0.85, 0.8, 0.75, 0.7))]pr = prior(EmpiricalPrior(), rd)rf = 4.2 / 100 / 252opt = JuMPOptimiser(; pe = pr, slv = slv)JuMPOptimiser
pe ┼ LowOrderPrior
│ X ┼ 252×20 Matrix{Float64}
│ o_X ┼ nothing
│ mu ┼ 20-element Vector{Float64}
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ w ┼ nothing
│ ens ┼ nothing
│ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ kld ┼ nothing
│ ow ┼ nothing
│ rr ┼ nothing
│ fpr ┼ nothing
│ x_src ┼ nothing
│ ss_gaps ┼ nothing
│ pc ┴ nothing
slv ┼ 7-element Vector{Solver}
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
│ Solver ⋯
cbe ┼ ConstraintBlock
│ wb ┼ WeightBounds
│ │ lb ┼ Float64: 0.0
│ │ ub ┴ Float64: 1.0
│ sbgt ┼ nothing
│ gbgt ┼ nothing
│ lt ┼ nothing
│ st ┼ nothing
│ lcse ┼ nothing
│ cte ┼ nothing
│ gcarde ┼ nothing
│ sgcarde ┼ nothing
│ smtx ┼ nothing
│ sgmtx ┼ nothing
│ slt ┼ nothing
│ sst ┼ nothing
│ sglt ┼ nothing
│ sgst ┼ nothing
│ tn ┼ nothing
│ sets ┼ nothing
│ tr ┼ nothing
│ ple ┼ nothing
│ ccnt ┼ nothing
│ cobj ┼ nothing
│ ss ┼ nothing
│ card ┼ nothing
│ scard ┼ nothing
│ l2c ┼ nothing
│ lpc ┼ nothing
│ linfc ┼ nothing
│ l1 ┼ nothing
│ l2 ┼ nothing
│ lp ┼ nothing
│ linf ┼ nothing
│ xbgt ┴ Bool: false
bgt ┼ Float64: 1.0
fees ┼ nothing
ret ┼ ArithmeticReturn
│ settings ┼ JuMPReturnsSettings
│ │ scale ┼ Float64: 1.0
│ │ lb ┼ nothing
│ │ rte ┼ Bool: true
│ │ fee ┼ Bool: true
│ │ mic ┴ Bool: true
│ ucs ┼ nothing
│ mu ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
sca ┼ nothing
sc ┼ Int64: 1
so ┼ Int64: 1
strict ┴ Bool: false
3. The reference: a MeanRisk corner solution
We first solve for the largest risk-adjusted return. This is the extreme point that NOC centres around. rf is the daily risk-free rate that the ratio subtracts from the expected return, 4.2% a year divided by 252 trading days.
res_mr = optimise(MeanRisk(; r = StandardDeviation(), obj = MaximumRatio(; rf = rf), opt = opt))MeanRiskResult
jr ┼ JuMPOptimisationResult
│ jor ┼ ResolvedJuMPOptimiser
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ fees ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ nothing
│ │ imsk ┼ nothing
│ │ cbr ┼ ResolvedConstraintBlock
│ │ │ pr ┼ LowOrderPrior
│ │ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ │ o_X ┼ nothing
│ │ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ │ chol ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ ens ┼ nothing
│ │ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ │ kld ┼ nothing
│ │ │ │ ow ┼ nothing
│ │ │ │ rr ┼ nothing
│ │ │ │ fpr ┼ nothing
│ │ │ │ x_src ┼ nothing
│ │ │ │ ss_gaps ┼ nothing
│ │ │ │ pc ┴ nothing
│ │ │ rd ┼ ReturnsResult
│ │ │ │ nx ┼ nothing
│ │ │ │ X ┼ nothing
│ │ │ │ nf ┼ nothing
│ │ │ │ F ┼ nothing
│ │ │ │ nb ┼ nothing
│ │ │ │ B ┼ nothing
│ │ │ │ ne ┼ nothing
│ │ │ │ E ┼ nothing
│ │ │ │ ts ┼ nothing
│ │ │ │ iv ┼ nothing
│ │ │ │ ivpa ┼ nothing
│ │ │ │ pnl ┴ nothing
│ │ │ wb ┼ WeightBounds
│ │ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ lt ┼ nothing
│ │ │ st ┼ nothing
│ │ │ lcsr ┼ nothing
│ │ │ ctr ┼ nothing
│ │ │ gcardr ┼ nothing
│ │ │ sgcardr ┼ nothing
│ │ │ smtx ┼ nothing
│ │ │ sgmtx ┼ nothing
│ │ │ slt ┼ nothing
│ │ │ sst ┼ nothing
│ │ │ sglt ┼ nothing
│ │ │ sgst ┼ nothing
│ │ │ tn ┼ nothing
│ │ │ plr ┼ nothing
│ │ │ l2c ┼ nothing
│ │ │ lpc ┼ nothing
│ │ │ linfc ┼ nothing
│ │ │ l1 ┼ nothing
│ │ │ l2 ┼ nothing
│ │ │ lp ┼ nothing
│ │ │ linf ┼ nothing
│ │ │ card ┼ nothing
│ │ │ scard ┼ nothing
│ │ │ ss ┼ nothing
│ │ │ xbgt ┼ Bool: false
│ │ │ sbgt ┼ nothing
│ │ │ gbgt ┼ nothing
│ │ │ ccnt ┼ nothing
│ │ │ cobj ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: AffExpr
│ │ ├ num_variables: 22
│ │ ├ num_constraints: 6
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 2
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ └ VariableRef in MOI.GreaterThan{Float64}: 1
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :csd_risk_soc_1, :k, :lw, :obj_expr, :ohf, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :sd_risk_1, :sdp_corner, :so, :sr_ret, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ StandardDeviation
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
fb ┴ nothing
4. Unconstrained near optimal centering
The next cell runs the same objective through NOC. UnconstrainedNearOptimalCentering keeps the weight bounds and the budgets on the centred portfolio and leaves the other constraints of the problem off it, which keeps the solve cheap.
res_noc_u = optimise(NearOptimalCentering(; r = StandardDeviation(), obj = MaximumRatio(; rf = rf), opt = opt, alg = UnconstrainedNearOptimalCentering()))NearOptimalCenteringResult
jr ┼ JuMPOptimisationResult
│ jor ┼ ResolvedJuMPOptimiser
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ fees ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ nothing
│ │ imsk ┼ nothing
│ │ cbr ┼ ResolvedConstraintBlock
│ │ │ pr ┼ LowOrderPrior
│ │ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ │ o_X ┼ nothing
│ │ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ │ chol ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ ens ┼ nothing
│ │ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ │ kld ┼ nothing
│ │ │ │ ow ┼ nothing
│ │ │ │ rr ┼ nothing
│ │ │ │ fpr ┼ nothing
│ │ │ │ x_src ┼ nothing
│ │ │ │ ss_gaps ┼ nothing
│ │ │ │ pc ┴ nothing
│ │ │ rd ┼ ReturnsResult
│ │ │ │ nx ┼ nothing
│ │ │ │ X ┼ nothing
│ │ │ │ nf ┼ nothing
│ │ │ │ F ┼ nothing
│ │ │ │ nb ┼ nothing
│ │ │ │ B ┼ nothing
│ │ │ │ ne ┼ nothing
│ │ │ │ E ┼ nothing
│ │ │ │ ts ┼ nothing
│ │ │ │ iv ┼ nothing
│ │ │ │ ivpa ┼ nothing
│ │ │ │ pnl ┴ nothing
│ │ │ wb ┼ WeightBounds
│ │ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ lt ┼ nothing
│ │ │ st ┼ nothing
│ │ │ lcsr ┼ nothing
│ │ │ ctr ┼ nothing
│ │ │ gcardr ┼ nothing
│ │ │ sgcardr ┼ nothing
│ │ │ smtx ┼ nothing
│ │ │ sgmtx ┼ nothing
│ │ │ slt ┼ nothing
│ │ │ sst ┼ nothing
│ │ │ sglt ┼ nothing
│ │ │ sgst ┼ nothing
│ │ │ tn ┼ nothing
│ │ │ plr ┼ nothing
│ │ │ l2c ┼ nothing
│ │ │ lpc ┼ nothing
│ │ │ linfc ┼ nothing
│ │ │ l1 ┼ nothing
│ │ │ l2 ┼ nothing
│ │ │ lp ┼ nothing
│ │ │ linf ┼ nothing
│ │ │ card ┼ nothing
│ │ │ scard ┼ nothing
│ │ │ ss ┼ nothing
│ │ │ xbgt ┼ Bool: false
│ │ │ sbgt ┼ nothing
│ │ │ gbgt ┼ nothing
│ │ │ ccnt ┼ nothing
│ │ │ cobj ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ nothing
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: AffExpr
│ │ ├ num_variables: 63
│ │ ├ num_constraints: 46
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ └ Vector{AffExpr} in MOI.ExponentialCone: 42
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :clog_delta_w, :clog_ret, :clog_risk, :clog_w, :csd_risk_soc_1, :k, :log_delta_w, :log_ret, :log_risk, :log_w, :lw, :noc_rk, :noc_rt, :obj_expr, :ret, :ret_1, :ret_vec, :risk, :risk_vec, :sc, :sd_risk_1, :so, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ StandardDeviation
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
w_min_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
w_opt_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
w_max_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
noc_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
fb ┴ nothing
5. Constrained near optimal centering
ConstrainedNearOptimalCentering asks the centred portfolio to meet every constraint of the problem, the linear, cardinality, turnover and other constraints you set on the optimiser as well as the bounds and budgets. It is the harder solve of the two, which is why section 2 passes seven solvers. This page sets no constraint beyond the default bounds and budget, so here both variants centre under the same bounds.
res_noc_c = optimise(NearOptimalCentering(; r = StandardDeviation(), obj = MaximumRatio(; rf = rf), opt = opt, alg = ConstrainedNearOptimalCentering()))NearOptimalCenteringResult
jr ┼ JuMPOptimisationResult
│ jor ┼ ResolvedJuMPOptimiser
│ │ pr ┼ LowOrderPrior
│ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ o_X ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ chol ┼ nothing
│ │ │ w ┼ nothing
│ │ │ ens ┼ nothing
│ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ kld ┼ nothing
│ │ │ ow ┼ nothing
│ │ │ rr ┼ nothing
│ │ │ fpr ┼ nothing
│ │ │ x_src ┼ nothing
│ │ │ ss_gaps ┼ nothing
│ │ │ pc ┴ nothing
│ │ fees ┼ nothing
│ │ ret ┼ ArithmeticReturn
│ │ │ settings ┼ JuMPReturnsSettings
│ │ │ │ scale ┼ Float64: 1.0
│ │ │ │ lb ┼ nothing
│ │ │ │ rte ┼ Bool: true
│ │ │ │ fee ┼ Bool: true
│ │ │ │ mic ┴ Bool: true
│ │ │ ucs ┼ nothing
│ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ mtx_sqrt ┴ EigenFallbackSquareRoot()
│ │ sca ┼ nothing
│ │ imsk ┼ nothing
│ │ cbr ┼ ResolvedConstraintBlock
│ │ │ pr ┼ LowOrderPrior
│ │ │ │ X ┼ 252×20 Matrix{Float64}
│ │ │ │ o_X ┼ nothing
│ │ │ │ mu ┼ 20-element Vector{Float64}
│ │ │ │ sigma ┼ 20×20 Matrix{Float64}
│ │ │ │ chol ┼ nothing
│ │ │ │ w ┼ nothing
│ │ │ │ ens ┼ nothing
│ │ │ │ eoc ┼ Tuple{Nothing, Nothing}: (nothing, nothing)
│ │ │ │ kld ┼ nothing
│ │ │ │ ow ┼ nothing
│ │ │ │ rr ┼ nothing
│ │ │ │ fpr ┼ nothing
│ │ │ │ x_src ┼ nothing
│ │ │ │ ss_gaps ┼ nothing
│ │ │ │ pc ┴ nothing
│ │ │ rd ┼ ReturnsResult
│ │ │ │ nx ┼ nothing
│ │ │ │ X ┼ nothing
│ │ │ │ nf ┼ nothing
│ │ │ │ F ┼ nothing
│ │ │ │ nb ┼ nothing
│ │ │ │ B ┼ nothing
│ │ │ │ ne ┼ nothing
│ │ │ │ E ┼ nothing
│ │ │ │ ts ┼ nothing
│ │ │ │ iv ┼ nothing
│ │ │ │ ivpa ┼ nothing
│ │ │ │ pnl ┴ nothing
│ │ │ wb ┼ WeightBounds
│ │ │ │ lb ┼ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ │ ub ┴ 20-element StepRangeLen{Float64, Base.TwicePrecision{Float64}, Base.TwicePrecision{Float64}, Int64}
│ │ │ lt ┼ nothing
│ │ │ st ┼ nothing
│ │ │ lcsr ┼ nothing
│ │ │ ctr ┼ nothing
│ │ │ gcardr ┼ nothing
│ │ │ sgcardr ┼ nothing
│ │ │ smtx ┼ nothing
│ │ │ sgmtx ┼ nothing
│ │ │ slt ┼ nothing
│ │ │ sst ┼ nothing
│ │ │ sglt ┼ nothing
│ │ │ sgst ┼ nothing
│ │ │ tn ┼ nothing
│ │ │ plr ┼ nothing
│ │ │ l2c ┼ nothing
│ │ │ lpc ┼ nothing
│ │ │ linfc ┼ nothing
│ │ │ l1 ┼ nothing
│ │ │ l2 ┼ nothing
│ │ │ lp ┼ nothing
│ │ │ linf ┼ nothing
│ │ │ card ┼ nothing
│ │ │ scard ┼ nothing
│ │ │ ss ┼ nothing
│ │ │ xbgt ┼ Bool: false
│ │ │ sbgt ┼ nothing
│ │ │ gbgt ┼ nothing
│ │ │ ccnt ┼ nothing
│ │ │ cobj ┴ nothing
│ retcode ┼ OptimisationSuccess
│ │ res ┴ nothing
│ sol ┼ JuMPOptimisationSolution
│ │ w ┴ 20-element Vector{Float64}
│ model ┼ A JuMP Model
│ │ ├ solver: Clarabel
│ │ ├ objective_sense: MIN_SENSE
│ │ │ └ objective_function_type: AffExpr
│ │ ├ num_variables: 63
│ │ ├ num_constraints: 46
│ │ │ ├ AffExpr in MOI.EqualTo{Float64}: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonnegatives: 1
│ │ │ ├ Vector{AffExpr} in MOI.Nonpositives: 1
│ │ │ ├ Vector{AffExpr} in MOI.SecondOrderCone: 1
│ │ │ └ Vector{AffExpr} in MOI.ExponentialCone: 42
│ │ └ Names registered in the model
│ │ └ :G, :T, :bgt, :clog_delta_w, :clog_ret, :clog_risk, :clog_w, :csd_risk_soc_1, :k, :log_delta_w, :log_ret, :log_risk, :log_w, :lw, :noc_rk, :noc_rt, :obj_expr, :ret, :ret_1, :ret_vec, :risk, :risk_minimised, :risk_vec, :sc, :sd_risk_1, :so, :w, :w_gross_ub, :w_lb, :w_ub
r ┼ StandardDeviation
│ settings ┼ RiskMeasureSettings
│ │ scale ┼ Float64: 1.0
│ │ ub ┼ nothing
│ │ rke ┴ Bool: true
│ sigma ┼ 20×20 Matrix{Float64}
│ chol ┼ nothing
│ mtx_sqrt ┴ EigenFallbackSquareRoot()
w_min_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
w_opt_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
w_max_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
noc_retcode ┼ OptimisationSuccess
│ res ┴ Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}: Dict{Union{AbstractString, Symbol}, AbstractDict{Symbol}}()
fb ┴ nothing
6. Comparing the allocations
Read the three weight columns against each other.
pretty_table(DataFrame(; :assets => rd.nx, Symbol("MaxRatio (extreme)") => res_mr.w, Symbol("NOC unconstrained") => res_noc_u.w, Symbol("NOC constrained") => res_noc_c.w); formatters = [resfmt])┌────────┬────────────────────┬───────────────────┬─────────────────┐
│ assets │ MaxRatio (extreme) │ NOC unconstrained │ NOC constrained │
│ String │ Float64 │ Float64 │ Float64 │
├────────┼────────────────────┼───────────────────┼─────────────────┤
│ AAPL │ 0.0 % │ 0.463 % │ 0.463 % │
│ AMD │ 0.0 % │ 0.281 % │ 0.281 % │
│ BAC │ 0.0 % │ 0.505 % │ 0.505 % │
│ BBY │ 0.0 % │ 0.684 % │ 0.684 % │
│ CVX │ 0.0 % │ 2.785 % │ 2.785 % │
│ GE │ 0.0 % │ 0.622 % │ 0.622 % │
│ HD │ 0.0 % │ 0.606 % │ 0.606 % │
│ JNJ │ 0.0 % │ 1.206 % │ 1.206 % │
│ JPM │ 0.0 % │ 0.645 % │ 0.645 % │
│ KO │ 0.0 % │ 1.377 % │ 1.377 % │
│ LLY │ 0.0 % │ 3.216 % │ 3.216 % │
│ MRK │ 66.038 % │ 38.422 % │ 38.422 % │
│ MSFT │ 0.0 % │ 0.468 % │ 0.468 % │
│ PEP │ 0.0 % │ 1.256 % │ 1.256 % │
│ PFE │ 0.0 % │ 0.71 % │ 0.71 % │
│ PG │ 0.0 % │ 0.925 % │ 0.925 % │
│ RRC │ 0.0 % │ 1.324 % │ 1.324 % │
│ UNH │ 0.0 % │ 1.064 % │ 1.064 % │
│ WMT │ 0.0 % │ 1.044 % │ 1.044 % │
│ XOM │ 33.961 % │ 42.397 % │ 42.397 % │
└────────┴────────────────────┴───────────────────┴─────────────────┘We print two numbers per portfolio, the largest single weight and the number of assets whose weight is above 0.01%.
summarise(w) = (round(maximum(w) * 100; digits = 2), count(>(1e-4), w))pretty_table(DataFrame(; :portfolio => ["MaxRatio (extreme)", "NOC unconstrained", "NOC constrained"], Symbol("max weight %") => [summarise(res_mr.w)[1], summarise(res_noc_u.w)[1], summarise(res_noc_c.w)[1]], Symbol("assets held") => [summarise(res_mr.w)[2], summarise(res_noc_u.w)[2], summarise(res_noc_c.w)[2]]))┌────────────────────┬──────────────┬─────────────┐
│ portfolio │ max weight % │ assets held │
│ String │ Float64 │ Int64 │
├────────────────────┼──────────────┼─────────────┤
│ MaxRatio (extreme) │ 66.04 │ 2 │
│ NOC unconstrained │ 42.4 │ 20 │
│ NOC constrained │ 42.4 │ 20 │
└────────────────────┴──────────────┴─────────────┘The extreme maximum-ratio portfolio holds far fewer assets than either NOC portfolio, and its largest weight is larger. The centre of the near-optimal region lies away from the corner that the extreme point occupies.
7. Visualising the compositions
The plot stacks the three allocations, with the extreme portfolio first.
using StatsPlotsplot_stacked_bar_composition([res_mr, res_noc_u, res_noc_c], rd)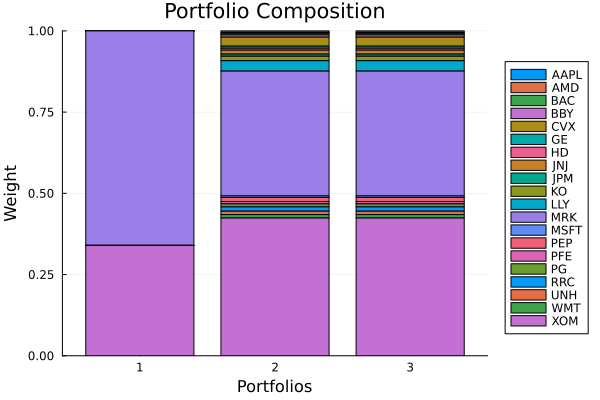
This page was generated using Literate.jl.