The source files can be found in user_guide/.
Data and priors
The first pipeline stage turns raw prices into a prior — the expected-returns vector and covariance matrix every optimiser consumes. Two calls cover the common path: prices_to_returns and prior. This page is the quick tour; for the full menu of moment estimators and view-based priors, see the moments & priors examples.
using PortfolioOptimisers, CSV, TimeSeries, DataFrames, PrettyTables, LinearAlgebra, StatsPlots, GraphRecipesresfmt = (v, i, j) -> begin return if j == 1 v else isa(v, AbstractFloat) ? "$(round(v*100, digits=3)) %" : v endend;1. Prices to returns
Price data usually arrives from an API and must be converted to returns. prices_to_returns handles asset, factor, and benchmark prices (plus implied volatilities and volatility premiums), validates that the series are consistent, and can collapse to lower frequencies (TimeSeries.jl). Given a single TimeArray of prices it returns a ReturnsResult holding the asset names nx and the return matrix X.
Real price tables are rarely clean — newly listed or delisted names leave leading/trailing gaps, halts and stale quotes leave flat stretches, and exchanges keep different holiday calendars. price_ingestion reads each asset's Listing Span off the panel and the conversion carries every gap into the returns, handing back an AssetPanel that says which assets are estimable when; filling a gap is PriceGapFill's and deleting one is MissingDataFilter's. The Data preprocessing and the ingestion layer example is the deep dive.
X = TimeArray(CSV.File(joinpath(@__DIR__, "../examples/SP500.csv.gz")); timestamp = :Date)[(end - 252):end]rd = prices_to_returns(X)ReturnsResult
nx ┼ 20-element Vector{String}
X ┼ 252×20 Matrix{Float64}
nf ┼ nothing
F ┼ nothing
nb ┼ nothing
B ┼ nothing
ts ┼ 252-element Vector{Date}
iv ┼ nothing
ivpa ┼ nothing
pnl ┼ AssetPanel
│ pf ┼ Vector{AbstractPanelField}: AbstractPanelField[]
│ amsk ┼ 252×20 AllTrueMask
│ emsk ┴ 252×20 AllTrueMask
That one call is the layer's own path: prices_to_returns(X) on a bare price table is prices_to_returns(price_ingestion(PriceIngestion(), X)). Write the two steps when you hold more than one table — price_ingestion takes factor and benchmark price series as F and B, aligns them onto the asset clock, and the conversion carries the factor returns F and the benchmark returns B through on the same ReturnsResult, so everything downstream has the data it needs. The point-in-time universe takes a gapped table through that path to a walk-forward.
2. Returns to a prior
prior applies a prior estimator to a ReturnsResult and returns the moments. The blessed default is EmpiricalPrior — the sample mean and covariance.
pr = prior(EmpiricalPrior(), rd)pretty_table(DataFrame("Asset" => rd.nx, "Expected return" => pr.mu, "Volatility" => sqrt.(diag(pr.sigma))); formatters = [resfmt], title = "Empirical prior: per-asset mean and volatility")Empirical prior: per-asset mean and volatility
┌────────┬─────────────────┬────────────┐
│ Asset │ Expected return │ Volatility │
│ String │ Float64 │ Float64 │
├────────┼─────────────────┼────────────┤
│ AAPL │ -0.113 % │ 2.237 % │
│ AMD │ -0.281 % │ 3.84 % │
│ BAC │ -0.093 % │ 2.04 % │
│ BBY │ -0.028 % │ 2.85 % │
│ CVX │ 0.195 % │ 2.07 % │
│ GE │ -0.034 % │ 2.192 % │
│ HD │ -0.071 % │ 1.968 % │
│ JNJ │ 0.031 % │ 1.096 % │
│ JPM │ -0.042 % │ 1.877 % │
│ KO │ 0.05 % │ 1.237 % │
│ LLY │ 0.131 % │ 1.714 % │
│ MRK │ 0.167 % │ 1.254 % │
│ MSFT │ -0.121 % │ 2.214 % │
│ PEP │ 0.039 % │ 1.223 % │
│ PFE │ -0.026 % │ 1.698 % │
│ PG │ -0.008 % │ 1.382 % │
│ RRC │ 0.182 % │ 3.957 % │
│ UNH │ 0.036 % │ 1.533 % │
│ WMT │ 0.016 % │ 1.681 % │
│ XOM │ 0.264 % │ 2.207 % │
└────────┴─────────────────┴────────────┘3. Swapping the prior
EmpiricalPrior is only the starting point. Every prior estimator has the same prior(pe, rd) interface, so swapping one in is a one-line change. The common alternatives:
FactorPrior— moments from a factor model (deep dive: Factor Priors).BlackLittermanPrior— blend market-equilibrium moments with your views (deep dive: Black–Litterman). The family extends toBayesianBlackLittermanPrior,FactorBlackLittermanPrior(views on factor premia) andAugmentedBlackLittermanPrior(asset and factor views together) — see Advanced Black–Litterman.EntropyPoolingPrior/OpinionPoolingPrior— reweight the empirical scenarios to satisfy views on any moment (deep dives: Entropy Pooling, Opinion Pooling).CrossSectionalFactorPrior— moments from a factor model fitted across the assets rather than through time: at each date it regresses that date's returns on the assets' lagged per-asset exposures, so it needs no factor return series of its own and admits a universe whose membership changes.
A cross-sectional fit asks more of the caller than the others. It reads no F; it reads an AssetPanel of per-asset Panel Fields — a market capitalisation, a book equity, an industry label — carried on the returns result as rd.pnl, and the caller names the Descriptors and Exposure Estimators that turn those fields into factors, one Pair per factor. The deep dive is Cross-sectional factor model, end to end, and Cross-sectional factor model through a Pipeline reaches the same weights through a Pipeline.
The covariance estimator inside a prior is itself swappable (shrinkage, denoising, Gerber, …); see Covariance Estimation. Any moment estimator can also be windowed — restricted to a trailing window or recency-weighted — when the recent regime is more informative than the full sample (deep dive: Windowed Estimators; regime-adjusted estimators are a related sibling).
4. A first look at the data
plot_prior summarises a prior in one figure — expected returns, per-asset volatility, and the correlation matrix — a quick sanity check before optimising.
plot_prior(pr, rd)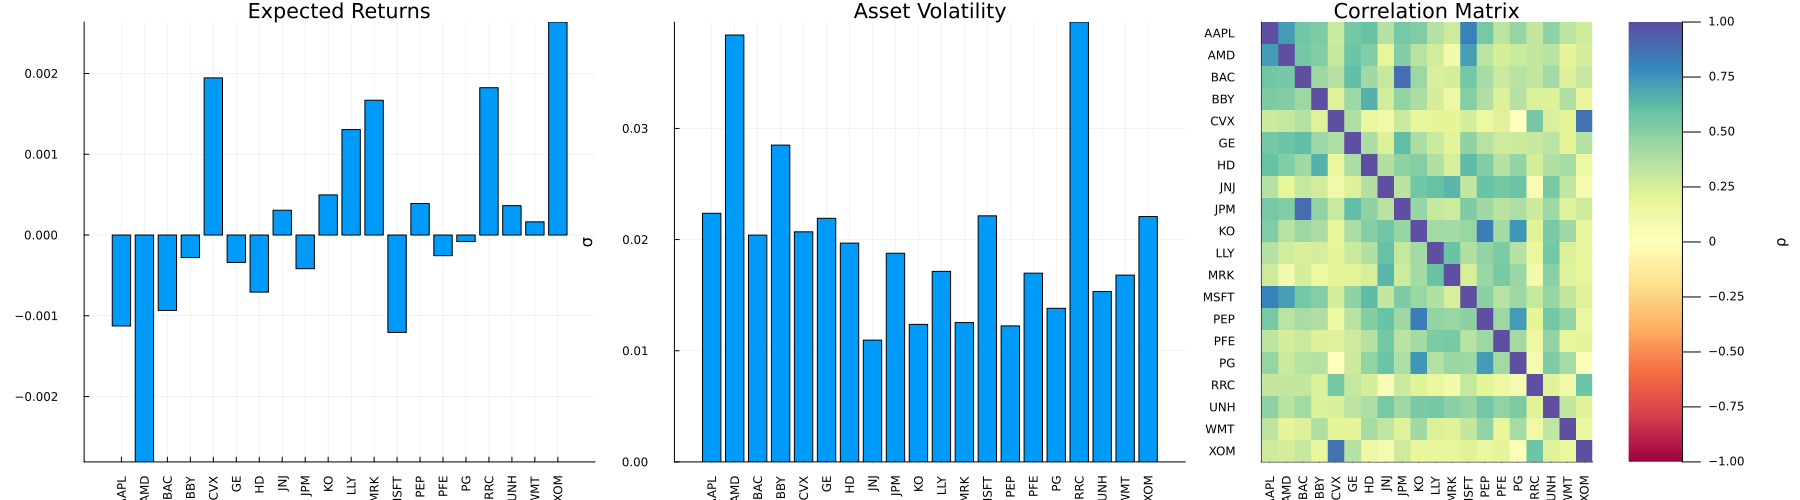
This page was generated using Literate.jl.